stefanocarrera/autophagycode_D_he_train-mercury_Qwen3-4B_strategy_trust_t1.25_g4_run0_metrics
收藏资源简介:
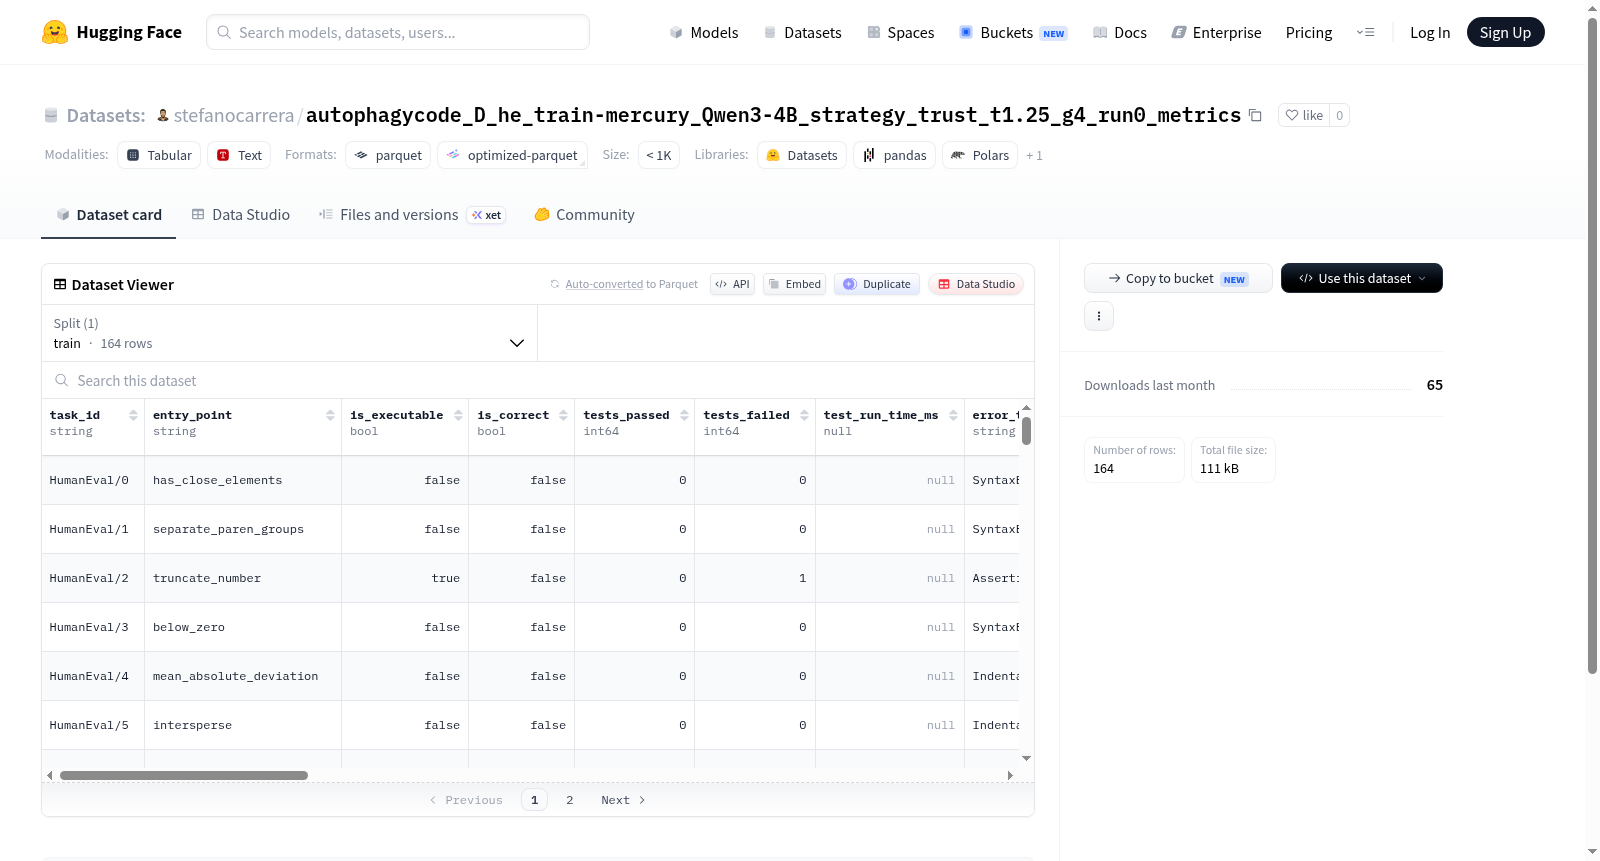
该数据集包含来自代码问题求解任务(如HumanEval)的样本,每个样本包括任务ID、入口函数名、代码是否可执行、是否正确、通过的测试数、失败的测试数、测试运行时间、错误类型、以及多种代码复杂度指标(如Halstead指标、圈复杂度、可维护性指数、代码行数、注释百分比等)和预测熵特征。数据集共164个训练样本,可用于分析代码质量、复杂度与正确性之间的关系。
This dataset contains samples from code problem-solving tasks (e.g., HumanEval), each including task ID, entry point function name, whether the code is executable, whether it is correct, number of tests passed, number of tests failed, test run time, error type, and various code complexity metrics (such as Halstead metrics, cyclomatic complexity, maintainability index, lines of code, comment percentage, etc.) and predictive entropy features. The dataset has 164 training samples and can be used to analyze the relationship between code quality, complexity, and correctness.