microsoft/ms_marco
收藏资源简介:
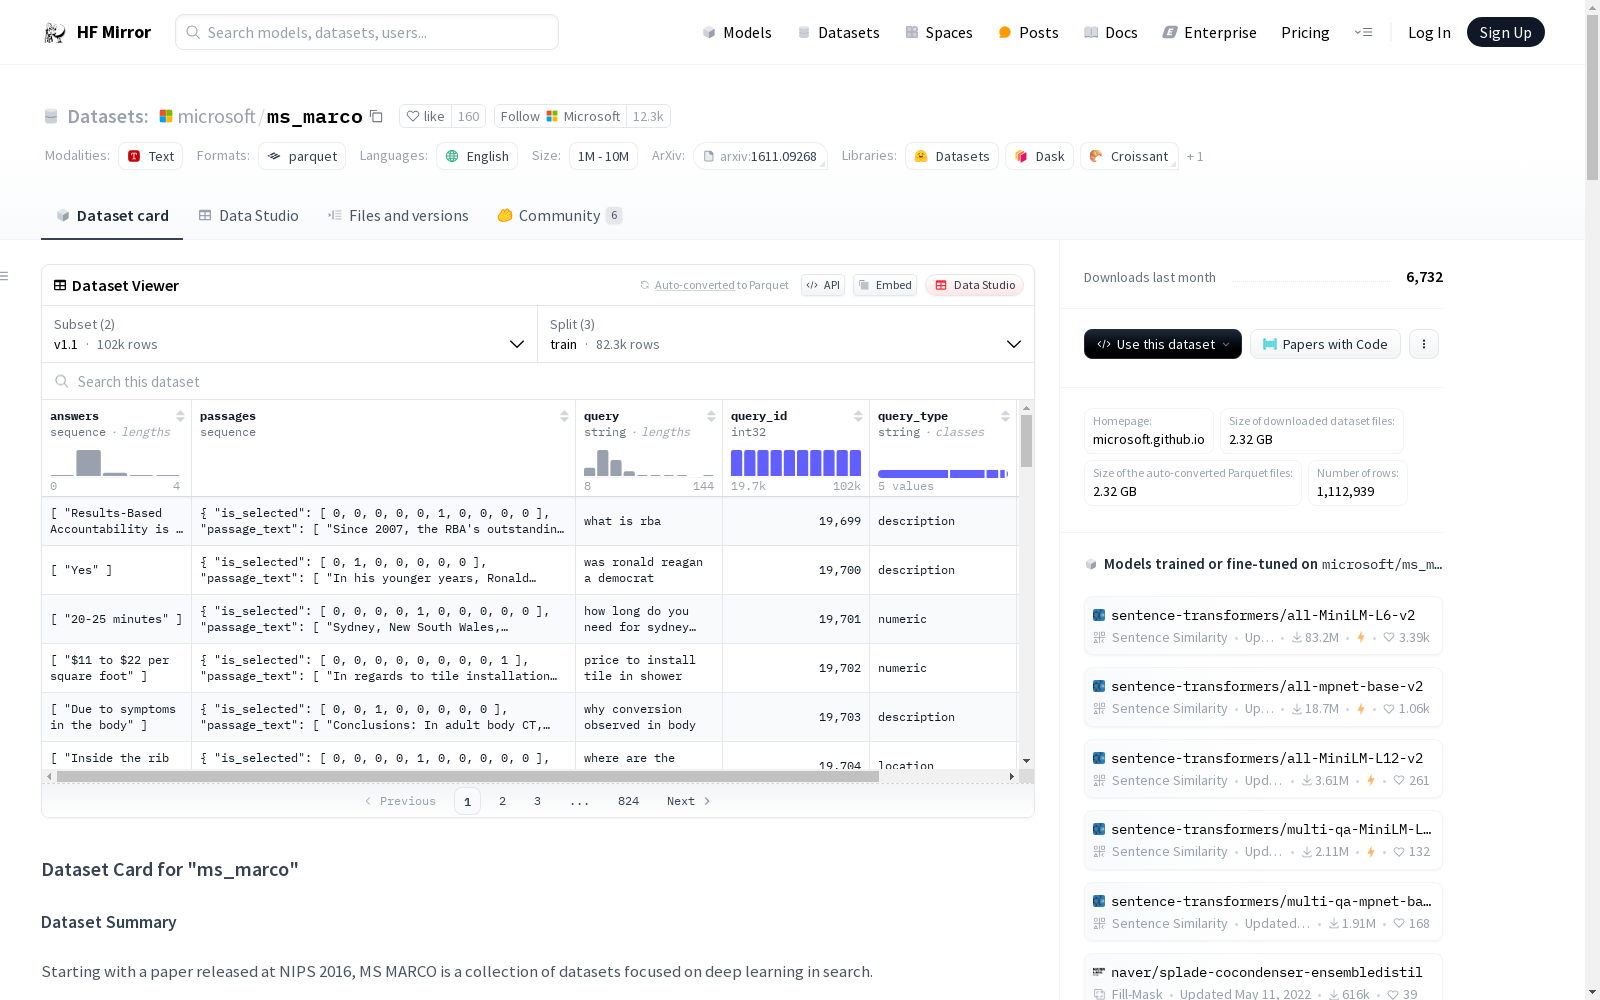
MS MARCO数据集是一个专注于深度学习在搜索领域应用的数据集集合。最初的数据集是一个包含100,000个真实Bing问题和人工生成答案的问答数据集。随后,数据集扩展到了包含1,000,000个问题的数据集,以及自然语言生成、段落排序、关键词提取、爬虫和对话搜索等多个数据集。数据集分为三个任务/形式:原始问答数据集(v1.1)、问答(v2.1)和自然语言生成(v2.1)。v1.1版本包含100,000个示例,而v2.1版本则包含超过1,000,000个查询,并且质量更高。自然语言生成数据集包含180,000个示例,旨在提供可以被智能音箱朗读的答案。
MS MARCO Dataset is a collection of datasets focused on the application of deep learning in the search domain. The original dataset was a question answering (QA) dataset containing 100,000 real Bing queries and human-generated answers. Subsequently, the dataset collection expanded to include a dataset with 1,000,000 queries, as well as multiple datasets covering natural language generation (NLG), passage ranking, keyword extraction, web crawling, and conversational search. The dataset collection is divided into three task/formats: the original QA dataset (v1.1), QA (v2.1), and natural language generation (v2.1). The v1.1 version contains 100,000 examples, while the v2.1 version includes over 1,000,000 queries with higher quality. The natural language generation dataset consists of 180,000 examples, designed to produce answers that can be read aloud by smart speakers.
Microsoft Machine Reading Comprehension Dataset (MS MARCO) 数据集概述
数据集配置
v1.1
- 特征:
answers: 字符串序列passages: 字典特征,包含:is_selected: 32位整数passage_text: 字符串url: 字符串
query: 字符串query_id: 32位整数query_type: 字符串wellFormedAnswers: 字符串序列
- 数据分割:
validation: 42665198 字节, 10047 样本train: 350516260 字节, 82326 样本test: 40977580 字节, 9650 样本
- 下载大小: 217328153 字节
- 数据集大小: 434159038 字节
v2.1
- 特征:
answers: 字符串序列passages: 字典特征,包含:is_selected: 32位整数passage_text: 字符串url: 字符串
query: 字符串query_id: 32位整数query_type: 字符串wellFormedAnswers: 字符串序列
- 数据分割:
validation: 413765365 字节, 101093 样本train: 3462807709 字节, 808731 样本test: 405691932 字节, 101092 样本
- 下载大小: 2105722550 字节
- 数据集大小: 4282265006 字节
数据集文件配置
v1.1
- 验证集:
v1.1/validation-* - 训练集:
v1.1/train-* - 测试集:
v1.1/test-*
v2.1
- 验证集:
v2.1/validation-* - 训练集:
v2.1/train-* - 测试集:
v2.1/test-*