korean-ai-prompt-style-dataset
收藏资源简介:
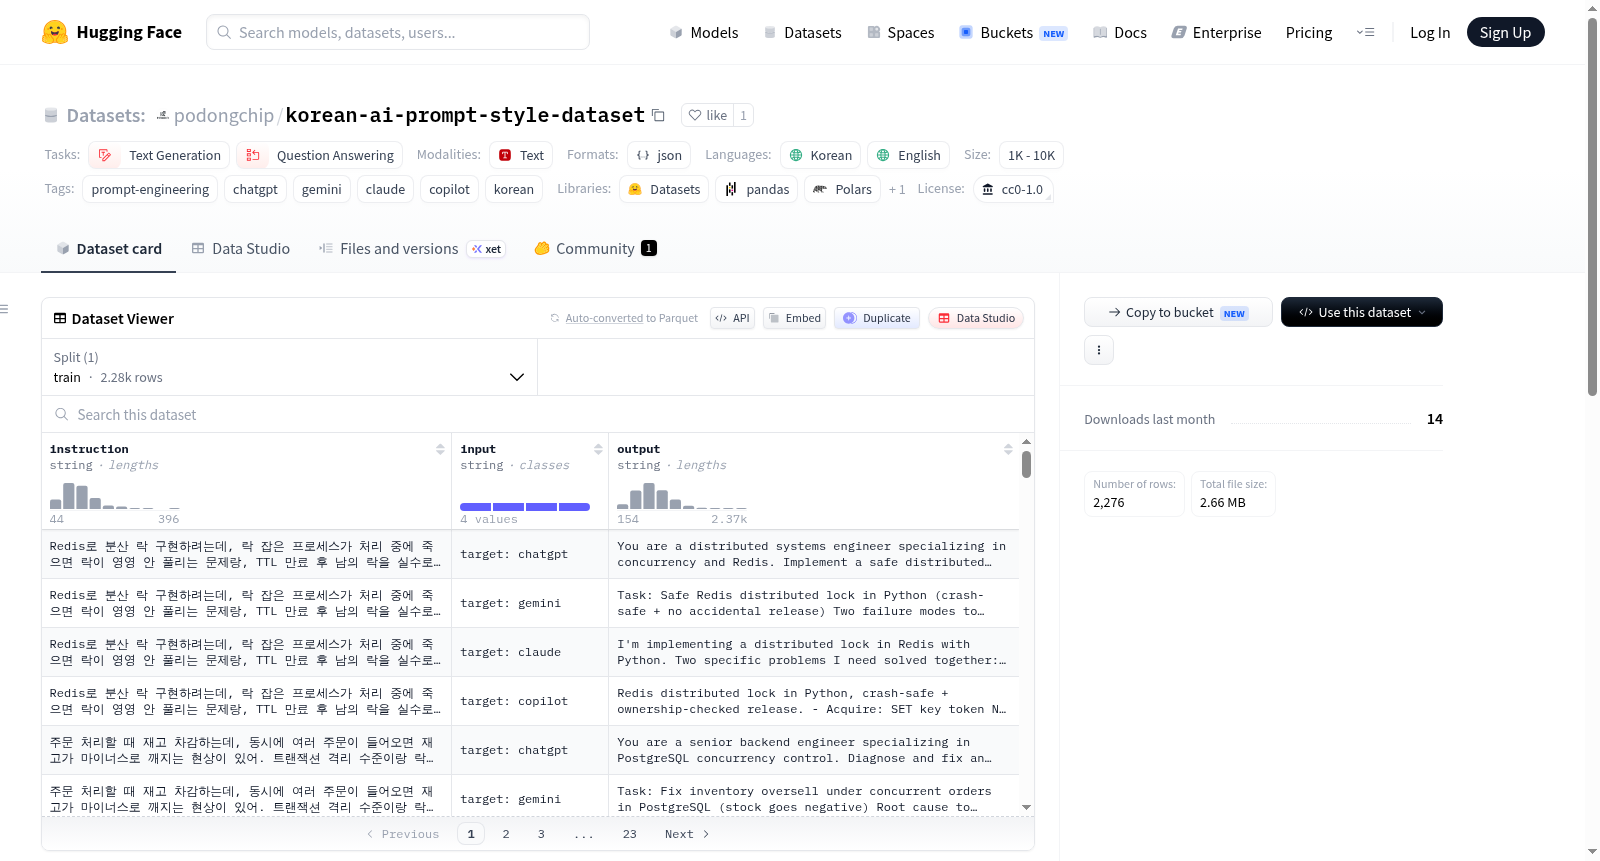
Korean AI Prompt Style Dataset 是一个韩语数据集,旨在比较和展示针对不同大型语言模型优化的提示(prompt)风格。该数据集围绕相同的用户问题或指令,为四个主流AI模型(ChatGPT、Gemini、Claude、Copilot)分别提供了经过优化的提示文本。数据集包含869个样本,每个样本由三个字段构成:instruction字段表示用户提出的原始问题或任务;input字段指定该条提示所针对的目标AI模型(chatgpt、gemini、claude或copilot之一);output字段则是对应目标模型的最优提示文本。数据主题多样,涵盖后端开发、数据库、安全等多个技术领域。该数据集主要用于研究不同大语言模型(LLM)在提示风格上的差异与偏好,也可作为微调语言模型或进行提示工程教学与学习的资源。数据集采用CC0 1.0通用公共领域贡献许可协议,主要语言为韩语,同时包含英语元素。
Korean AI Prompt Style Dataset is a Korean language dataset designed to compare and showcase prompt styles optimized for different large language models. It provides optimized prompt texts for four mainstream AI models (ChatGPT, Gemini, Claude, Copilot) based on the same user questions or instructions. The dataset contains 869 samples, each consisting of three fields: the instruction field represents the original user question or task; the input field specifies the target AI model for the prompt (one of chatgpt, gemini, claude, or copilot); and the output field is the optimal prompt text for the corresponding target model. The data covers diverse technical topics, including backend development, databases, security, and more. This dataset is primarily used for researching differences and preferences in prompt styles across different large language models (LLMs), and can also serve as a resource for fine-tuning language models or for teaching and learning prompt engineering. It is released under the CC0 1.0 Universal Public Domain Dedication license, with Korean as the main language and some English elements included.
数据集概述:Korean AI Prompt Style Dataset
- 许可证:CC0-1.0
- 语言:韩语(ko)、英语(en)
- 标签:提示工程、ChatGPT、Gemini、Claude、Copilot、韩语
- 任务类别:文本生成、问答
数据结构
每条样本包含三个字段:
instruction:用户问题(韩语)input:目标AI模型(chatgpt / gemini / claude / copilot)output:针对该AI优化后的提示词(韩语)
数据统计
- 总样本数:869条
- 覆盖AI模型:4个(ChatGPT、Gemini、Claude、Copilot)
- 主题范围:后端、数据库、安全等多个领域
用途
- 研究不同大语言模型间的提示风格差异
- 用于大语言模型的微调
- 作为提示工程教育材料