llama-nemotron-science-reasoning-on-canonical-think-full
收藏资源简介:
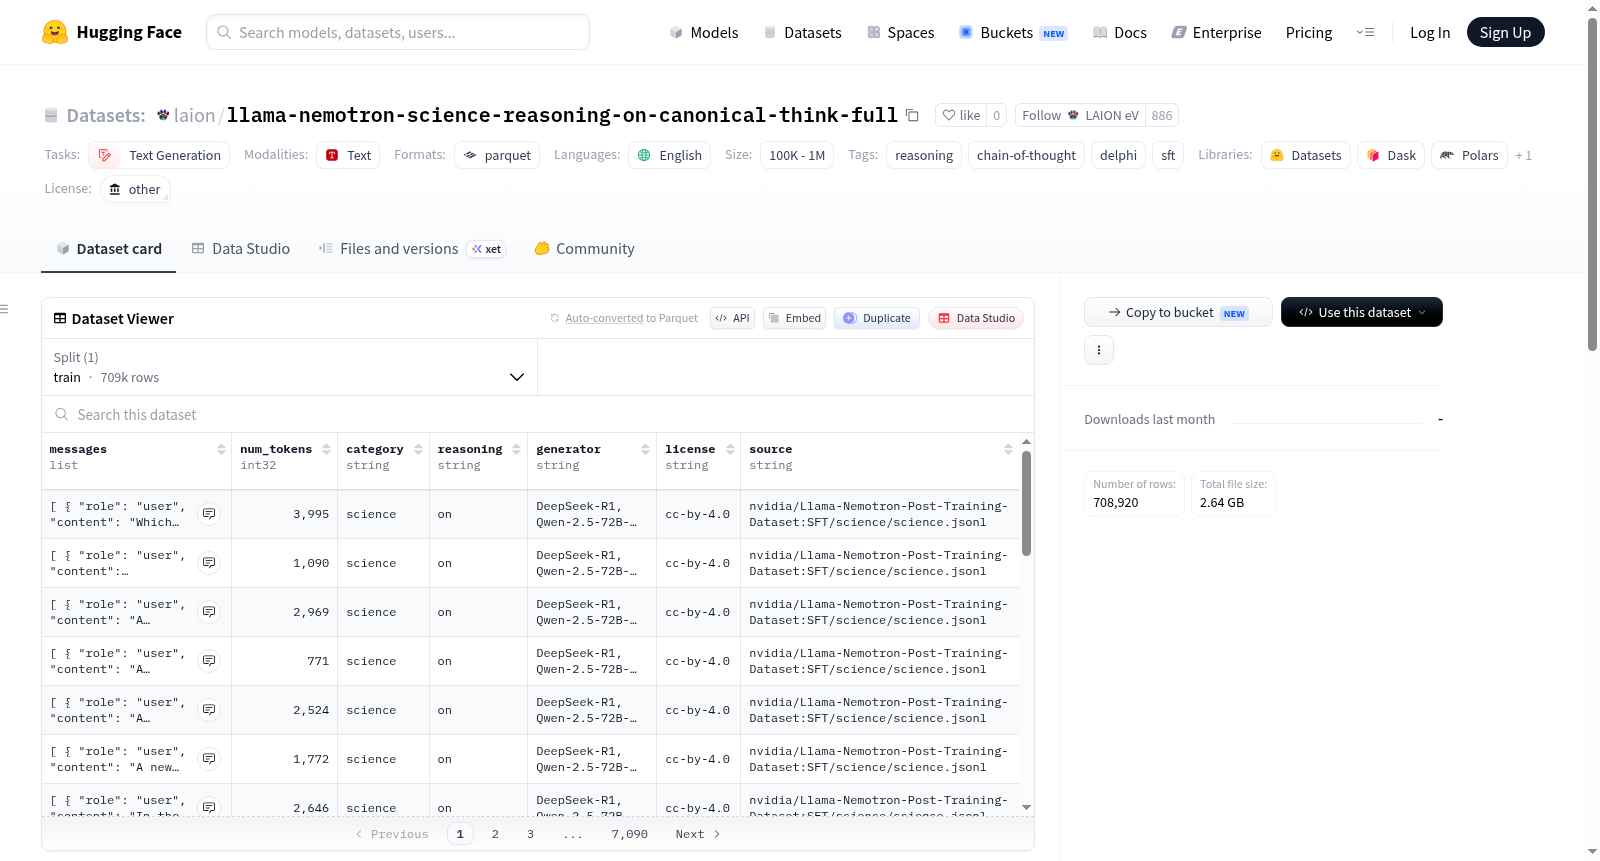
Llama-Nemotron科学推理数据集(Delphi规范思考格式)是一个专注于科学领域推理任务的文本生成数据集。该数据集派生自NVIDIA的Llama-Nemotron后训练数据集,专门提取了其中的SFT/science子集,并筛选出所有启用了推理(reasoning=="on")的样本,即包含详细思维链(长链式思考)的示例。数据集规模为708,920个样本,未应用任何长度限制或子采样。关键特征在于数据格式转换:原始数据中的思考标记(如`<think>...</think>`)被统一转换为规范的Delphi聊天模板格式(`<|start_think|>...<|end_think|>`),以兼容LLaMA-Factory的ReasoningTemplate.encode_oneturn方法。数据集采用ShareGPT格式组织,每个样本包含messages(角色-内容对话列表)、num_tokens(基于Delphi/Llama-3.1分词器的输入输出总长度)、category(固定为"science")、reasoning(固定为"on")、generator(生成模型信息)、license(许可证类型)和source(来源标识)等字段。该数据集适用于训练和评估具有推理能力的语言模型,特别是在科学领域的思维链生成任务中。数据许可证继承自源数据集,主要包括CC-BY-4.0和CC-BY-SA两种类型,生成模型涉及DeepSeek-R1系列。
The Llama-Nemotron Scientific Reasoning Dataset (Delphi Standard Thinking Format) is a text generation dataset focused on reasoning tasks in the scientific domain. It is derived from NVIDIAs Llama-Nemotron post-training dataset, specifically extracting the SFT/science subset and filtering all samples with reasoning enabled (reasoning=="on"), i.e., examples containing detailed chain-of-thought (long-chain thinking). The dataset size is 708,920 samples, with no length restrictions or subsampling applied. A key feature is the data format conversion: the original thinking tokens (e.g., `<think>...</think>`) are uniformly converted to the standard Delphi chat template format (`<|start_think|>...<|end_think|>`) to be compatible with the ReasoningTemplate.encode_oneturn method in LLaMA-Factory. The dataset is organized in ShareGPT format, with each sample containing fields such as messages (a list of role-content dialogues), num_tokens (total input-output length based on the Delphi/Llama-3.1 tokenizer), category (fixed as "science"), reasoning (fixed as "on"), generator (generation model information), license (license type), and source (source identifier). This dataset is suitable for training and evaluating language models with reasoning capabilities, particularly in chain-of-thought generation tasks in the scientific field. The data license is inherited from the source dataset, primarily including CC-BY-4.0 and CC-BY-SA types, and the generation models involve the DeepSeek-R1 series.
Llama-Nemotron Science Reasoning — Delphi Canonical-Think (完整版)
数据集概述
本数据集是 nvidia/Llama-Nemotron-Post-Training-Dataset 中 reasoning:on 的科学子集的完整版本,已转换为规范的 Delphi 聊天模板思考格式。包含 708,920 条数据。
与早期发布的冷启动热身切片(如 laion/llama-nemotron-science-reasoning-on-le3000tok-100k 及其 -canonical-think 变体)不同,本构建既不设置长度上限,也不进行子采样——所有长链式思维(long-CoT)科学样本均已包含。
数据处理说明
数据源自 nvidia/Llama-Nemotron-Post-Training-Dataset 中的 SFT/science/science.jsonl:
- 子集选择:仅使用
SFT/science部分。 - 推理启用:仅筛选
reasoning == "on"的样本,即长链式思维("详细思考")示例,每条数据均包含思考区域。 - 无长度过滤与子采样:早期版本设置了最多 3000 个 Delphi token 的上限并通过水库采样缩减至 10 万条;本版本取消了两项限制。
- 规范化 Delphi 思考标记:将每条助手指令中的内联
<think>...</think>改写为标准格式 `<|start_think|> ... <|end_think|>
+ 答案,字节级镜像了chat_templates/delphi_v0.jinja2中的推理提取逻辑。该格式符合 LLaMA-Factory 的ReasoningTemplate.encode_oneturn要求——该函数检测字面量<|start_think|>字符串,内联<think>会导致空思考目标,使得推理部分无法训练。若原始数据不含</think>`,则保留为纯答案。
数据格式
每条数据包含以下字段:
messages:ShareGPT 格式的[{role, content}]列表;助手内容以规范的<|start_think|>块开头(若原始数据包含<think>痕迹)。num_tokens:使用 Delphi / Llama-3.1 分词器(词汇表为marin-community/delphi-3e18-447Mparams-1.2Btokens)计算的原始输入 + 输出token 长度。可供下游过滤使用,但本数据集未依此进行过滤。category:固定为science。reasoning:固定为on。generator:生成模型来源,包括[DeepSeek-R1, DeepSeek-R1, Qwen-2.5-32B-Instruct, DeepSeek-R1, Qwen-2.5-72B-Instruct]。license:许可协议,包括[cc-by-4.0, cc-by-sa]。source:数据来源。
许可与归属
本数据集衍生自 NVIDIA 的 nvidia/Llama-Nemotron-Post-Training-Dataset。每条数据携带相应的许可协议(cc-by-4.0 或 cc-by-sa)。完整的许可条款请参考源数据集,本转换版本继承源数据集的许可。
标签信息
- 语言:英语 (
en) - 数据规模:100K < n < 1M(实际 708,920 条)
- 任务类别:文本生成 (
text-generation) - 标签:推理 (
reasoning)、链式思维 (chain-of-thought)、Delphi、监督微调 (sft)