eagle0504/multireward-grpo-fintech-customer-comms
收藏资源简介:
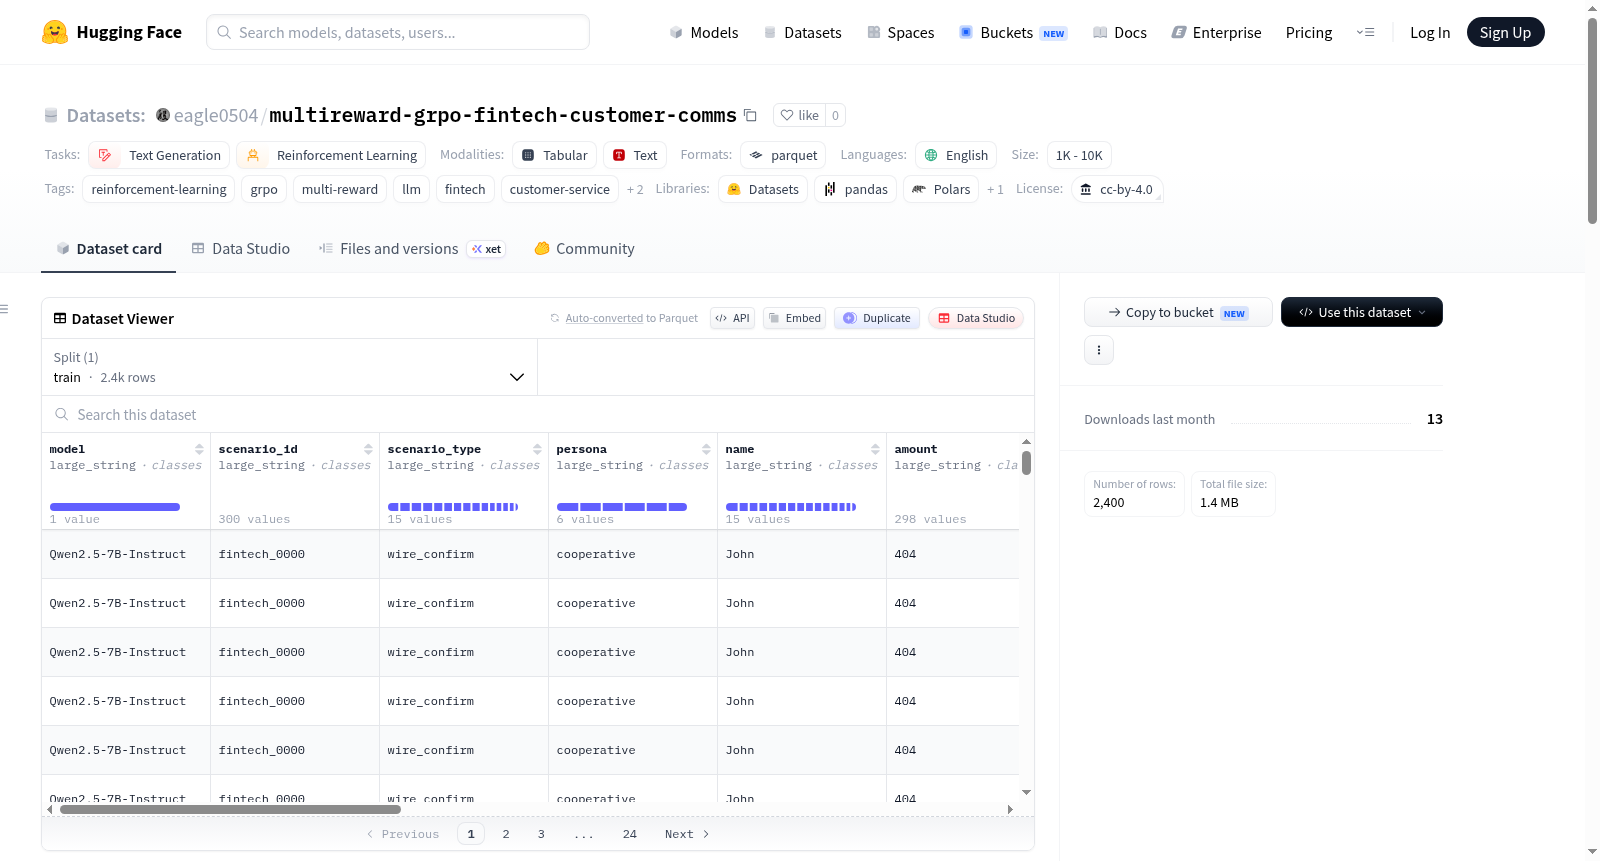
这是一个为虚构银行(Bank of XYZ)生成的合成多轮客户服务对话数据集,专门用于金融科技领域。每个对话包含多个并行采样的机器人回复,每个回复在三个可验证的奖励通道上评分:合规性(避免未经授权的费用减免、泄露账户详情等)、礼貌门控(基于合规性的同理心评分)和行动(以清晰下一步结束回复)。数据集设计用于强化学习中的多奖励GRPO(Group Relative Policy Optimization)结构,模拟真实生成分布,类似于GSM8K但侧重于合规性门控的多奖励塑造。数据集中包含15种场景类型(如账单提醒、退款请求、欺诈报告等)、6种用户角色(如合作型、焦虑型、沮丧型等),并随机化名称、金额和日期,以最大化多样性。数据集由Qwen2.5-7B-Instruct模型生成,无真实客户数据,适用于文本生成和强化学习任务。
Synthetic multi-turn customer-service conversations for a fictional bank (Bank of XYZ), generated for the empirical section of a research paper. Each conversation ends with m parallel sampled bot replies, each scored on three verifiable reward channels designed for fintech customer service: compliance (avoiding unauthorized fee waivers, account leaks, etc.), politeness_gated (empathy-based score conditioned on compliance), and action (ending with a clear next step). The dataset follows a multi-reward GRPO group structure on a real generation distribution, analogous to GSM8K but in a domain where multi-reward shaping matters most, particularly compliance gating for politeness/empathy. It includes 15 scenario types (e.g., billing reminder, refund request, fraud report), 6 user personas (e.g., cooperative, anxious, frustrated), and randomized elements like names and amounts. Generated using the Qwen2.5-7B-Instruct model, it contains no real customer data and is intended for text-generation and reinforcement-learning tasks.