EmoBench
收藏资源简介:
EmoBench是一个综合且具有挑战性的基准测试,旨在评估大型语言模型(LLMs)的情感智能(EI)。该数据集包含400个手工制作的英语和中文场景,分为两个关键评估任务:情感理解和情感应用。情感理解任务涉及识别复杂场景中的情感及其原因,而情感应用任务则涉及在情感困境中推荐有效的情感反应或行动。数据集基于心理学理论设计,支持双语场景,并包含需要推理和视角转换的复杂情感困境。数据集的高质量多标签注释通过严格的注释者间一致性验证(Fleiss' Kappa = 0.852)。
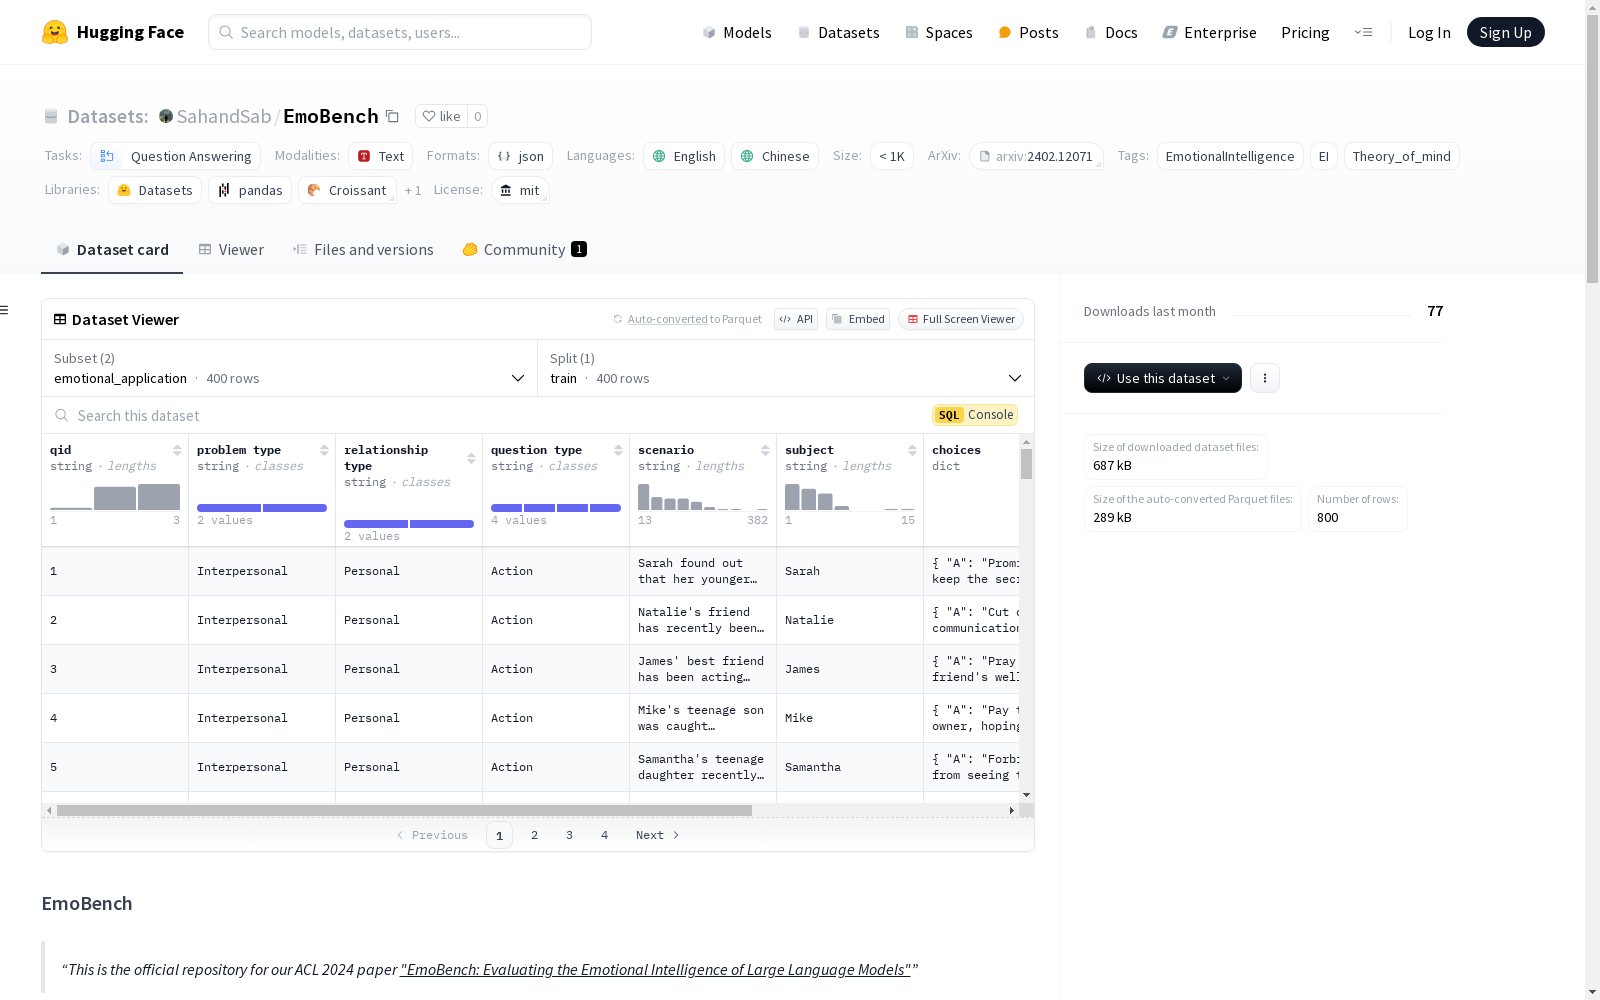
EmoBench is a comprehensive and challenging benchmark intended to evaluate the emotional intelligence (EI) of large language models (LLMs). This dataset contains 400 handcrafted English and Chinese scenarios, which are categorized into two core evaluation tasks: emotion understanding and emotion application. The emotion understanding task requires identifying emotions and their causes within complex scenarios, while the emotion application task focuses on recommending effective emotional responses or actions in emotional dilemmas. Designed based on psychological theories, the dataset supports bilingual scenarios and incorporates complex emotional dilemmas that necessitate reasoning and perspective-taking. Its high-quality multi-label annotations have been validated through strict inter-annotator agreement tests, with Fleiss' Kappa score reaching 0.852.
EmoBench 数据集概述
概述
EmoBench 是一个综合且具有挑战性的基准测试,旨在评估大型语言模型(LLMs)的情感智能(EI)。该数据集不仅关注情感识别,还涵盖了情感推理和应用等高级情感智能能力。
数据集结构
数据集包含 400 个手工制作的场景,分为两个主要评估任务:
- 情感理解 (Emotional Understanding, EU): 识别复杂场景中的情感及其原因。
- 情感应用 (Emotional Application, EA): 在情感冲突的情境中推荐有效的情感反应或行动。
关键特性
- 基于心理学的设计: 基于情感智能的既定理论(如 Salovey & Mayer, Goleman)。
- 双语支持: 场景提供英文和中文版本。
- 挑战性场景: 包含需要推理和视角转换的复杂情感困境。
- 高质量标注: 通过严格的标注者间一致性验证(Fleiss Kappa = 0.852)。
数据集详细结构
情感理解 (Emotional Understanding)
- 类别: 复杂情感、情感线索、个人信念和经历、视角转换。
- 示例:
- 场景: 经过一天的糟糕事件后,Sam 的车坏了,他开始歇斯底里地大笑。
- 任务: 识别情感(如悲伤、喜悦)及其原因。
情感应用 (Emotional Application)
- 类别: 根据关系类型(个人、社交)、问题类型(自我、他人)和问题类型(反应、行动)划分。
- 示例:
- 场景: Rebecca 的儿子输掉了足球比赛,感到沮丧并责备自己。
- 任务: 识别最有效的反应或行动。
评估
有关评估代码,请访问 GitHub 仓库。
引用
如果该数据集对您的研究有用,请引用以下论文:
@inproceedings{sabour-etal-2024-emobench, title = "{E}mo{B}ench: Evaluating the Emotional Intelligence of Large Language Models", author = "Sabour, Sahand and Liu, Siyang and Zhang, Zheyuan and Liu, June and Zhou, Jinfeng and Sunaryo, Alvionna and Lee, Tatia and Mihalcea, Rada and Huang, Minlie", editor = "Ku, Lun-Wei and Martins, Andre and Srikumar, Vivek", booktitle = "Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)", month = aug, year = "2024", address = "Bangkok, Thailand", publisher = "Association for Computational Linguistics", url = "https://aclanthology.org/2024.acl-long.326", doi = "10.18653/v1/2024.acl-long.326", pages = "5986--6004", abstract = "Recent advances in Large Language Models (LLMs) have highlighted the need for robust, comprehensive, and challenging benchmarks. Yet, research on evaluating their Emotional Intelligence (EI) is considerably limited. Existing benchmarks have two major shortcomings: first, they mainly focus on emotion recognition, neglecting essential EI capabilities such as emotion management and thought facilitation through emotion understanding; second, they are primarily constructed from existing datasets, which include frequent patterns, explicit information, and annotation errors, leading to unreliable evaluation. We propose EmoBench, a benchmark that draws upon established psychological theories and proposes a comprehensive definition for machine EI, including Emotional Understanding and Emotional Application. EmoBench includes a set of 400 hand-crafted questions in English and Chinese, which are meticulously designed to require thorough reasoning and understanding. Our findings reveal a considerable gap between the EI of existing LLMs and the average human, highlighting a promising direction for future research. Our code and data are publicly available at https://github.com/Sahandfer/EmoBench.", }