sphragis-metre
收藏资源简介:
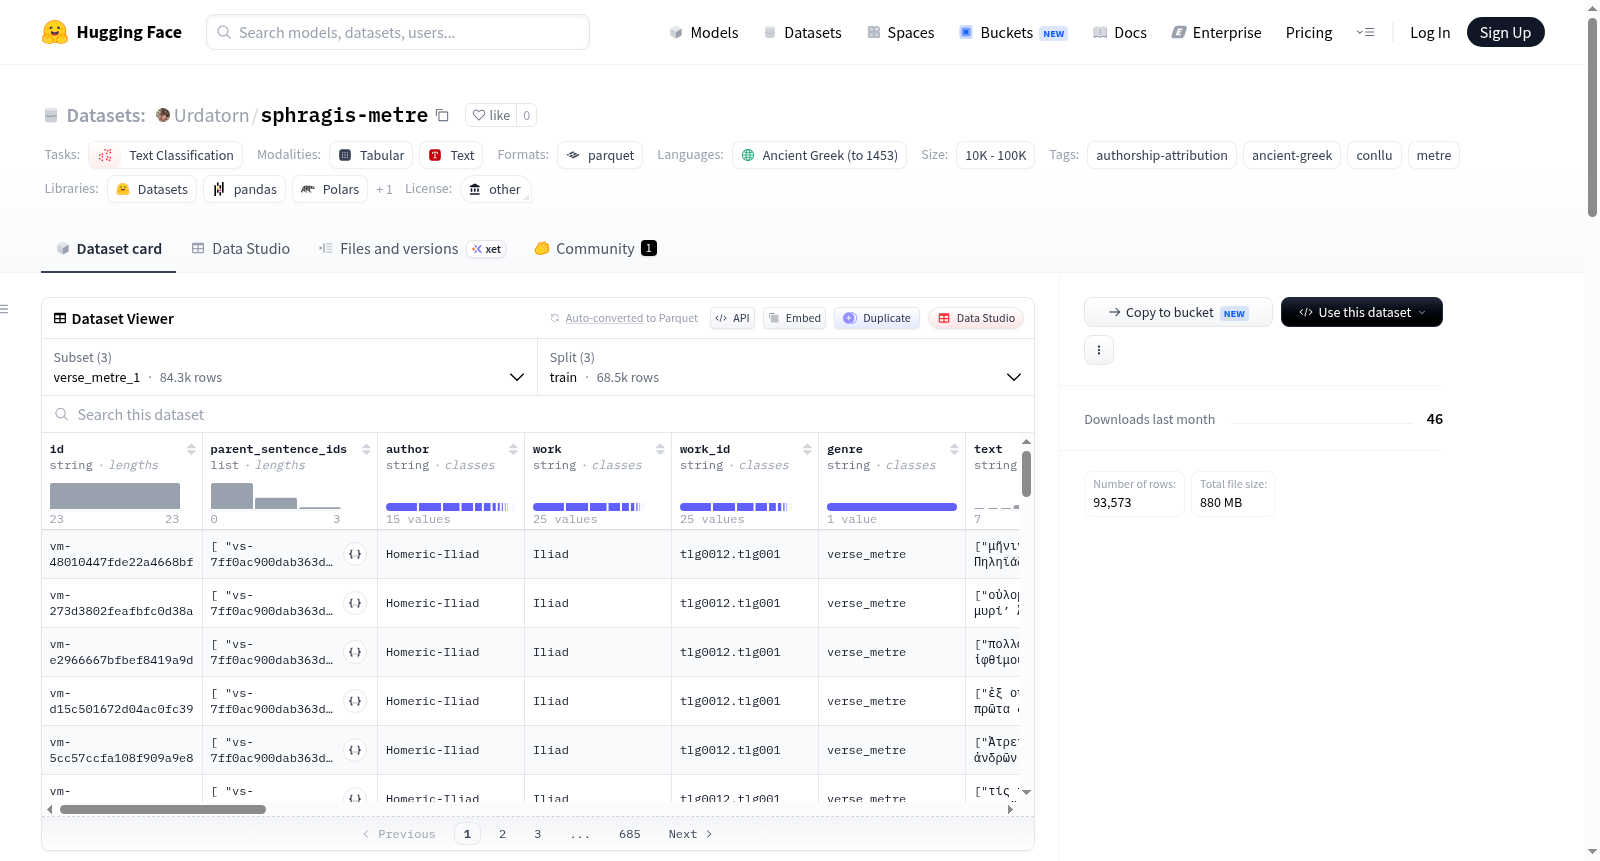
Sphragis Metre 是 Urdatorn/sphragis 数据集的扫描行版本,专为古希腊语作者归因任务设计。该数据集结合了人工韵律标注与依存句法标注,支持从精确的1行、10行和100行单元进行作者归属分析。数据涵盖15位古希腊诗人(包括埃斯库罗斯、阿波罗尼乌斯、阿拉图斯、卡利马科斯、赫西奥德、荷马(伊利亚特)、荷马(奥德赛)、吕科弗隆、尼坎德、诺努斯、奥皮安、品达、昆图斯·斯米纳乌斯、忒奥克里托斯、忒奥格尼斯),共计84,300行原子行,并按固定比例划分训练集(68,500行)、验证集(7,900行)和测试集(7,900行)。数据集提供三个配置:verse_metre_1(每行一个样本)、verse_metre_10(每10行一个块)、verse_metre_100(每100行一个块),所有配置共享相同的源行。每个样本包含文本(text)、CoNLL-U格式的依存句法分析(conllu)、韵律标注(metre)以及音节级人工标注(syllables)。句法标注部分来自黄金树库,部分由预训练模型预测,并标注了来源。数据集的构建过程保留了原始音节转录,并对所有结果进行了CoNLL 2018加载器验证。该数据集适用于文本分类任务,特别是古希腊诗歌的作者归因研究。
Sphragis Metre is a scanned line version of the Urdatorn/sphragis dataset, designed for authorship attribution of ancient Greek texts. It combines manual prosodic annotations with dependency syntactic annotations, supporting authorship analysis from precise units of 1 line, 10 lines, and 100 lines. The dataset covers 15 ancient Greek poets (including Aeschylus, Apollonius, Aratus, Callimachus, Hesiod, Homer (Iliad), Homer (Odyssey), Lycophron, Nicander, Nonnus, Oppian, Pindar, Quintus Smyrnaeus, Theocritus, Theognis), totaling 84,300 atomic lines, divided into training set (68,500 lines), validation set (7,900 lines), and test set (7,900 lines) with a fixed ratio. It provides three configurations: verse_metre_1 (one sample per line), verse_metre_10 (a block of 10 lines), and verse_metre_100 (a block of 100 lines), all sharing the same source lines. Each sample contains text, CoNLL-U format dependency parsing (conllu), prosodic annotation (metre), and syllable-level manual annotations (syllables). Part of the syntactic annotations come from a gold treebank, and part are predicted by a pre-trained model, with sources indicated. The construction process preserves the original syllable transcription, and all results are validated by the CoNLL 2018 loader. The dataset is suitable for text classification tasks, especially authorship attribution of ancient Greek poetry.
Sphragis Metre 数据集概述
基本信息
- 数据集名称:Sphragis Metre
- 语言:古希腊语(grc)
- 许可证:其他(other)
- 任务类别:文本分类(text-classification)
- 标签:作者归属(authorship-attribution)、古希腊语(ancient-greek)、CoNLL-U格式(conllu)、格律(metre)
数据集简介
Sphragis Metre 是 Urdatorn/sphragis 数据集的扫描行(scanned-line)配套版本,通过结合人工格律注释与依存注释,支持基于精确的1行、10行和100行单位的古希腊语作者归属研究。数据集保留了黄金树库(gold treebank)分析(在精确对齐允许的情况下),其余经过整理的 Hypotactic 段落则使用固定的 Ericu950/Stoicheia-tagger-parser 检查点进行解析。
配置与规模
| 配置 | 作者数 | 行单位 | 训练行数 | 验证行数 | 测试行数 |
|---|---|---|---|---|---|
verse_metre_1 |
15 | 扫描行 | 68,500 | 7,900 | 7,900 |
verse_metre_10 |
15 | 10行块 | 6,850 | 790 | 790 |
verse_metre_100 |
15 | 100行块 | 685 | 79 | 79 |
所有分割均固定在配置后缀上。_1、_10 和 _100 包含完全相同的源行总数;基于种子的余数移除由100行任务决定,并在各任务规模间复用。
作者标签与行数分布
15个保留标签为:Aeschylus、Apollonius Rhodius、Aratus、Callimachus、Hesiod、Homeric-Iliad、Homeric-Odyssey、Lycophron、Nicander、Nonnus、Oppian、Pindar、Quintus Smyrnaeus、Theocritus 和 Theognis。
| 诗人标签 | 训练 | 验证 | 测试 | 总计 |
|---|---|---|---|---|
| Aeschylus | 1,600 | 200 | 200 | 2,000 (2.4%) |
| Apollonius Rhodius | 4,600 | 500 | 500 | 5,600 (6.6%) |
| Aratus | 900 | 100 | 100 | 1,100 (1.3%) |
| Callimachus | 1,100 | 100 | 100 | 1,300 (1.5%) |
| Hesiod | 1,400 | 100 | 100 | 1,600 (1.9%) |
| Homeric-Iliad | 12,500 | 1,500 | 1,500 | 15,500 (18.4%) |
| Homeric-Odyssey | 9,600 | 1,200 | 1,200 | 12,000 (14.2%) |
| Lycophron | 1,100 | 100 | 100 | 1,300 (1.5%) |
| Nicander | 1,200 | 100 | 100 | 1,400 (1.7%) |
| Nonnus | 17,100 | 2,100 | 2,100 | 21,300 (25.3%) |
| Oppian | 4,500 | 500 | 500 | 5,500 (6.5%) |
| Pindar | 2,700 | 300 | 300 | 3,300 (3.9%) |
| Quintus Smyrnaeus | 7,000 | 800 | 800 | 8,600 (10.2%) |
| Theocritus | 2,100 | 200 | 200 | 2,500 (3.0%) |
| Theognis | 1,100 | 100 | 100 | 1,300 (1.5%) |
| 所有诗人 | 68,500 | 7,900 | 7,900 | 84,300 (100.0%) |
数据表示
text、conllu和metre是 JSON 列表,每个组成行对应一个元素。syllables是嵌套 JSON 列表:外层列表按相同顺序包含行,每个内层列表包含该行的音节。- 原子
_1行包含一个外层元素,而_10和_100保留10或100个可明确区分的行,而非扁平化音节。 - 每个黄金 CoNLL-U 单元被裁剪到对应的格律行。对于没有黄金树的段落,先跨连续格律行重建标点分隔的句子,并使用 Stoicheia 完整解析。每个句子树再裁剪回其组成行的边界。因此,行断点不会成为人为的解析器句子边界。
- 如果一行包含多个句子的内容,其单个 JSON
conllu单元按顺序包含这些有效的 CoNLL-U 句子块。上下文窗口回退分割(如有需要)仅发生在行之间。 - 所有结果均使用官方 CoNLL 2018 加载器验证。
syllables包含人工音节级格律注释。源 Hypotactic HTML 中音节后的字面空白保留为该音节features列表中的caesura成员;行末音节从不接收该标记。冗余的scansion字段未发布。- 源音节转录被保留而非静默纠正。14行保留行包含上游文本-音节转录不匹配;此审计计数记录在
metadata/build_report.json中。 syntax_annotation对于原子行为gold或predicted,对于块可能为mixed。treebank_source和source_records提供确切来源,对于预测行,固定 Stoicheia 修订版本cd8ae1658c364874c3b6f4df37bd1d46313e3cea。- 在共享100行瓶颈后,
_1包含28,183行黄金语法行和56,117行预测语法行。
使用注意事项
黄金和预测的依存分析在方法上不完全相同。当作者的黄金覆盖率不同时,使用 conllu 的模型可能学习到注释来源伪影。因此,结果应报告是否使用了语法;建议将仅格律/文本分析及按来源分层分析作为对照。
元数据与来源
模型面对的 CoNLL-U 注释和 MISC 字段不包含句子ID、CTS URN、源文件名、作者或作品标题。完整的审计溯源信息保留在专用元数据列中。源修订版本、分割清单、排除项和验证结果记录在 metadata/ 目录下。
加载方式
python from datasets import load_dataset
metre = load_dataset("Urdatorn/sphragis-metre", "verse_metre_10")