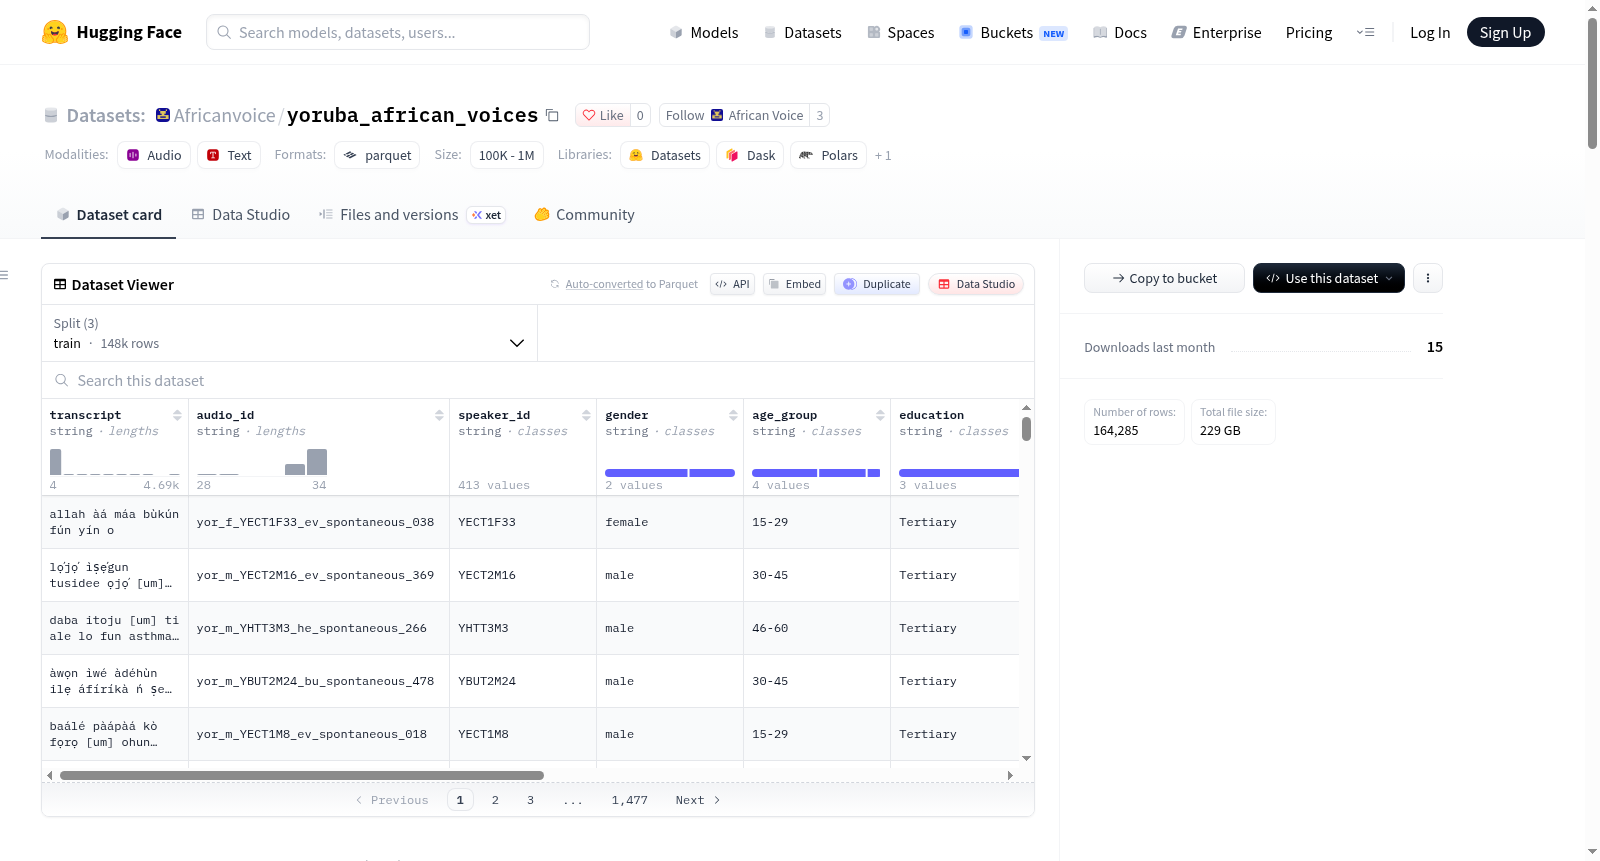
yoruba_african_voices
收藏资源简介:
WaZoBiaSpeech 是一个大规模、高质量、完全转录的约鲁巴语语音数据集,总时长超过500小时(509.56小时),包含171,651个音频片段,由714位说话人录制。数据集旨在加速非洲语境下的语音技术发展,促进语言多样性,支持低资源机器学习研究。数据通过道德、社区中心的方式收集,涵盖脚本化和非脚本化录音,并具有广泛的人口统计学覆盖。每个样本包含音频ID、说话人ID、48 kHz单声道WAV音频路径、干净的转录文本、音频时长(秒)、性别(男/女)、年龄组(15-29、30-45、46-60、60+)、教育水平(小学、中学、大学)、领域(如EV, HE, AG, BU)、录音类型(脚本化/非脚本化)、分割标签(train/dev/dev_test)和语言代码。数据集已按说话人独立分割:训练集147,686条,开发集7,717条,开发测试集8,882条。性别分布均衡(50.3%男性,49.7%女性)。该数据集适用于自动语音识别(ASR)训练、低资源非洲语言NLP、跨语言学习与迁移学习研究,以及多语言ASR系统评估。使用限制包括:严禁用于语音克隆、说话人识别、监视或任何依赖于识别或模仿个体的商业应用;区域口音变化可能不全面,非脚本化片段可能包含自然背景噪声。数据集采用Creative Commons Attribution 4.0 (CC BY 4.0)许可。
WaZoBiaSpeech is a large-scale, high-quality, fully transcribed Yoruba speech dataset with a total duration of over 500 hours (509.56 hours), containing 171,651 audio clips recorded by 714 speakers. The dataset aims to accelerate speech technology development in African contexts, promote linguistic diversity, and support low-resource machine learning research. Data is collected in an ethical, community-centered manner, covering scripted and unscripted recordings with broad demographic coverage. Each sample includes audio ID, speaker ID, 48 kHz mono WAV audio path, clean transcription text, audio duration (seconds), gender (male/female), age group (15-29, 30-45, 46-60, 60+), education level (primary, secondary, university), domain (e.g., EV, HE, AG, BU), recording type (scripted/unscripted), split label (train/dev/dev_test), and language code. The dataset is split independently by speaker: 147,686 in training set, 7,717 in development set, and 8,882 in development test set. Gender distribution is balanced (50.3% male, 49.7% female). This dataset is suitable for automatic speech recognition (ASR) training, low-resource African language NLP, cross-lingual and transfer learning research, and multilingual ASR system evaluation. Usage restrictions include: strictly prohibited for voice cloning, speaker identification, surveillance, or any commercial applications relying on identifying or mimicking individuals; regional accent variations may not be comprehensive, and unscripted clips may contain natural background noise. The dataset is licensed under Creative Commons Attribution 4.0 (CC BY 4.0).
WaZoBiaSpeech: 500+ Hour Yoruba (yor) Corpus 数据集概述
基本信息
- 数据集名称:WaZoBiaSpeech: 500+ Hour Yoruba (yor) Corpus
- 版本:30 Nov 2025
- 语言:约鲁巴语(Yoruba,语言代码 yor)
- 数据集地址:https://huggingface.co/datasets/Africanvoice/yoruba_african_voices
- 维护者:Data Science Nigeria / EqualyzAI
- 最后更新:2025年11月30日
- 备注:该数据集会定期进行更新、修正和扩展
数据集概况
WaZoBiaSpeech 是一个大规模、高质量、完全转录的约鲁巴语(Yoruba)语音数据集。该语料库旨在加速非洲语境下语音技术的发展,促进语言多样性,并支持低资源机器学习研究。
数据包含**脚本化(scripted)和非脚本化(unscripted)**录音,通过符合伦理、以社区为中心的方式采集,具有广泛的人口统计覆盖。
语言覆盖情况
| 语言 | 总片段数 | 总时长 | 说话人数 |
|---|---|---|---|
| Yoruba | 171,651 | 509.56 小时 | 714 |
数据集结构与特征
数据集包含以下特征字段:
| 字段 | 类型 | 描述 |
|---|---|---|
| audio_id | string | 唯一音频标识符 |
| speaker_id | string | 匿名化说话人代码 |
| audio_path | Audio | 48 kHz 单声道 WAV 音频文件 |
| transcript | string | 干净的人工转录文本 |
| duration_seconds | float64 | 音频片段时长(秒) |
| gender | string | 性别(Male / Female) |
| age_group | string | 年龄段(15–29、30–45、46–60、60+) |
| education | string | 教育程度(Primary、Secondary、Tertiary) |
| domain | string | 内容背景(EV、HE、AG、BU) |
| type | string | 脚本化 / 非脚本化(Scripted / Unscripted) |
| split | string | train / dev / dev_test(说话人不重叠) |
| language | string | 语言代码(例如 pcm) |
数据划分详情
| 划分 | 样本数 | 字节数 |
|---|---|---|
| train | 147,686 | 203,997,133,341 |
| dev | 7,717 | 12,001,168,011 |
| dev_test | 8,882 | 12,547,665,326 |
- 下载大小:228,546,719,647 字节
- 数据集大小:228,545,966,678 字节
约鲁巴语汇总统计
- 总片段数:171,651
- 总时长:509.56 小时
- 性别比例:50.3% 男性 / 49.7% 女性
加载数据集
数据集已配置好,可方便加载约鲁巴语(yor)子集。
推荐环境
bash pip install --upgrade datasets[audio] pip install --upgrade ffmpeg ffmpeg-python
标准加载
python from datasets import load_dataset
Load the full training split
ds = load_dataset("Africanvoice/African_voices_yoruba", "hau", split="train")
Load a specific split (e.g., development)
ds_dev = load_dataset("Africanvoice/African_voices_yoruba", "hau", split="dev")
流式模式(用于内存优化)
python from datasets import load_dataset
Load the dev_test split in streaming mode
ds_stream = load_dataset( "Data-Science-Nigeria/African_voices_yoruba", "default", split="dev_test", streaming=True )
预期用途与应用
该数据集专为以下用途设计:
- 自动语音识别(ASR)训练
- 低资源非洲语言的自然语言处理(NLP)
- 跨语言学习与迁移学习研究
- 多语言 ASR 系统的评估
- 语言学研究和口音/方言建模
使用限制与局限
严格禁止的用途
- 声音克隆或适配(文本转语音/TTS)
- 声纹识别、说话人识别或模仿
- 监控、画像,或任何依赖识别或模仿个人的商业应用
局限性
- 区域口音变体虽然广泛,但并非完全详尽
- 自发性(非脚本化)语音片段可能包含自然的低水平背景噪声
- 不适用于生物识别或法证用途
许可与引用
许可
该数据集在 知识共享署名 4.0(CC BY 4.0) 许可下发布。
引用
bibtex @dataset{wazobiaspeech-2025, title = {WaZoBiaSpeech: A 2,500-Hour Multilingual Speech Corpus for Hausa, Igbo, Nigerian Pidgin, and Yoruba}, author = {EqualyzAI and African Voices Team}, year = {2025}, url = {https://huggingface.co/datasets/Data-Science-Nigeria/African_voices_yoruba}, note = {Yoruba subset (yor) version}, type = {dataset} }
联系与支持
如有问题、疑问或合作咨询,请在仓库中提交 issue 或直接联系维护者。