SemEval_NLI4CT_MaelAnnotated2023
收藏资源简介:
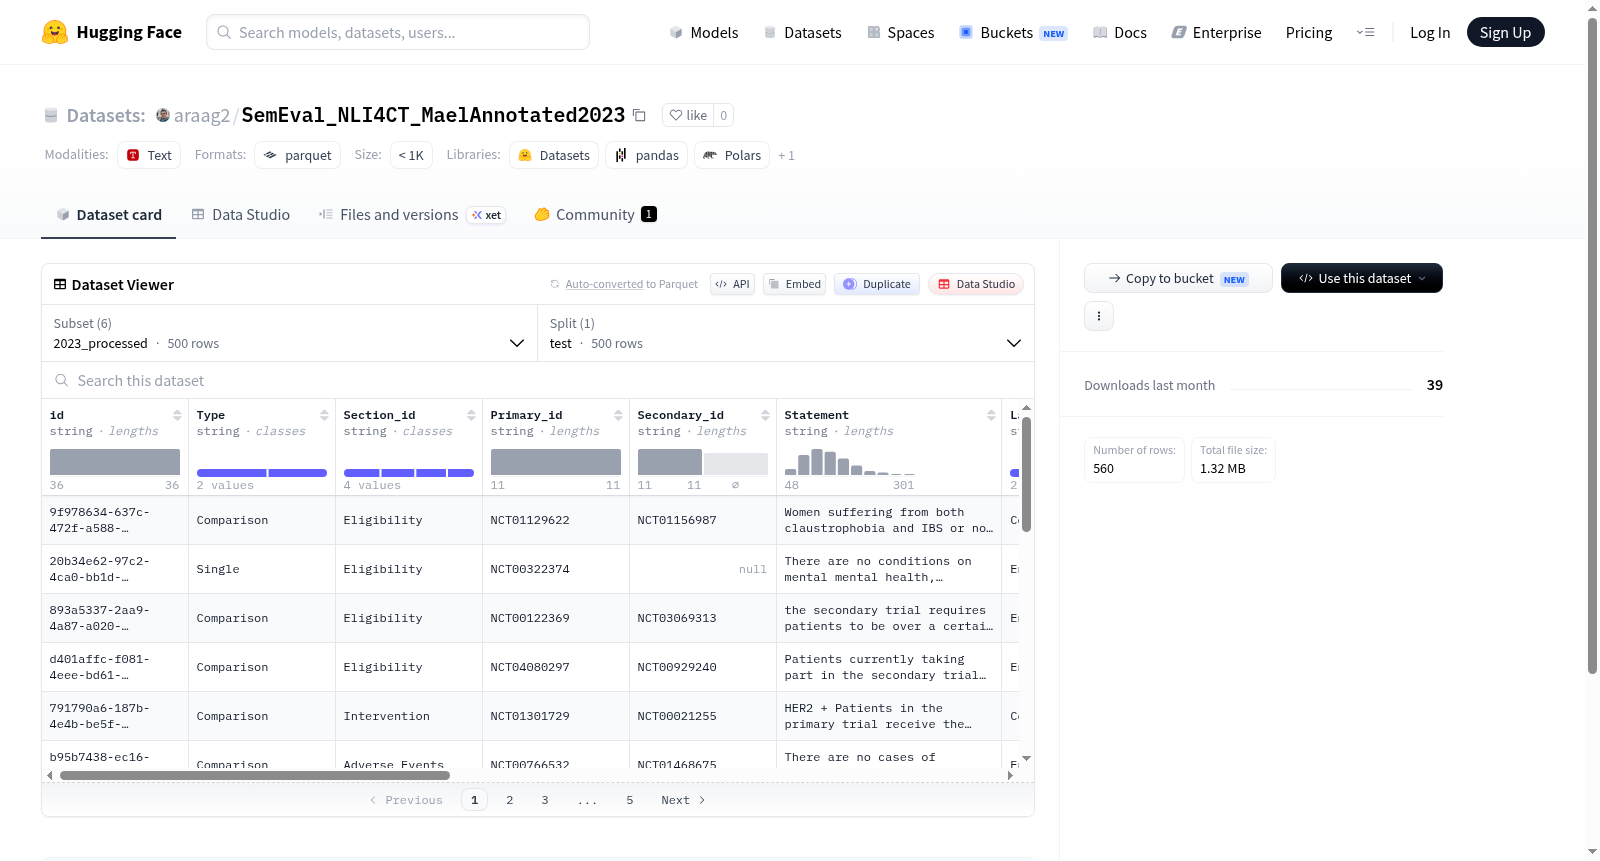
该数据集包含多个配置子集,每个子集均具有相同的字段结构,用于存储与临床试验文档相关的文本对比较或推理任务数据。字段包括唯一标识符、类型、章节ID、主文档和辅助文档的ID、陈述文本、标签、证据索引、主文档和辅助文档的具体内容(包括不良事件、入选标准、干预措施、结果四个部分)、对应的章节信息以及推理类型。所有配置仅提供测试集,样本数量从12到500不等。
This dataset contains multiple configuration subsets, each with the same field structure, used to store text pair comparison or reasoning task data related to clinical trial documents. Fields include unique identifier, type, section ID, main document and auxiliary document IDs, statement text, label, evidence index, specific content of the main document and auxiliary document (including adverse events, inclusion criteria, interventions, outcomes), corresponding section information, and reasoning type. All configurations only provide test sets, with sample sizes ranging from 12 to 500.
数据集概述:SemEval_NLI4CT_MaelAnnotated2023
基本信息
- 数据集名称:SemEval_NLI4CT_MaelAnnotated2023
- 来源平台:Hugging Face
- 数据集地址:https://huggingface.co/datasets/araag2/SemEval_NLI4CT_MaelAnnotated2023
数据集简介
该数据集基于SemEval 2023 NLI4CT任务构建,包含自然语言推理(NLI)相关的临床文本数据,用于研究临床文本中的推理与证据分析。
配置与数据划分
数据集包含 6 个子配置,每个配置均仅包含 test 分割:
| 配置名称 | 测试样本数 | 数据集大小 | 下载大小 |
|---|---|---|---|
| 2023_processed | 500 | 4,887,838 字节 | 1,189,523 字节 |
| paraphrase_abstraction | 12 | 69,942 字节 | 24,989 字节 |
| paraphrase_lexical | 12 | 70,070 字节 | 25,043 字节 |
| paraphrase_syntactic | 12 | 69,914 字节 | 24,813 字节 |
| paraphrase_tonal_shift_clinical | 12 | 69,942 字节 | 24,933 字节 |
| paraphrase_tonal_shift_lay | 12 | 69,980 字节 | 24,778 字节 |
数据特征
所有配置包含相同的特征字段:
- id (string):样本唯一标识符
- Type (string):数据类型
- Section_id (string):章节标识
- Primary_id (string):主要文档标识
- Secondary_id (string):次要文档标识
- Statement (string):推理陈述
- Label (string):推理标签
- Primary_evidence_index (sequence of int64):主要证据索引
- Secondary_evidence_index (sequence of int64):次要证据索引
- Primary_Document(结构体):包含不良事件、资格条件、干预措施、结果等四个子字段(序列类型)
- Primary_Section (sequence of string):主要文档章节
- Secondary_Document(结构体):包含不良事件、资格条件、干预措施、结果等四个子字段(序列类型)
- Secondary_Section (sequence of string):次要文档章节
- reasoning_types (sequence of string):推理类型
数据用途
该数据集适用于临床文本自然语言推理、证据抽取、多文档对比分析等研究任务,特别用于评估模型在两篇临床文档之间的推理能力。