automated-research-group/llama2_7b_chat-arc_challenge-results
收藏资源简介:
--- dataset_info: config_name: '{''do_sample''=False, ''beams''=1}' features: - name: id dtype: string - name: prediction dtype: string - name: arc_challenge_accuracy dtype: bool splits: - name: train num_bytes: 77311 num_examples: 299 download_size: 43636 dataset_size: 77311 configs: - config_name: '{''do_sample''=False, ''beams''=1}' data_files: - split: train path: '{''do_sample''=False, ''beams''=1}/train-*' ---
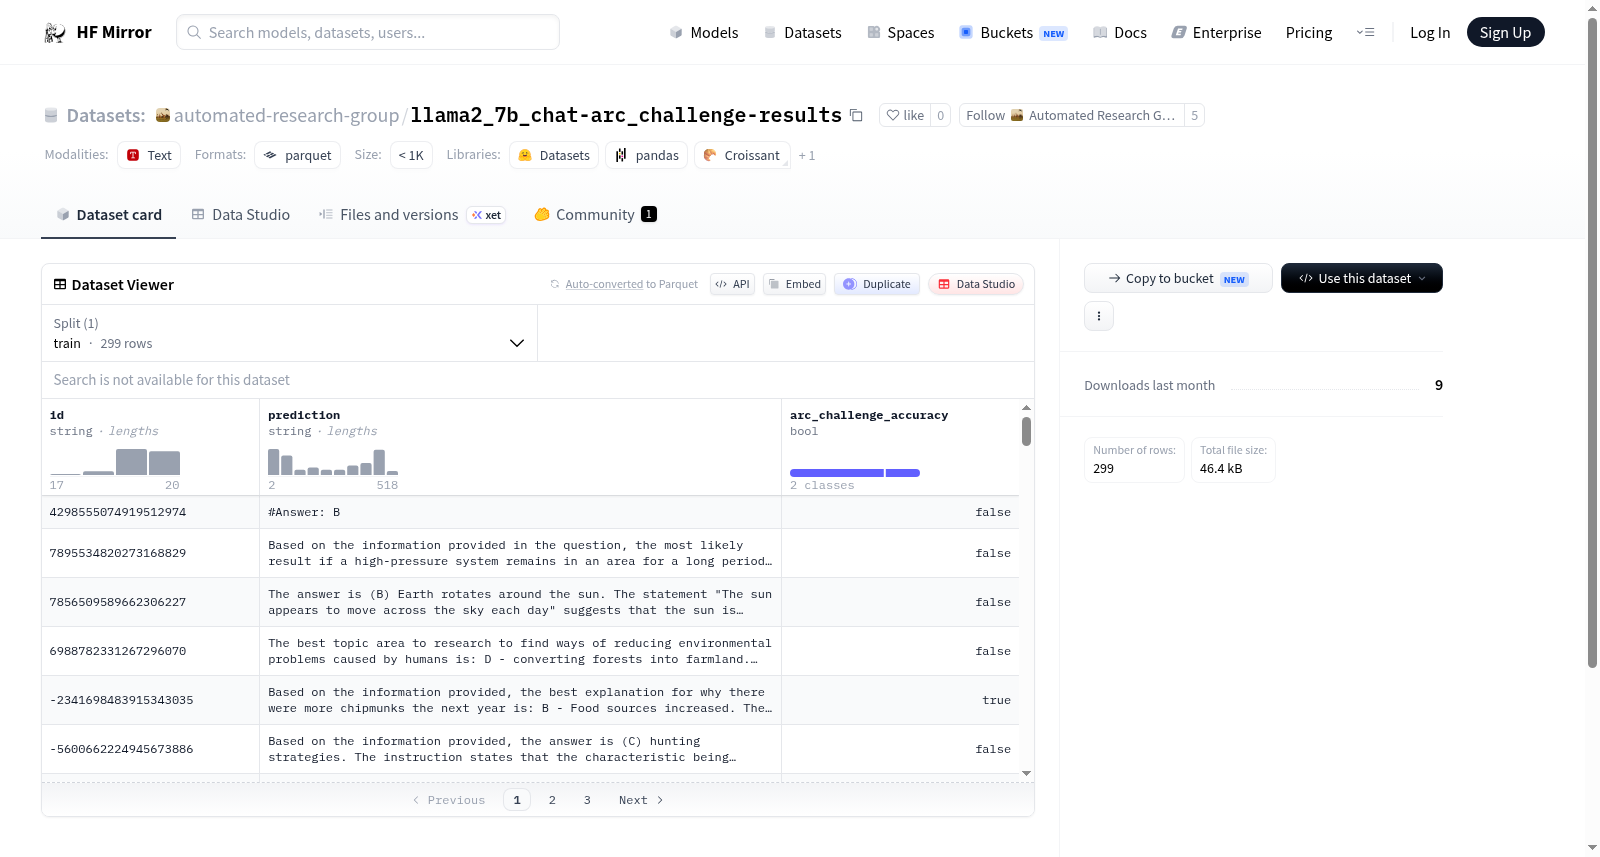
数据集信息: 配置名称:{'do_sample'=False, 'beams'=1} 特征: - 字段名:样本标识符(id),数据类型:字符串 - 字段名:预测结果(prediction),数据类型:字符串 - 字段名:ARC Challenge准确率(arc_challenge_accuracy),数据类型:布尔型 数据集划分: - 划分名称:训练集(train),字节数:77311,样本数量:299 下载大小:43636 字节 数据集总大小:77311 字节 配置项: - 配置名称:{'do_sample'=False, 'beams'=1} 数据文件: - 划分:训练集(train),路径:{'do_sample'=False, 'beams'=1}/train-*
数据集信息
配置名称
{do_sample=False, beams=1}
特征
id: 数据类型为stringprediction: 数据类型为stringarc_challenge_accuracy: 数据类型为bool
数据分割
train: 包含 299 个样本,占用 77311 字节
数据大小
- 下载大小: 43636 字节
- 数据集大小: 77311 字节
配置详情
- 配置名称:
{do_sample=False, beams=1} - 数据文件:
- 分割:
train - 路径:
{do_sample=False, beams=1}/train-*
- 分割: