
cumcm-dataset/CUMCM-2025c-dataset
收藏官方服务:
资源简介:
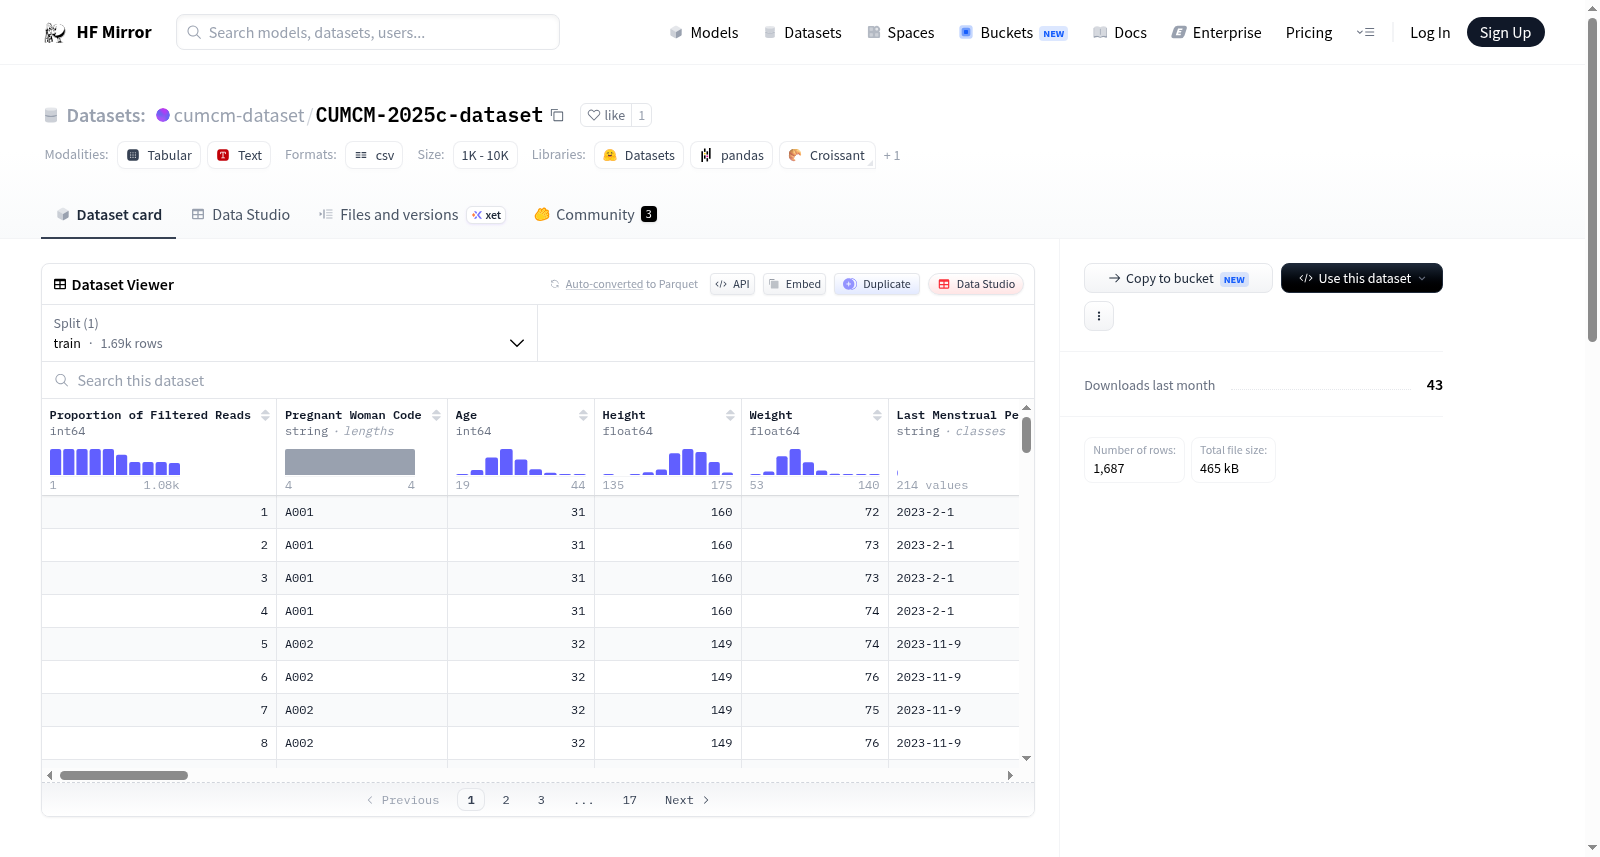
该数据集是CUMCM 2025问题C的数据集,用于文本分类和总结任务。数据集的语言为英语,包含与生物学相关的标签,数据规模在1K到10K之间。数据集的具体信息、来源、使用方式、数据结构、创建过程等详细信息未在README中提供。
This dataset is the Problem C dataset for CUMCM 2025, used for text classification and summarization tasks. The dataset is in English, tagged with biology-related topics, and has a size range of 1K to 10K. Detailed information about the dataset, its sources, usage, structure, creation process, etc., is not provided in the README.
提供机构:
cumcm-dataset搜集汇总
数据集介绍
背景与挑战
背景概述
该数据集包含1687份孕妇cfDNA测序样本,其中男胎1082例、女胎605例,由中国大学生数学建模竞赛提供,可用于胎儿染色体非整倍体检测相关研究。
以上内容由遇见数据集搜集并总结生成


