chinese_text_correction
收藏资源简介:
中文真实场景文本纠错数据集,包括拼写纠错、语法纠错、校对数据。拼写纠错数据集包括多个领域的数据,如汽车、医疗、新闻、游戏等,来源不同。语法纠错数据集包括约1500条数据,已经用gpt4o生成改写后的结果,还有来自百度智能文本校对大赛的初赛数据集。数据集结构包括原始文本、纠错后的文本和类别(positive或negative)。数据集的贡献者是shibing624。
Chinese real-world scenario text correction dataset covering spelling correction, grammar correction and text proofreading data. The spelling correction subset includes multi-domain data from diverse sources, covering automotive, medical, news, gaming and other fields. The grammar correction subset contains approximately 1,500 samples, with rewritten outputs generated by GPT-4o, as well as the preliminary round dataset from the Baidu Intelligent Text Proofreading Competition. Each sample in the dataset consists of original text, corrected text and category label (positive or negative). The contributor of this dataset is shibing624.
中文真实场景文本纠错数据集
数据集概述
该数据集包含中文真实场景下的文本纠错数据,包括拼写纠错和语法纠错。数据集涵盖多个领域,如汽车、医疗、新闻、游戏、法律、政府等。
数据集内容
拼写纠错数据
- lemon_*.tsv:各领域拼写纠错数据集,包括汽车、医疗、新闻、游戏等领域。
- ec_*.tsv:法律、医学、政府领域拼写纠错数据集。
- medical_csc.tsv:医学领域拼写纠错数据集。
语法纠错数据
- grammar.tsv:语法纠错数据集,约1500条,已经用gpt4o生成改写后的结果。
- TextProofreadingCompetition.tsv:真实场景下验证集约2000条,包括约1000条正样本和1000条负样本。
数据集结构
数据字段
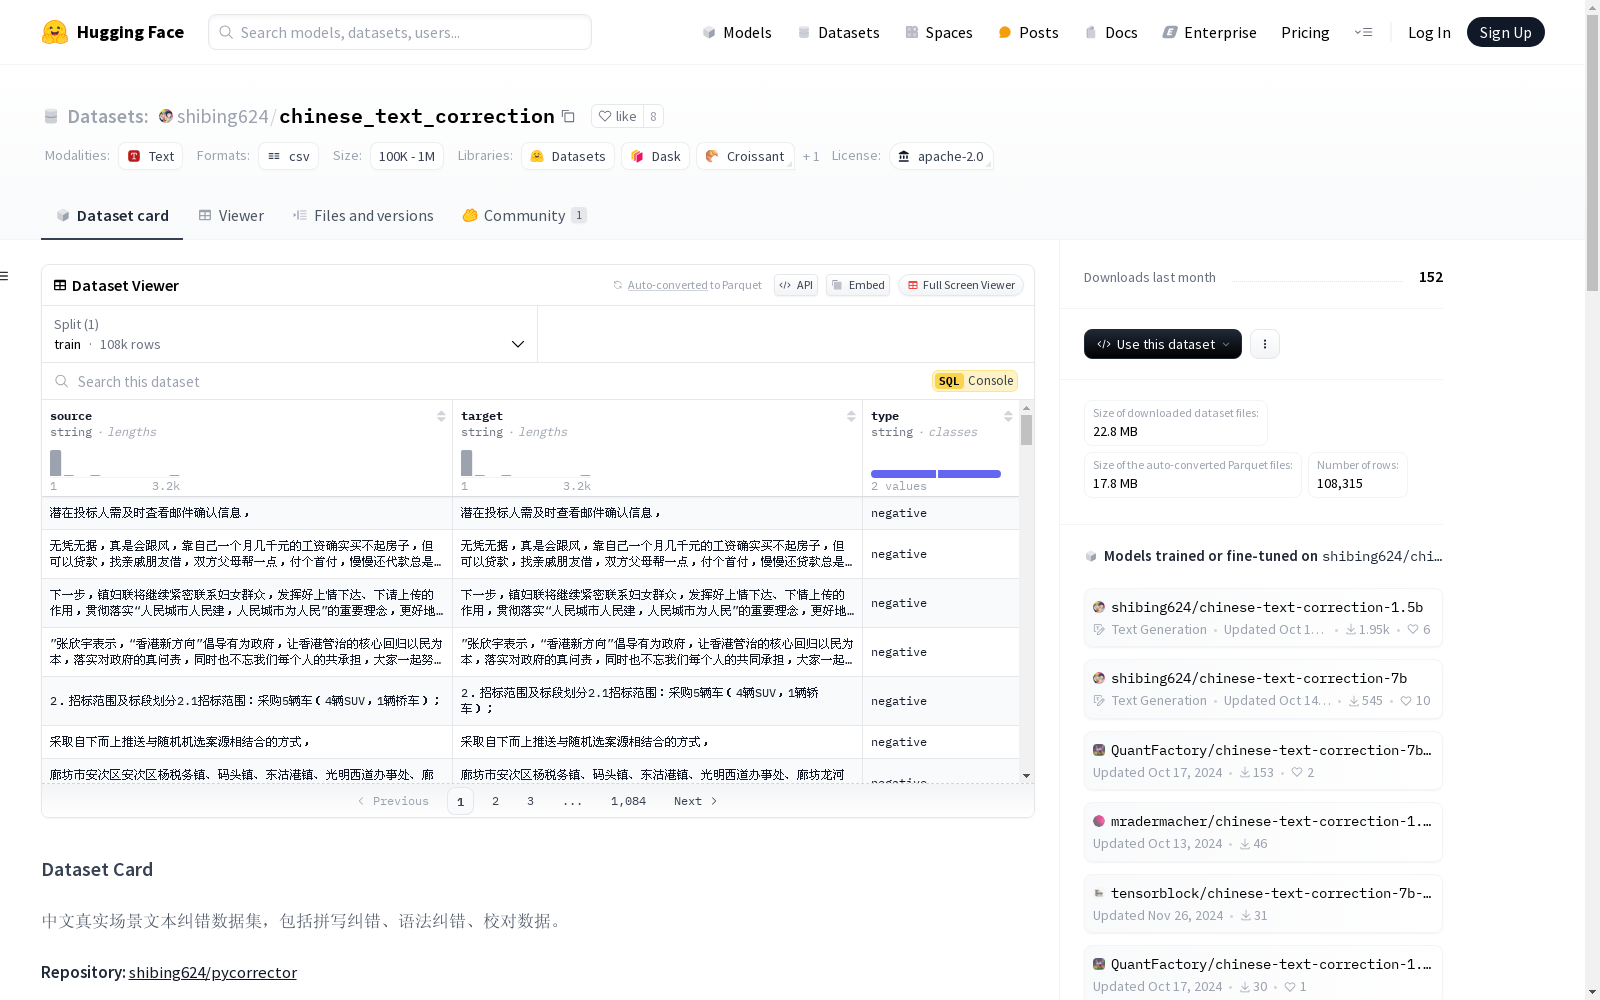
source:原始文本。target:纠错后的文本。type:类别,positive表示原始文本和纠错文本相同,negative表示不同,需要纠错的。
数据分割
数据集包含多个文件,总计约73328条数据。
贡献者
- shibing624 添加了此数据集。