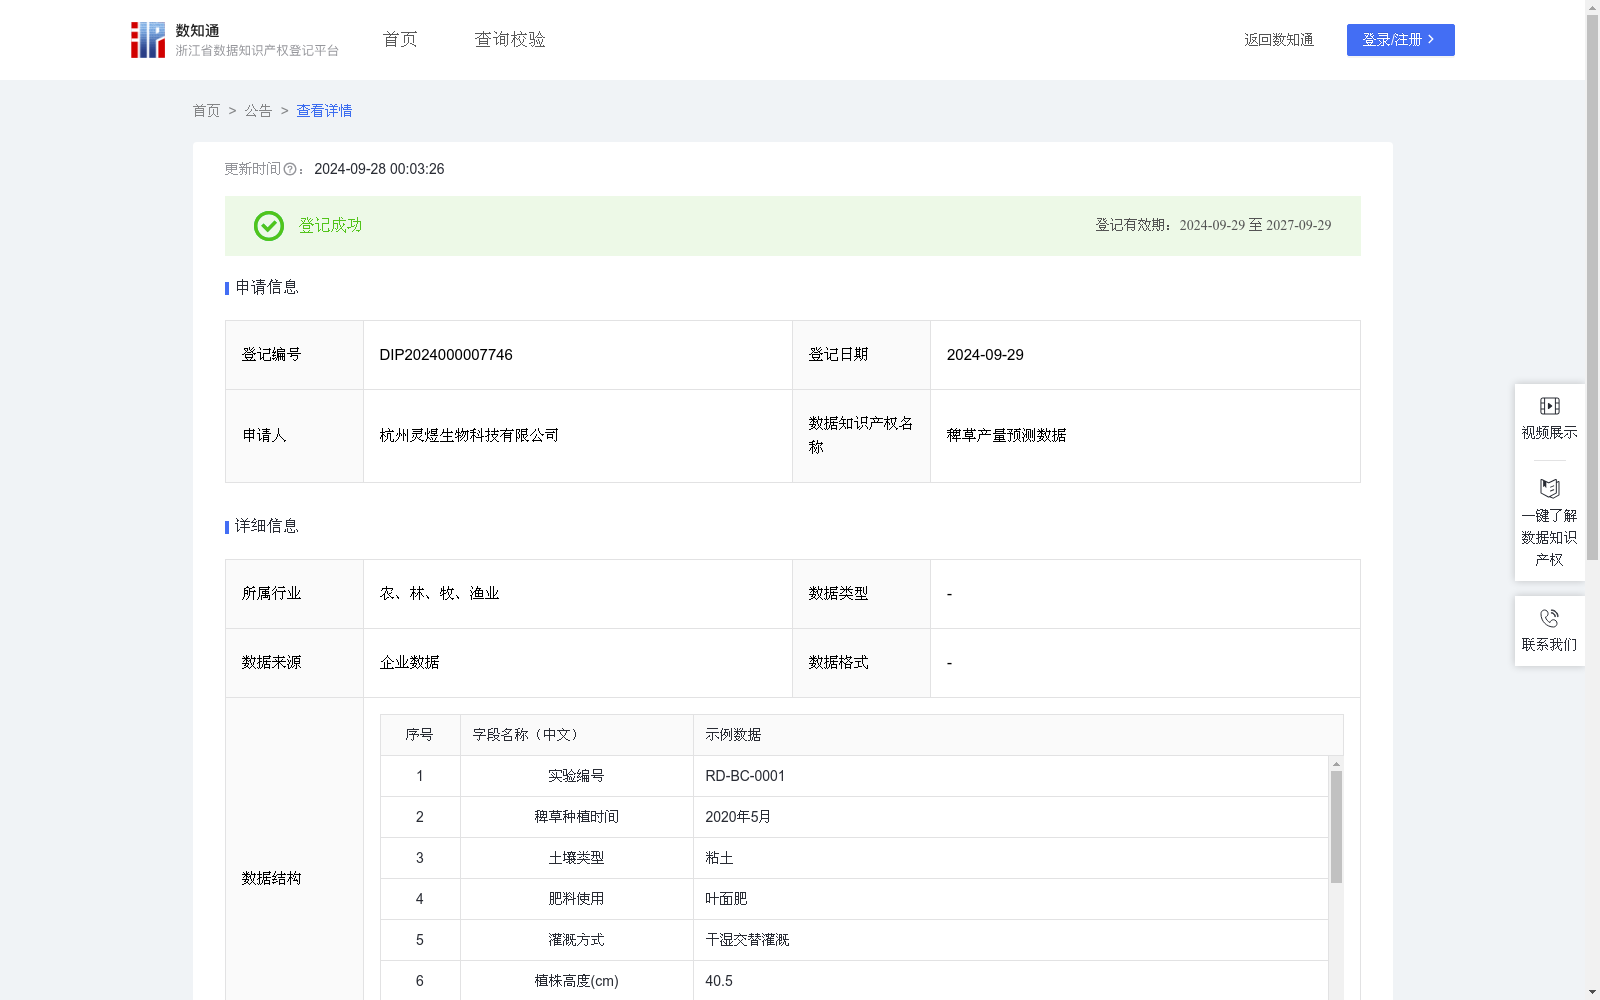
稗草产量预测数据
收藏资源简介:
可以用于稗草产量预测,输入为土壤类型、肥料使用、灌溉方式、植株高度(cm)、稗草茎粗(cm)、叶面积指数、根系长度(cm)、稗草产量(产量)、根系主要分布范围(cm)、稗草根系数量、根茎长(cm)、叶绿素含量(mg/g)、叶片数量。输出为稗草产量预测值。该模型帮助解决了稗草产量和稗草状况的关系建模的问题,对于预测产量过低则农民可以采取相应的措施来优化种植策略。稗草产量的高低不仅仅是农业生产的考核指标,更是反映了某个地区农业生产和农业经济状况的重要指标。产量的高低直接关系到农民的收入和粮食生产能力,对于农村的经济发展、人民生活水平的提高以及国家的农业安全都有着重要的影响。因此,提高产量不仅仅是农民个人利益的追求,更是国家和社会对于农业生产发展的重视。通过调查采集稗草数据,并使用传统算法和多元线性回归算法预测稗草产量。该模型的输入为土壤类型、肥料使用、灌溉方式、植株高度(cm)、稗草茎粗(cm)、叶面积指数、根系长度(cm)、稗草产量(产量)、根系主要分布范围(cm)、稗草根系数量、根茎长(cm)、叶绿素含量(mg/g)、叶片数量。多元线性回归算法通过分析这些输入变量与稗草产量之间的线性关系,确定每个变量的权重系数,使用深度学习框架构建模型,F=ω1 * U1 + ω2* U2+…+ω13 * U13,其中,ω1至ω13分别是土壤类型、肥料使用、灌溉方式、植株高度、稗草茎粗、叶面积指数、根系长度、稗草产量、根系主要分布范围、稗草根系数量、根茎长、叶绿素含量、叶片数量的权重系数,同理 U1至 U13分别是上述13个输入量的参数值,F是稗草产量预测值。在模型训练过程中,算法会利用稗草产量实际值进行优化,调整权重系数以最小化预测误差。模型通过最小二乘法等技术,根据输入的数据计算稗草产量预测值,从而得出最终结果。
This dataset can be used for barnyard grass yield prediction. Its inputs include soil type, fertilizer application, irrigation method, plant height (cm), barnyard grass stem diameter (cm), leaf area index, root length (cm), barnyard grass yield (yield), main root distribution range (cm), number of barnyard grass roots, rhizome length (cm), chlorophyll content (mg/g), and number of leaves. The output is the predicted barnyard grass yield. This model addresses the problem of modeling the relationship between barnyard grass yield and its growth status. When the predicted yield is too low, farmers can take corresponding measures to optimize their planting strategies. Barnyard grass yield is not only an assessment indicator for agricultural production, but also an important indicator reflecting the agricultural production and economic conditions of a region. Yield level directly affects farmers' income and food production capacity, and has a significant impact on rural economic development, improvement of people's living standards, and national agricultural security. Therefore, increasing yield is not only the pursuit of individual farmers' interests, but also reflects the attention paid by the country and society to the development of agricultural production. Barnyard grass data was collected through surveys, and traditional algorithms and multiple linear regression algorithms were used to predict barnyard grass yield. The inputs of this model are the aforementioned 13 variables: soil type, fertilizer application, irrigation method, plant height (cm), barnyard grass stem diameter (cm), leaf area index, root length (cm), barnyard grass yield (yield), main root distribution range (cm), number of barnyard grass roots, rhizome length (cm), chlorophyll content (mg/g), and number of leaves. The multiple linear regression algorithm analyzes the linear relationship between these input variables and barnyard grass yield to determine the weight coefficient of each variable. The model is built using a deep learning framework, with the formula: F=ω1 * U1 + ω2* U2+…+ω13 * U13, where ω1 to ω13 are the weight coefficients of soil type, fertilizer application, irrigation method, plant height, barnyard grass stem diameter, leaf area index, root length, barnyard grass yield, main root distribution range, number of barnyard grass roots, rhizome length, chlorophyll content, and number of leaves respectively, and U1 to U13 are the parameter values of the aforementioned 13 input quantities respectively, with F being the predicted barnyard grass yield. During the model training process, the algorithm uses the actual values of barnyard grass yield for optimization, adjusting the weight coefficients to minimize the prediction error. The model calculates the predicted barnyard grass yield based on the input data using techniques such as the least squares method to obtain the final result.