atlas-of-knowledge
收藏资源简介:
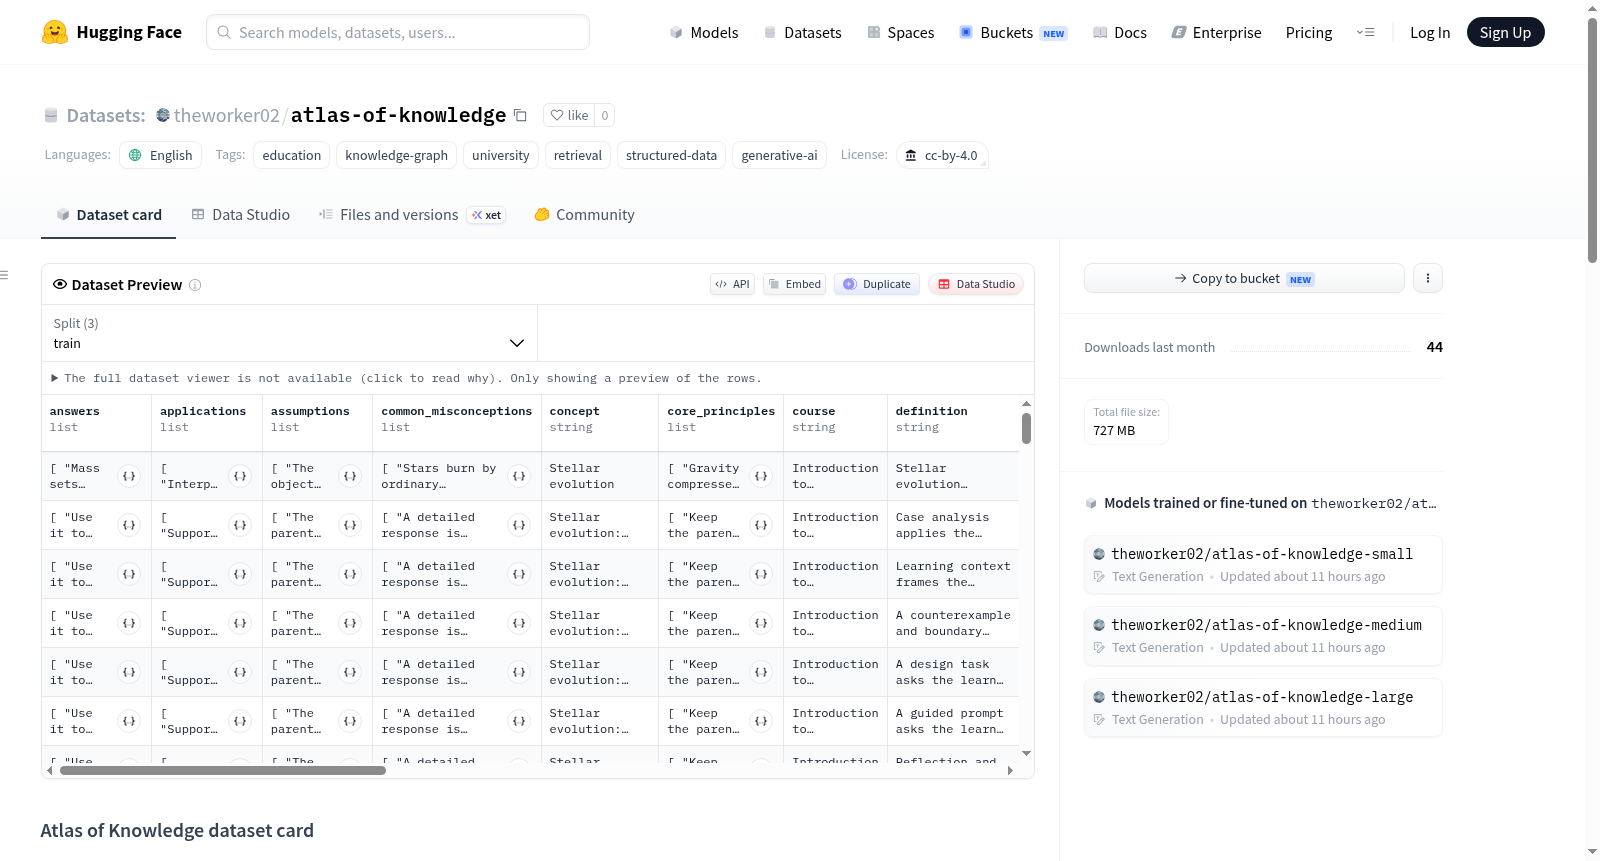
Atlas of Knowledge 是一个结构化的大学级概念数据集,旨在支持检索、教育工具开发、知识图谱分析以及经过评估的模型训练实验。该数据集包含 20,417 条记录,涵盖 17 门课程和 15 个学科。每条记录包含唯一标识符、学科、课程、主题、定义、解释字段、先决条件、类型化关系、应用、误解、假设、推理、问题、答案以及可选的领域属性。数据集包含多个子集:concepts(主要概念)、courses、prerequisites、relationships、questions、reasoning、misconceptions 和 cross_domain,并提供了确定性训练/验证/测试划分以及独立图结构。此外,该数据集还附带三个基于 PEFT/LoRA 的因果语言模型适配器(Small、Medium、Large),作为研究基线。数据收集使用声明的课程目录允许列表,并自动批准高置信度条目,来源与生成记录分离。数据集经过模式、关系、重复、许可、一致性和置信度检查,但可能遗漏细微的事实错误、文化框架、有争议的解释、来源偏见或语义重复,且初始覆盖较稀疏,以英语为主,不应用于评估广泛的教育能力。
Atlas of Knowledge is a structured university-level concept dataset designed to support retrieval, educational tool development, knowledge graph analysis, and evaluated model training experiments. The dataset contains 20,417 records covering 17 courses and 15 disciplines. Each record includes a unique identifier, discipline, course, topic, definition, explanation field, prerequisites, typed relationships, applications, misconceptions, assumptions, reasoning, questions, answers, and optional domain attributes. The dataset includes multiple subsets: concepts, courses, prerequisites, relationships, questions, reasoning, misconceptions, and cross_domain, and provides deterministic train/validation/test splits and independent graph structures. Additionally, the dataset comes with three PEFT/LoRA-based causal language model adapters (Small, Medium, Large) as research baselines. Data collection uses a declared course catalog allow list and automatically approves high-confidence entries, with sources separated from generated records. The dataset has undergone schema, relationship, duplication, licensing, consistency, and confidence checks, but may miss subtle factual errors, cultural frameworks, controversial interpretations, source biases, or semantic duplicates, and the initial coverage is sparse, primarily in English, and should not be used to evaluate broad educational capabilities.
数据集概述
- 名称: Atlas of Knowledge
- 版本: 1.1.0
- 记录数: 20,417
- 语言: 英语
- 许可证: CC-BY-4.0
- 标签: 教育、知识图谱、大学、检索、结构化数据、生成式AI
内容与用途
- 该数据集提供大学级概念的原始、结构化表示,支持检索、教育工具开发、知识图谱分析以及模型训练实验。
- 不替代专家指导、领域参考或专业建议。
数据结构
- 主要子集
concepts包含:ID、学科、课程、主题、定义、解释字段、先决条件、类型化关系、应用、误解、假设、推理、问题、答案及可选领域属性。 - 覆盖范围:17门课程、15个学科。
- 学习单元:每个经过验证的学习面向通过12个不同的学习单元开发,包括诊断检查、案例分析与检索练习等。
- 导出内容:
courses、prerequisites、relationships、questions、reasoning、misconceptions、cross_domain,以及确定的训练/验证/测试划分和独立图结构。
生成式模型系列
| 变体 | 基础模型 | 基础参数量 | LoRA参数量 | 训练步数 | 验证损失 |
|---|---|---|---|---|---|
| Small | distilgpt2 |
82,723,584 | 811,008 | 2,000 | 0.117829 |
| Medium | gpt2-medium |
354,823,168 | 4,325,376 | 1,200 | 0.102025 |
| Large | gpt2-large |
774,030,080 | 8,110,080 | 600 | 0.097541 |
- 模型为PEFT/LoRA因果语言模型适配器,仅基于Atlas训练记录训练,需配合指定基础模型使用。
- 数据集包内包含两个任务特定分类器(
models/目录),附指标、依赖清单和局限性说明卡片。
收集与来源
- 采用声明的课程目录白名单,检查来源身份与兼容许可,评分课程元数据,自动批准高置信度条目。
- 模糊来源会被隔离,来源出处与生成记录分离存储。
- 不抓取任意网站,也不将源文本作为数据发布。
验证与局限性
- 记录经过模式、关系、重复、许可、一致性和置信度检查。
- 自动验证可能遗漏微妙事实错误、文化框架、争议解释、来源偏差或语义重复。
- 分数不证明正确性。初始覆盖稀疏且仅限英语,不应用于衡量广泛教育能力。
版本与引用
- 语义化数据集版本确保可复现构建。
- GitHub托管源管线,完整生成版本发布在Hugging Face,包含卡片、模式、出处元数据、引文与许可证。
- 引用时需注明精确版本,参见
CITATION.cff和README中的现成引用格式。
数据示例
json {"id":"computer-science:algorithms:algorithmic-complexity","concept":"Algorithmic complexity","prerequisites":[],"related_concepts":[{"target_id":"mathematics:proofs:mathematical-induction","relationship":"formalizes","rationale":"Induction is a standard method for proving recurrence-based bounds."}]}