alinia/pii_detection_ner
收藏资源简介:
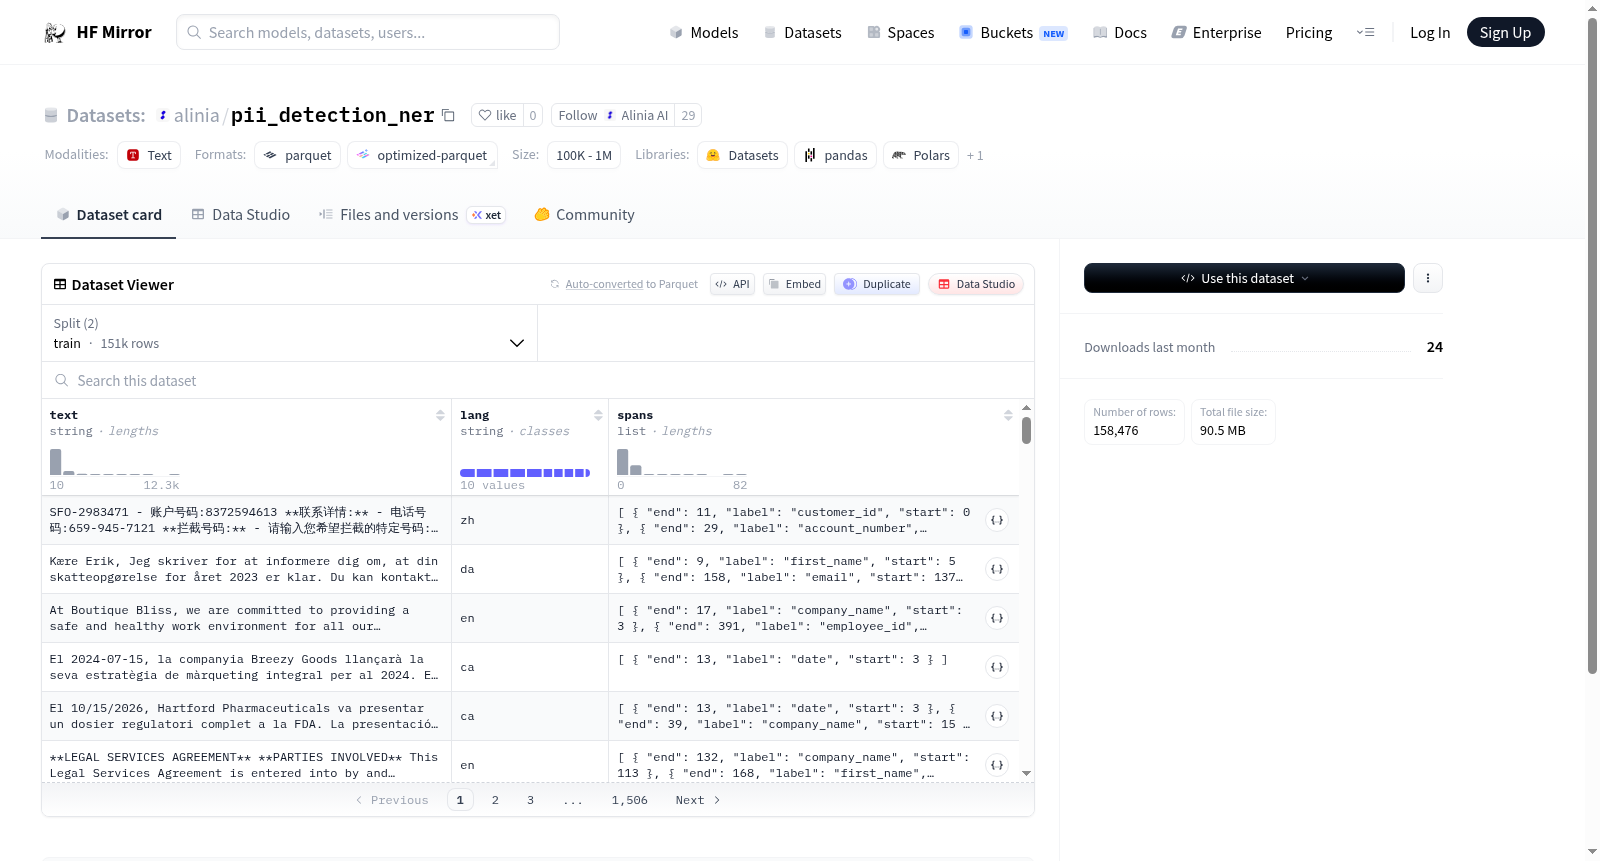
该数据集是一个用于自然语言处理任务的结构化数据集,包含文本、语言和标注范围。具体来说,每个数据样本由text(原始文本字符串)、lang(文本语言代码字符串)和spans(一个列表,每个元素包含start、end和label字段,用于标注文本中的实体或特定范围,如命名实体识别或文本分类)组成。数据集分为train(训练集,包含150,552个示例,大小约152.6 MB)和val(验证集,包含7,924个示例,大小约8.0 MB)两个分割,总下载大小约90.5 MB,总数据集大小约160.7 MB。数据格式支持多语言文本处理,适用于序列标注、信息提取等NLP应用。
This dataset is a structured dataset for natural language processing tasks, containing text, language, and annotated spans. Specifically, each data sample consists of text (raw text string), lang (language code string for the text), and spans (a list where each element includes start, end, and label fields, used to annotate entities or specific ranges in the text, such as for named entity recognition or text classification). The dataset is divided into train (training set, with 150,552 examples, approximately 152.6 MB) and val (validation set, with 7,924 examples, approximately 8.0 MB) splits, with a total download size of about 90.5 MB and a total dataset size of about 160.7 MB. The data format supports multilingual text processing and is suitable for NLP applications like sequence labeling and information extraction.