omnimcp_data_kafka_streaming_teaser
收藏资源简介:
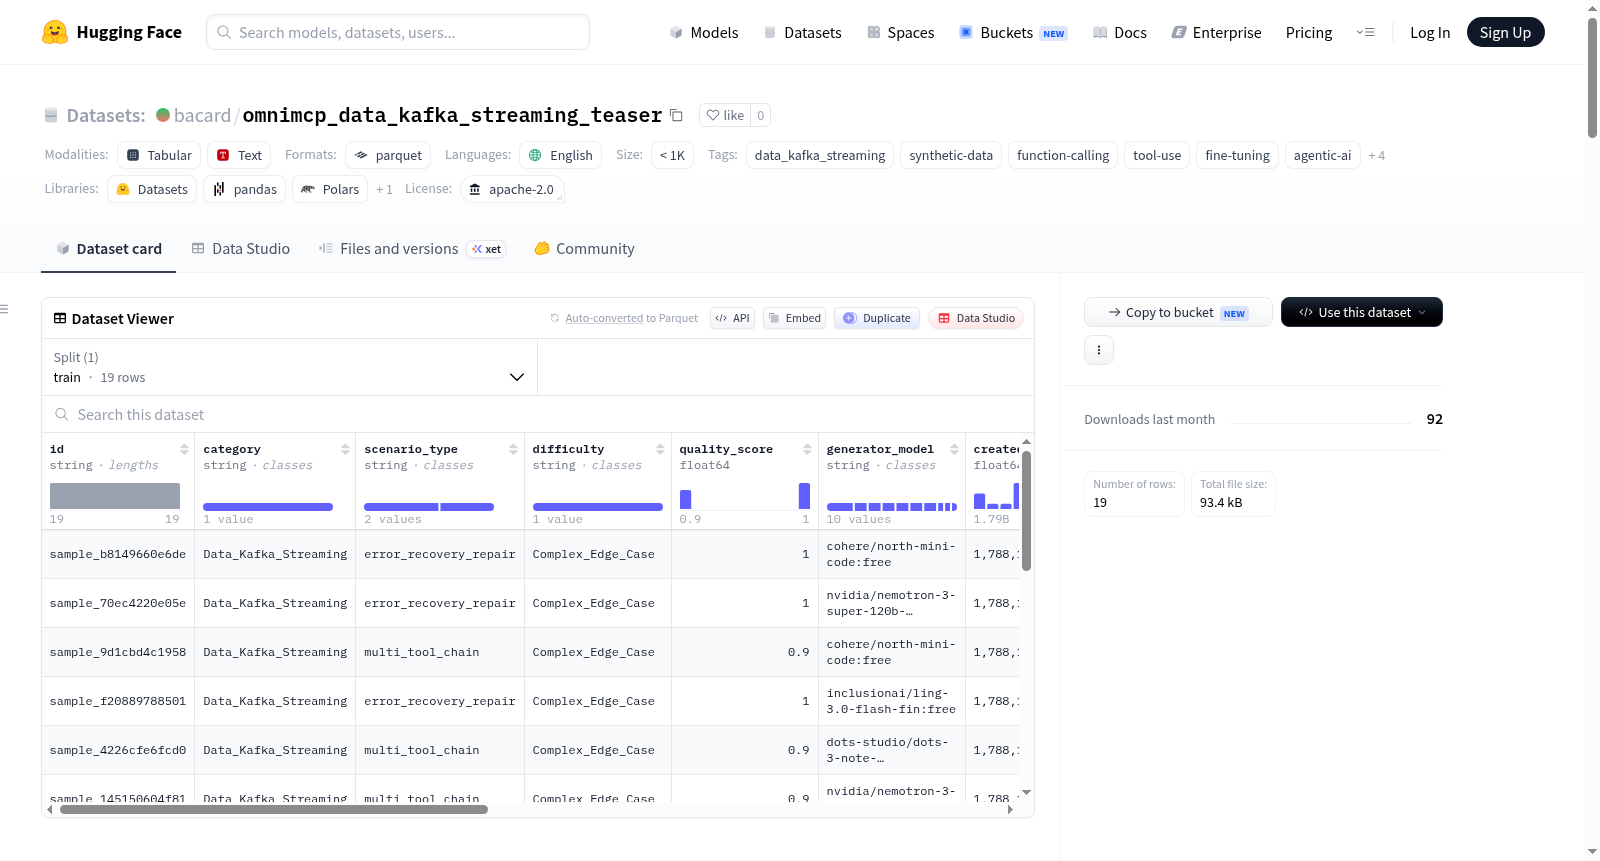
OmniMCP - Data Kafka Streaming (Free Teaser Edition) 是一个免费评估版的合成数据集,专为多轮代理函数调用(Agent Function-Calling)场景设计。该数据集属于OmniMCP模块化生态系统的一部分,专注于Kafka流式处理领域的工具使用和微调任务。数据规模小于1K条样本,每条样本包含指令(instruction)、思考过程(thought_process)和最终输出(final_output)三个字段。数据集所有内容均为合成生成,经过Pydantic AST严格验证,确保0%语法错误;采用原生链式思维推理,在每个工具调用前嵌入逐步诊断逻辑;并预训练了真实API故障和超时恢复场景,而非简单的理想路径。此外,数据集完全符合GDPR/DSGVO隐私要求,不包含任何个人数据,且附带EU AI Act合规声明。该免费试用版以Apache-2.0许可证发布,适用于研究和评估。
OmniMCP - Data Kafka Streaming (Free Teaser Edition) is a free evaluation synthetic dataset designed for multi-turn agent function-calling scenarios. It is part of the OmniMCP modular ecosystem, focusing on tool usage and fine-tuning tasks in the Kafka streaming domain. The dataset contains fewer than 1K samples, each with three fields: instruction, thought_process, and final_output. All content is synthetically generated, strictly validated by Pydantic AST to ensure 0% syntax errors, and employs native chain-of-thought reasoning with step-by-step diagnostic logic before each tool call. It also pre-trains real API failure and timeout recovery scenarios rather than simple ideal paths. Furthermore, the dataset fully complies with GDPR/DSGVO privacy requirements, contains no personal data, and includes an EU AI Act compliance statement. This free teaser edition is released under the Apache-2.0 license and is suitable for research and evaluation.
OmniMCP: Data Kafka Streaming (Free Teaser Edition) 数据集概述
基本信息
- 数据集名称:OmniMCP - Data Kafka Streaming (Free Teaser Edition)
- 语言:英语
- 许可协议:Apache 2.0(免费研究评估版)
- 大小类别:样本数少于 1K(n<1K)
- 标签:data_kafka_streaming、synthetic-data、function-calling、tool-use、fine-tuning、agentic-ai、multi-turn、unsloth、axolotl、ollama
- 数据集地址:https://huggingface.co/datasets/bacard/omnimcp_data_kafka_streaming_teaser
数据集定位与特色
该数据集是 OmniMCP 模块化生态系统 中的一个免费评估预览版本,专注于 企业数据平台的 Kafka 流式处理场景,属于经过验证的多轮 Agent 函数调用(function-calling)数据集。
核心优势(对比通用公开数据集)
- 0.0% 语法与解析错误:100% 通过 Pydantic AST 验证,严格遵循 OpenAPI 模式
- 原生思维链推理:每次工具调用前包含
<thought>块中的逐步诊断逻辑 - 生产级自愈能力:基于真实的 API 故障、连接池超时和错误恢复场景训练,而非简单理想路径
- 100% GDPR/DSGVO 合规:零个人数据(使用 RFC 2606
@example.com、RFC 5737 消毒文档 IP) - 符合欧盟 AI 法案:包含第 50 条和第 53 条的合成数据来源声明
数据加载示例
该数据集提供一个 Parquet 文件,可通过 Python 加载,包含列:instruction、thought_process、final_output。
python import pandas as pd
df = pd.read_parquet("omnimcp_data_kafka_streaming_teaser.parquet") print(f"Loaded {len(df)} verified training turns!") print(df[["instruction", "thought_process", "final_output"]].head())
所属产品体系(OmniMCP 四级架构)
该数据集属于 Level 2「房屋」层级 — 企业 DataOps Lakehouse 部门套件 的一部分,同时与 Level 3「村庄」层级的 Enterprise Modern Data Platform 村庄 相关,是 Kafka Streaming 场景的砖块组件。
商业说明
- 本免费版:Apache 2.0 许可,可用于免费研究和评估
- 完整生产版:可在 Gumroad 平台 获取完整版及商业 EULA 许可证,包含商业货币化及模型部署权限
- 完整母版:OmniMCP Master Metropolis(Level 4)包含 500+ 跨领域多轮场景,可在 Gumroad 购买