Preethi Dataset
收藏资源简介:
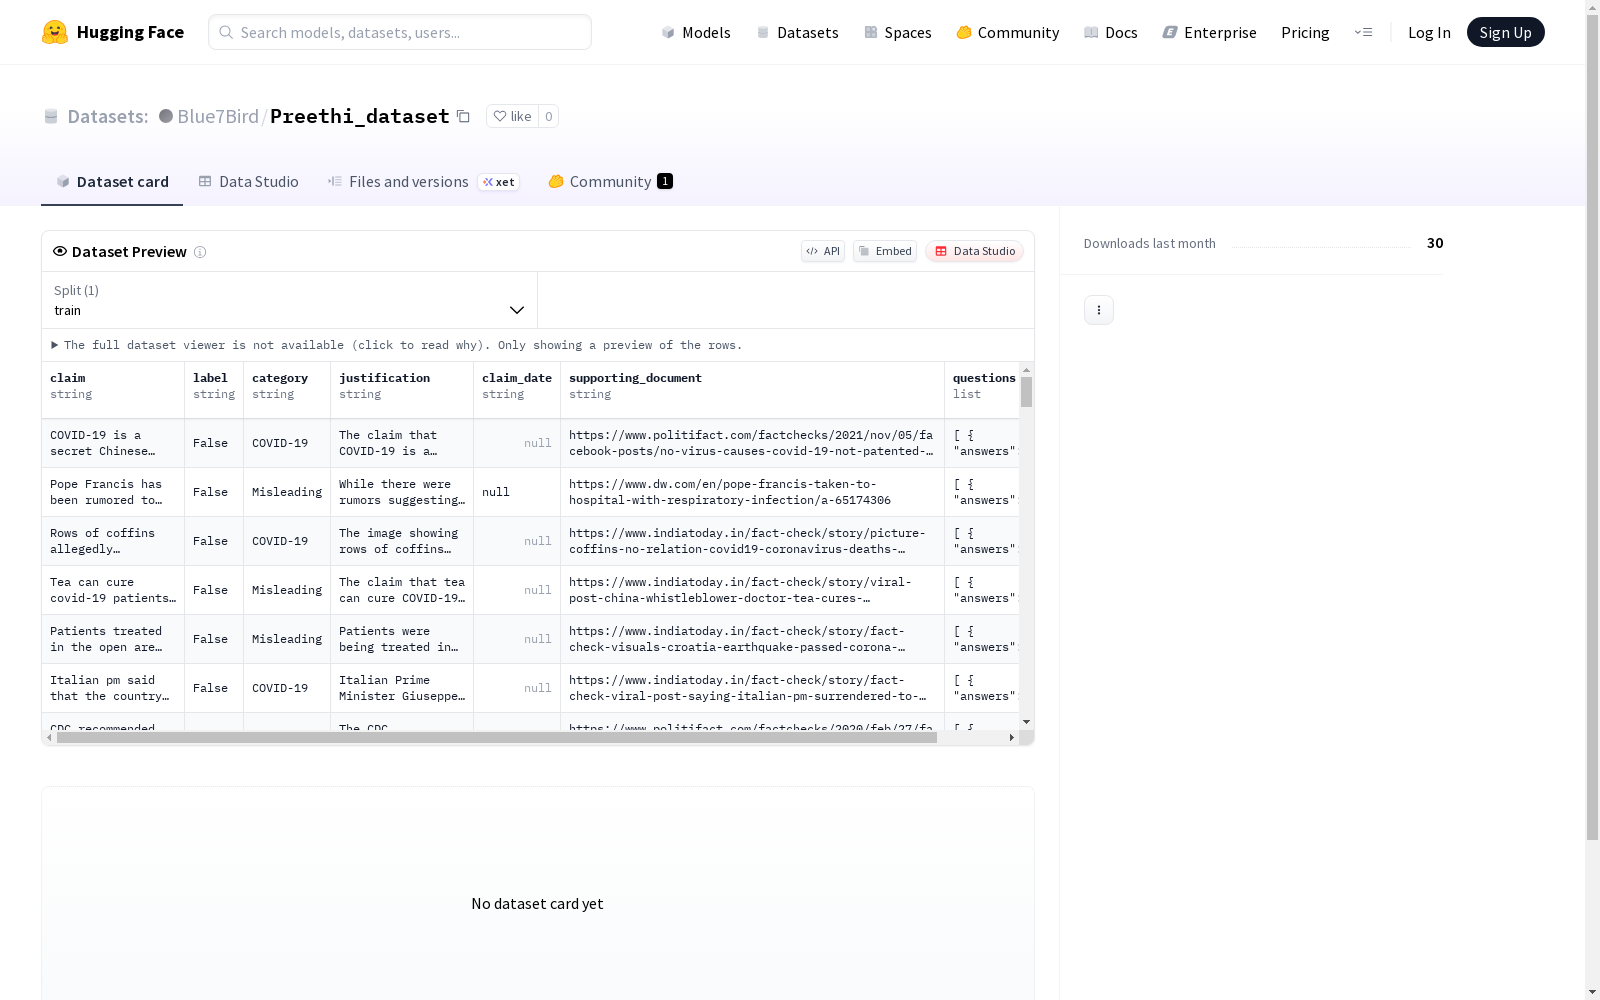
Preethi数据集是一个包含英语和泰卢固语的双语事实核查数据集,旨在支持多语言声明验证。该数据集基于公开的IFND数据集创建,包含来自IFND的2500个真实声明和从事实核查网站收集的2435个虚假声明。Preethi数据集为每个声明提供了额外的元数据,包括来自网络的支撑文档、声明日期、黄金解释和黄金QA对。数据集在泰卢固语中通过机器翻译后由人工后编辑以确保质量。该数据集旨在解决印度等多语言国家中通过翻译技术传播虚假信息的问题,并提高大型语言模型在事实核查任务中的性能。
The Preethi Dataset is a bilingual English-Telugu fact-checking dataset designed to support multilingual claim verification. It is built upon the publicly available IFND dataset, containing 2500 genuine claims sourced from IFND and 2435 false claims collected from public fact-checking websites. The dataset provides supplementary metadata for each claim, including web-retrieved supporting documents, claim publication dates, gold-standard explanations, and gold-standard QA pairs. The Telugu subset of the dataset was first machine-translated and then manually post-edited to ensure data quality. This dataset aims to address the issue of disinformation spread via translation technologies in multilingual countries such as India, and to improve the performance of large language models (LLMs) in fact-checking tasks.