bergson-wikitext-2-4656-chunks
收藏资源简介:
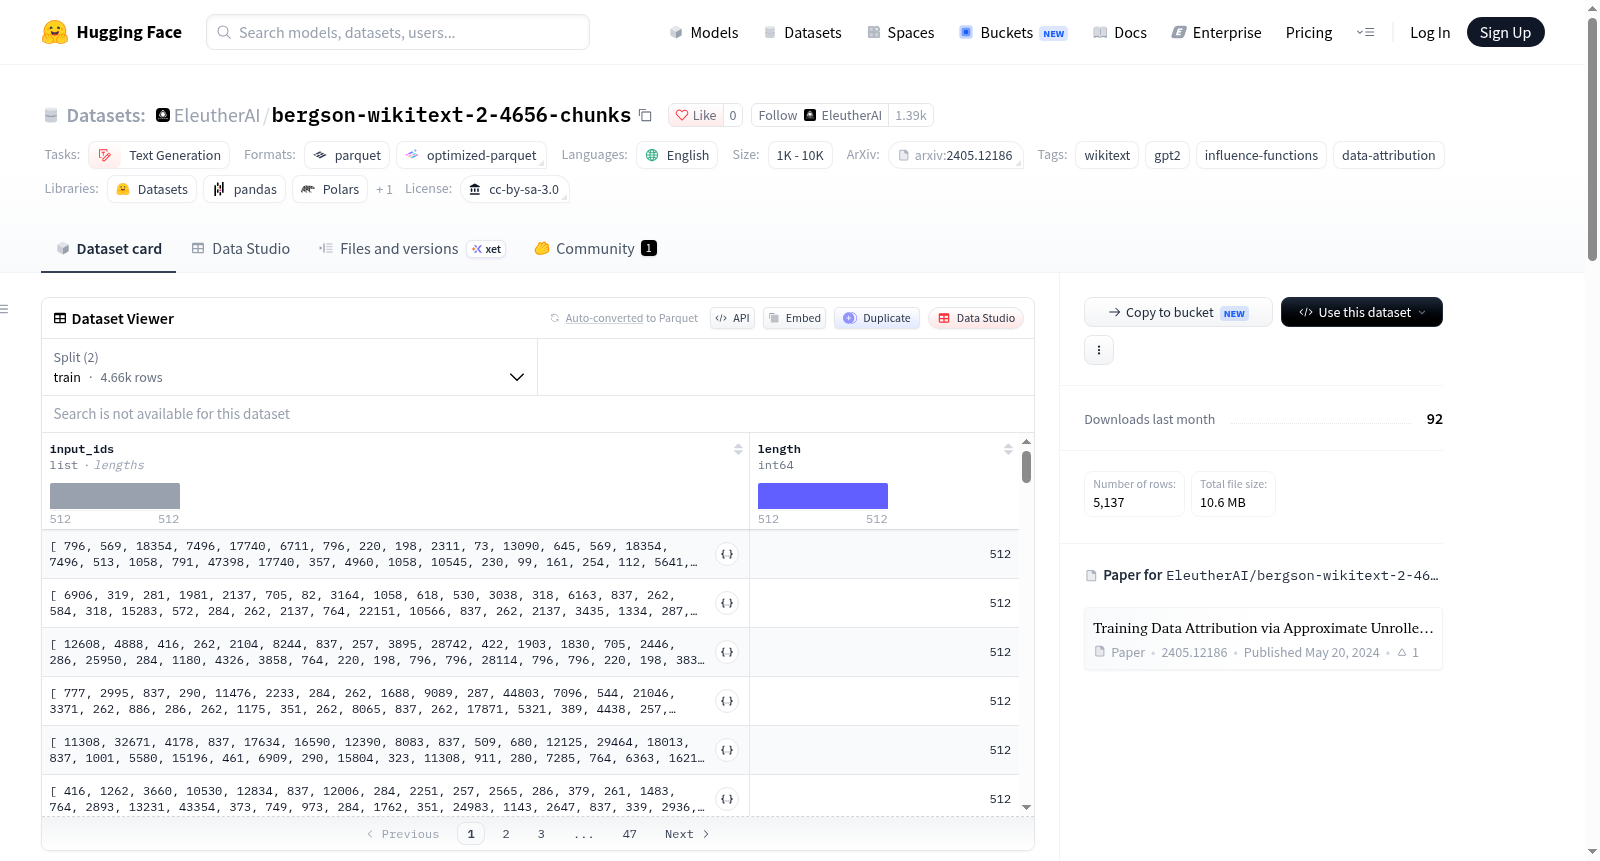
该数据集是 bergson-wikitext-2-4656-chunks,基于 WikiText-2 构建的预标记化数据集,专为 GPT-2 模型设计。数据来源于 Salesforce/wikitext 的 wikitext-2-raw-v1 版本,使用 GPT-2 tokenizer 进行分词,然后通过 group_texts 方法将文本连接成固定长度 512 token 的块,丢弃剩余部分。该预处理过程是确定性的,不涉及随机打乱。数据规模为训练集 4656 条样本,验证集 481 条样本,每条样本包含两个字段:input_ids(长度为 512 的整数列表,表示 GPT-2 BPE token ID)和 length(固定为 512 的 int64 值)。该数据集主要用于 Bergson 项目中复现 Bae 等人 2024 年的训练数据归因论文(Training Data Attribution via Approximate Unrolled Differentiation),适用于文本生成任务以及数据归因、影响函数等研究。许可证为 CC BY-SA 3.0。
This dataset is bergson-wikitext-2-4656-chunks, a pre-tokenized dataset built on WikiText-2, designed for the GPT-2 model. The data originates from the wikitext-2-raw-v1 version of Salesforce/wikitext, tokenized using the GPT-2 tokenizer, and then concatenated into fixed-length chunks of 512 tokens via the group_texts method, discarding the remainder. The preprocessing is deterministic without random shuffling. The dataset comprises 4656 training samples and 481 validation samples, each containing two fields: input_ids (a list of 512 integers representing GPT-2 BPE token IDs) and length (a fixed int64 value of 512). This dataset is primarily used in the Bergson project to reproduce the training data attribution paper by Bae et al. (2024) (Training Data Attribution via Approximate Unrolled Differentiation), suitable for text generation tasks and research on data attribution, influence functions, etc. The license is CC BY-SA 3.0.
数据集概述
数据集名称:bergson-wikitext-2-4656-chunks
发布机构:EleutherAI
数据集语言:英语(en)
许可证:CC BY-SA 3.0(继承自 WikiText-2)
任务类别:文本生成(text-generation)
标签:wikitext、gpt2、influence-functions、data-attribution
数据规模:1K < n < 10K
数据集内容
该数据集是 WikiText-2 的预分词版本,将原始语料切分为固定长度为 512 token 的块(chunk),每个块作为一个独立的文档。数据使用 GPT-2 的 BPE tokenizer 进行分词,主要用于 EleutherAI 的 bergson 项目中,复现 Bae et al. 2024 的论文《Training Data Attribution via Approximate Unrolled Differentiation》中的 WikiText-2 / GPT-2 数据归因实验。
数据划分
| 划分 | 样本数 |
|---|---|
| train | 4,656 |
| validation | 481 |
数据字段
- input_ids:
list[int32],长度为 512 的 GPT-2 BPE token ID 序列 - length:
int64,固定值为 512
数据生成方式
该数据集通过标准 HuggingFace run_clm 预处理流程生成,与 kronfluence 的 examples/wikitext 使用的流程一致,具体步骤如下:
- 使用 GPT-2 tokenizer 对公开的
Salesforce/wikitext的wikitext-2-raw-v1版本进行分词(不添加特殊 token)。 - 通过
group_texts函数,在每个 1000 行的datasets.map批次内,将 token 拼接、丢弃余数,并切分为固定 512 token 的块。
关键说明:
- 1000 行批处理是决定性的:该批处理方式正好产生 4656 / 481 个块(若采用全语料拼接则会产生 4671 / 482 个块)。
- 无随机性:整个流程不涉及 shuffle 或随机种子,是确定性生成。
- 可复现性:生成的 chunk 与参考数据集逐字节一致(所有 4656 个训练行和 481 个验证行的
input_ids均完全相同)。
使用说明
在 bergson 配置中加载该数据集时,需设置 chunk_length: 0,因为数据已经完成分词和分块处理。