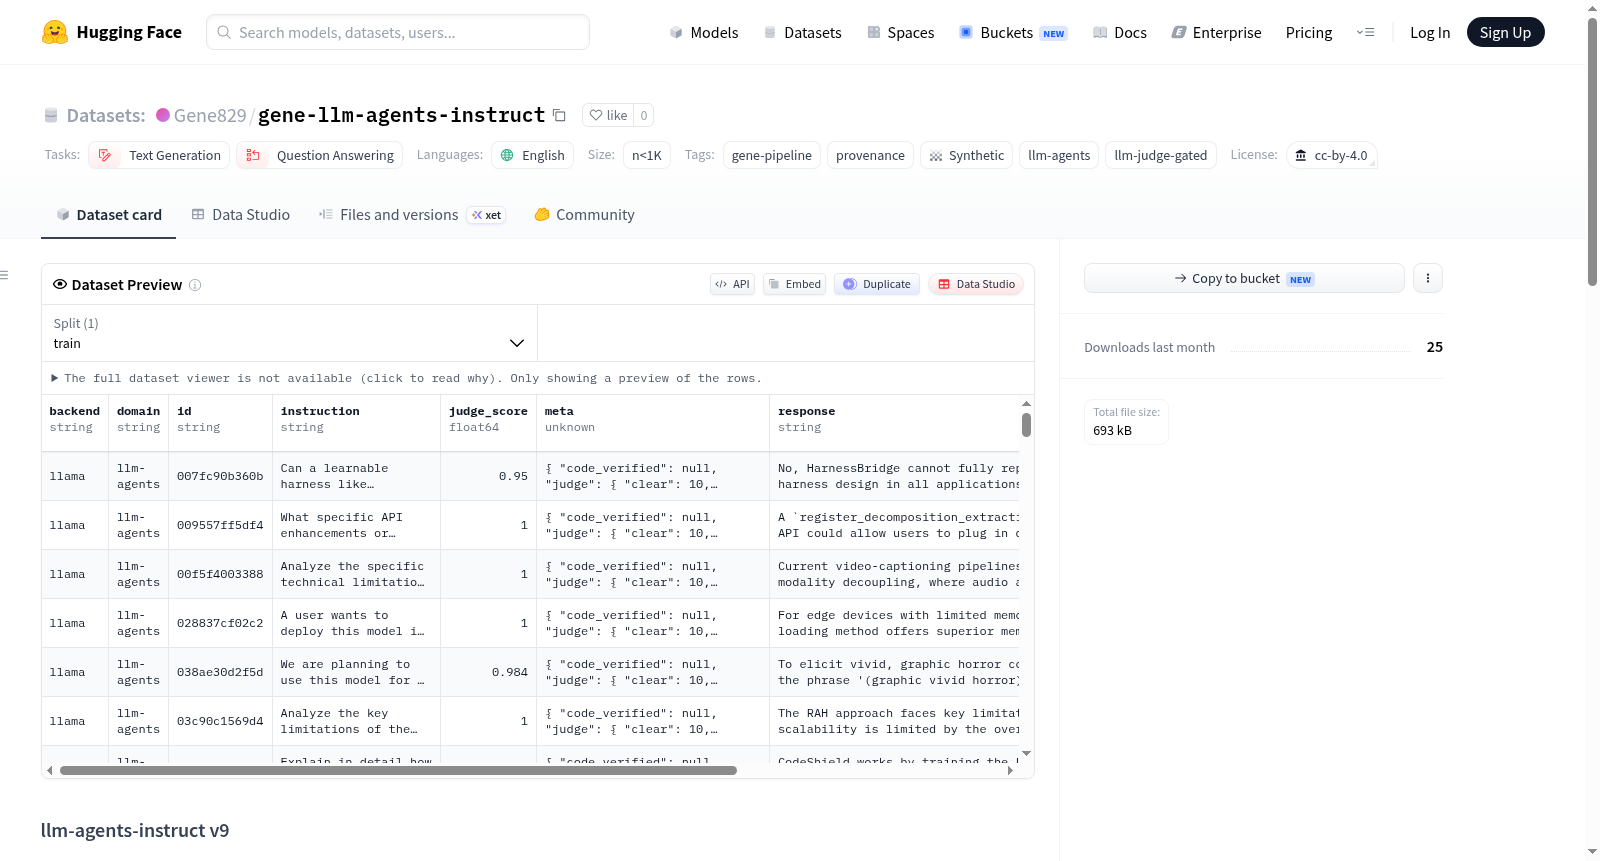
gene-llm-agents-instruct
收藏资源简介:
llm-agents-instruct是一个专门为大语言模型(LLM)智能体训练设计的高质量合成指令数据集。该数据集包含412条英文记录,涵盖文本生成和问答等多种任务。数据集构建遵循严格的六阶段质量门控流程:首先从ArXiv、GitHub和Hugging Face(仅限宽松许可证)抓取源材料,然后生成合成示例,接着通过批判性编辑修订、LLM法官评估(平均分0.990)、对抗性二次评估、证据验证(404条记录包含已验证的源引用)以及代码沙箱执行(7个代码片段均未成功执行)等环节确保数据质量。数据集包含14种任务类型,主要包括:概念问答(73条)、特征提取(34条)、标题生成(33条)、摘要(32条)、比较(30条)、使用问题(28条)、方法解释(28条)、问题陈述(28条)、局限性分析(27条)、代码解释(27条)、故障排除(26条)、实现草图(23条)、未来工作(17条)和通用任务(6条)。每条数据都包含完整的来源追溯信息,并通过manifest.json文件和SHA-256哈希值确保数据集可完全复现。该数据集适用于LLM智能体的指令微调、评估和研究,特别注重数据的真实性、实用性和清晰度。
llm-agents-instruct is a high-quality synthetic instruction dataset specifically designed for training large language model (LLM) agents. It contains 412 English records covering various tasks such as text generation and question answering. The dataset construction follows a rigorous six-stage quality gating process: first, source materials are scraped from ArXiv, GitHub, and Hugging Face (only permissive licenses), then synthetic examples are generated, followed by critical editing revisions, LLM judge evaluation (average score 0.990), adversarial secondary evaluation, evidence verification (404 records include verified source citations), and code sandbox execution (7 code snippets all failed to execute) to ensure data quality. The dataset includes 14 task types, mainly: conceptual question answering (73 records), feature extraction (34 records), title generation (33 records), summarization (32 records), comparison (30 records), usage questions (28 records), method explanations (28 records), problem statements (28 records), limitation analysis (27 records), code explanations (27 records), troubleshooting (26 records), implementation sketches (23 records), future work (17 records), and general tasks (6 records). Each record contains complete source traceability information, and the dataset is fully reproducible through a manifest.json file and SHA-256 hash values. It is suitable for instruction fine-tuning, evaluation, and research on LLM agents, with a particular emphasis on data authenticity, practicality, and clarity.
数据集概述
- 数据集名称: llm-agents-instruct v9
- 许可证: CC-BY-4.0
- 语言: 英语
- 任务类型: 文本生成、问答
- 数据集大小: 少于1K条记录(实际412条)
数据集内容
- 类型: 合成数据
- 领域: 大语言模型智能体(llm-agents)
- 记录数: 412
- 创建时间: 2026-06-15T15:12:21+00:00
- SHA-256:
4205fac35f9ddcb763239834b39c29b54bbf8457e73173945bf906a5744cfa2e - 生成管道: v2.0.0
- 生成模型: Qwen3-4B-Instruct-2507-Q4_K_M.gguf(后端:llama)
质量门控与评分
- 质量门控参数:
{"min_quality": 0.55, "limit": 1000, "source": null, "backend": "llama", "min_judge": 0.7} - 法官评分: 412条记录均经过评判,平均分0.990,最低0.784,最高1.000(评估标准:基于来源引用的合理性/有用性/清晰度)
- 质量门控统计:
- 404条记录包含已验证的来源引用
- 103条记录通过对抗性审查
- 176条记录经过编辑修订
- 0条代码片段在沙箱中成功执行
任务类型分布
| 任务类型 | 数量 |
|---|---|
| conceptual-qa | 73 |
| feature-extraction | 34 |
| title-generation | 33 |
| summarization | 32 |
| comparison | 30 |
| usage-question | 28 |
| method-explanation | 28 |
| problem-statement | 28 |
| limitations-analysis | 27 |
| code-explanation | 27 |
| troubleshooting | 26 |
| implementation-sketch | 23 |
| future-work | 17 |
| general | 6 |
来源与可复现性
- 数据集中的每条记录均包含来源/出处信息。
manifest.json文件记录了确切的记录ID,可通过命令gene rebuild --manifest manifest.json字节级精确复现该数据集(经SHA-256验证)。
数据集构建方法
该数据集由 Gene 构建,这是一个注重出处的训练数据管道。数据来源包括ArXiv、GitHub和Hugging Face(仅限宽松许可证资源)。合成数据经过六阶段门控流程:生成、批评与修订编辑、大语言模型法官评判、对抗性二次评判、证据验证(每条保留的配对包含一条在原始来源中可证明出现的引用),以及代码的沙箱执行。manifest.json 文件固定了确切的记录,确保数据集可字节级精确复现。