SberDevices/Golos
收藏资源简介:
Golos是一个适用于语音研究的俄语语料库,主要由通过众包平台手动注释的录音文件组成,总时长约为1240小时。数据集结构包括训练和测试文件的数量和时长,以及不同领域的分布。此外,还提供了音频文件的下载链接,包括opus和wav格式,以及基于该语料库构建的声学模型和语言模型。评估部分展示了不同测试集的词错误率(WER)。
Golos is a Russian corpus for speech research, mainly composed of audio recordings manually annotated through crowdsourcing platforms, with a total duration of approximately 1240 hours. The dataset structure covers the counts and durations of training and test files, as well as the distribution across various domains. Additionally, download links for audio files in both OPUS and WAV formats are provided, alongside acoustic models and language models developed based on this corpus. The evaluation section showcases the word error rate (WER) of different test sets.
Golos数据集
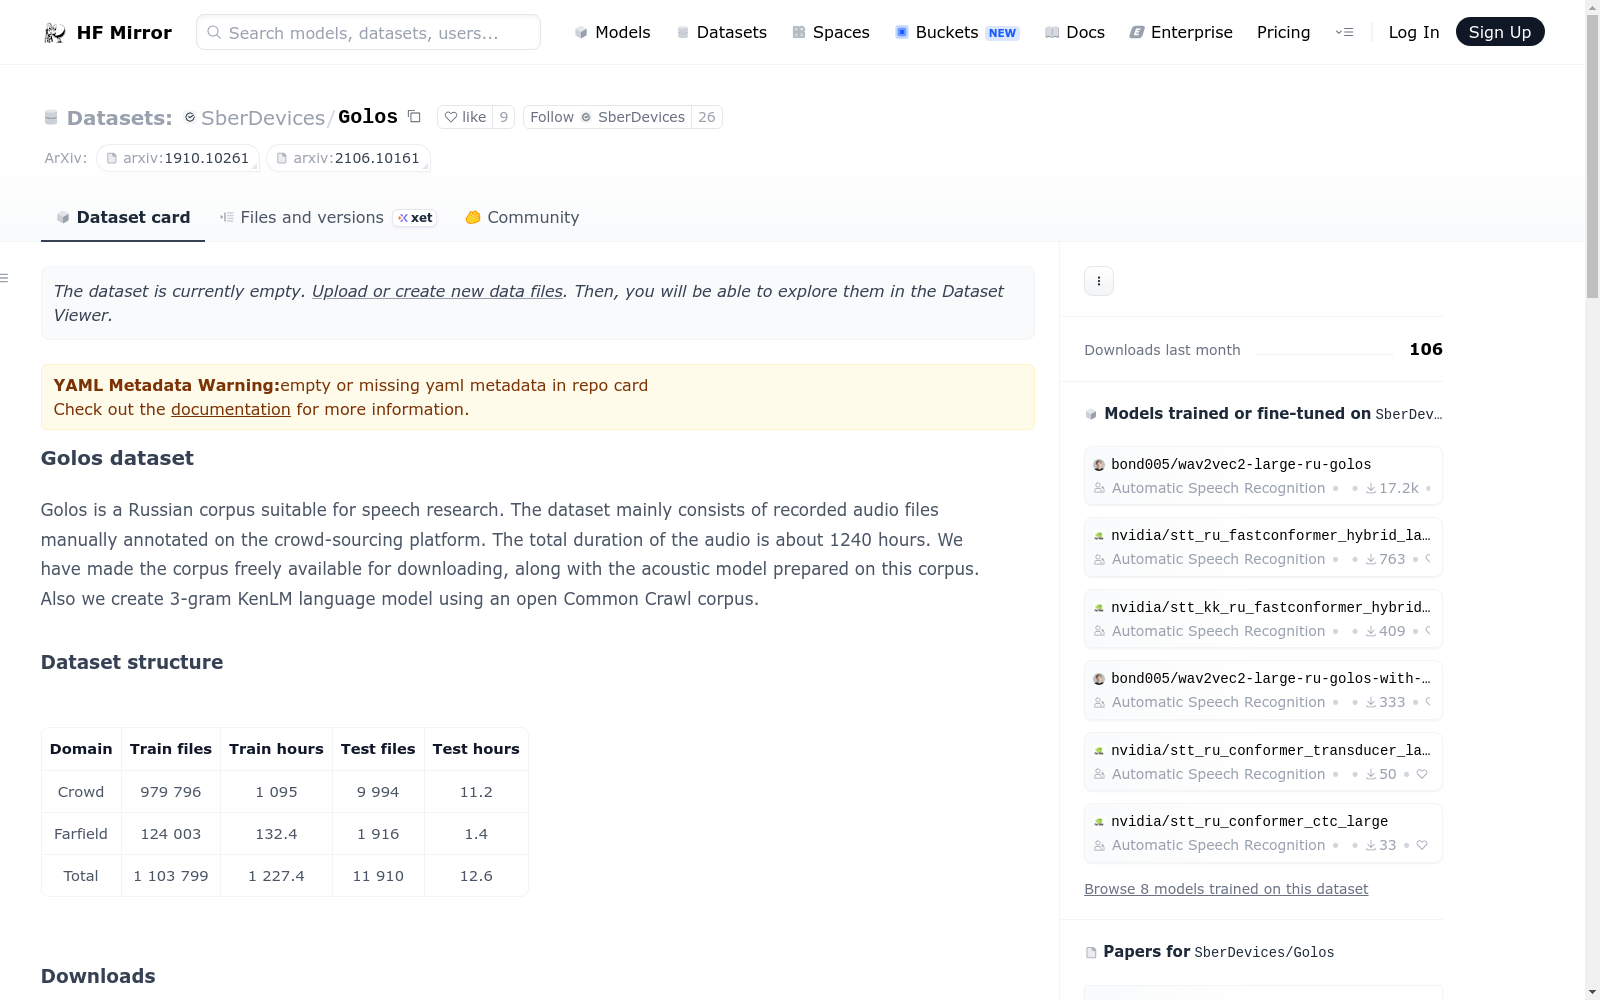
Golos是一个适用于语音研究的俄语语料库。该数据集主要由在众包平台上手动标注的录音文件组成,总时长约为1240小时。我们已将该语料库及其在此语料库上准备的声音模型免费提供下载。此外,我们还使用开放的Common Crawl语料库创建了3-gram KenLM语言模型。
数据集结构
| 领域 | 训练文件数 | 训练时长(小时) | 测试文件数 | 测试时长(小时) |
|---|---|---|---|---|
| 众包 | 979,796 | 1,095 | 9,994 | 11.2 |
| 远场 | 124,003 | 132.4 | 1,916 | 1.4 |
| 总计 | 1,103,799 | 1,227.4 | 11,910 | 12.6 |
下载
opus格式的音频文件
| 文件名 | 大小 | 链接 |
|---|---|---|
| golos_opus.tar | 20.5 GB | https://sc.link/JpD |
wav格式的音频文件
包含所有训练转录文本的清单文件在train_crowd9.tar归档文件中列出:
| 文件名 | 大小 | 链接 |
|---|---|---|
| train_farfield.tar | 15.4 GB | https://sc.link/1Z3 |
| train_crowd0.tar | 11 GB | https://sc.link/Lrg |
| train_crowd1.tar | 14 GB | https://sc.link/MvQ |
| train_crowd2.tar | 13.2 GB | https://sc.link/NwL |
| train_crowd3.tar | 11.6 GB | https://sc.link/Oxg |
| train_crowd4.tar | 15.8 GB | https://sc.link/Pyz |
| train_crowd5.tar | 13.1 GB | https://sc.link/Qz7 |
| train_crowd6.tar | 15.7 GB | https://sc.link/RAL |
| train_crowd7.tar | 12.7 GB | https://sc.link/VG5 |
| train_crowd8.tar | 12.2 GB | https://sc.link/WJW |
| train_crowd9.tar | 8.08 GB | https://sc.link/XKk |
| test.tar | 1.3 GB | https://sc.link/Kqr |
声学和语言模型
使用QuartzNet15x5架构构建的声学模型,并使用NeMo工具包进行训练。
使用KenLM语言模型工具包创建的三个n-gram语言模型:
- 基于Common Crawl俄语数据集构建的语言模型
- 基于Golos训练集构建的语言模型
- 基于Common Crawl和Golos数据集共同构建的语言模型(50/50)
| 文件名 | 大小 | 链接 |
|---|---|---|
| QuartzNet15x5_golos.nemo | 68 MB | https://sc.link/ZMv |
| KenLMs.tar | 4.8 GB | https://sc.link/YL0 |
评估
不同测试集的词错误率百分比:
| 解码器 测试集 | 众包测试 | 远场测试 | MCV<sup>1</sup> dev | MCV<sup>1</sup> test |
|---|---|---|---|---|
| 贪婪解码器 | 4.389 % | 14.949 % | 9.314 % | 11.278 % |
| 带Common Crawl LM的束搜索解码器 | 4.709 % | 12.503 % | 6.341 % | 7.976 % |
| 带Golos训练集LM的束搜索解码器 | 3.548 % | 12.384 % | - | - |
| 带Common Crawl和Golos LM的束搜索解码器 | 3.318 % | 11.488 % | 6.4 % | 8.06 % |
<sup>1</sup> Common Voice - Mozilla的倡议,帮助教机器如何真实人说话。