gnormplus-sapbert-classification
收藏资源简介:
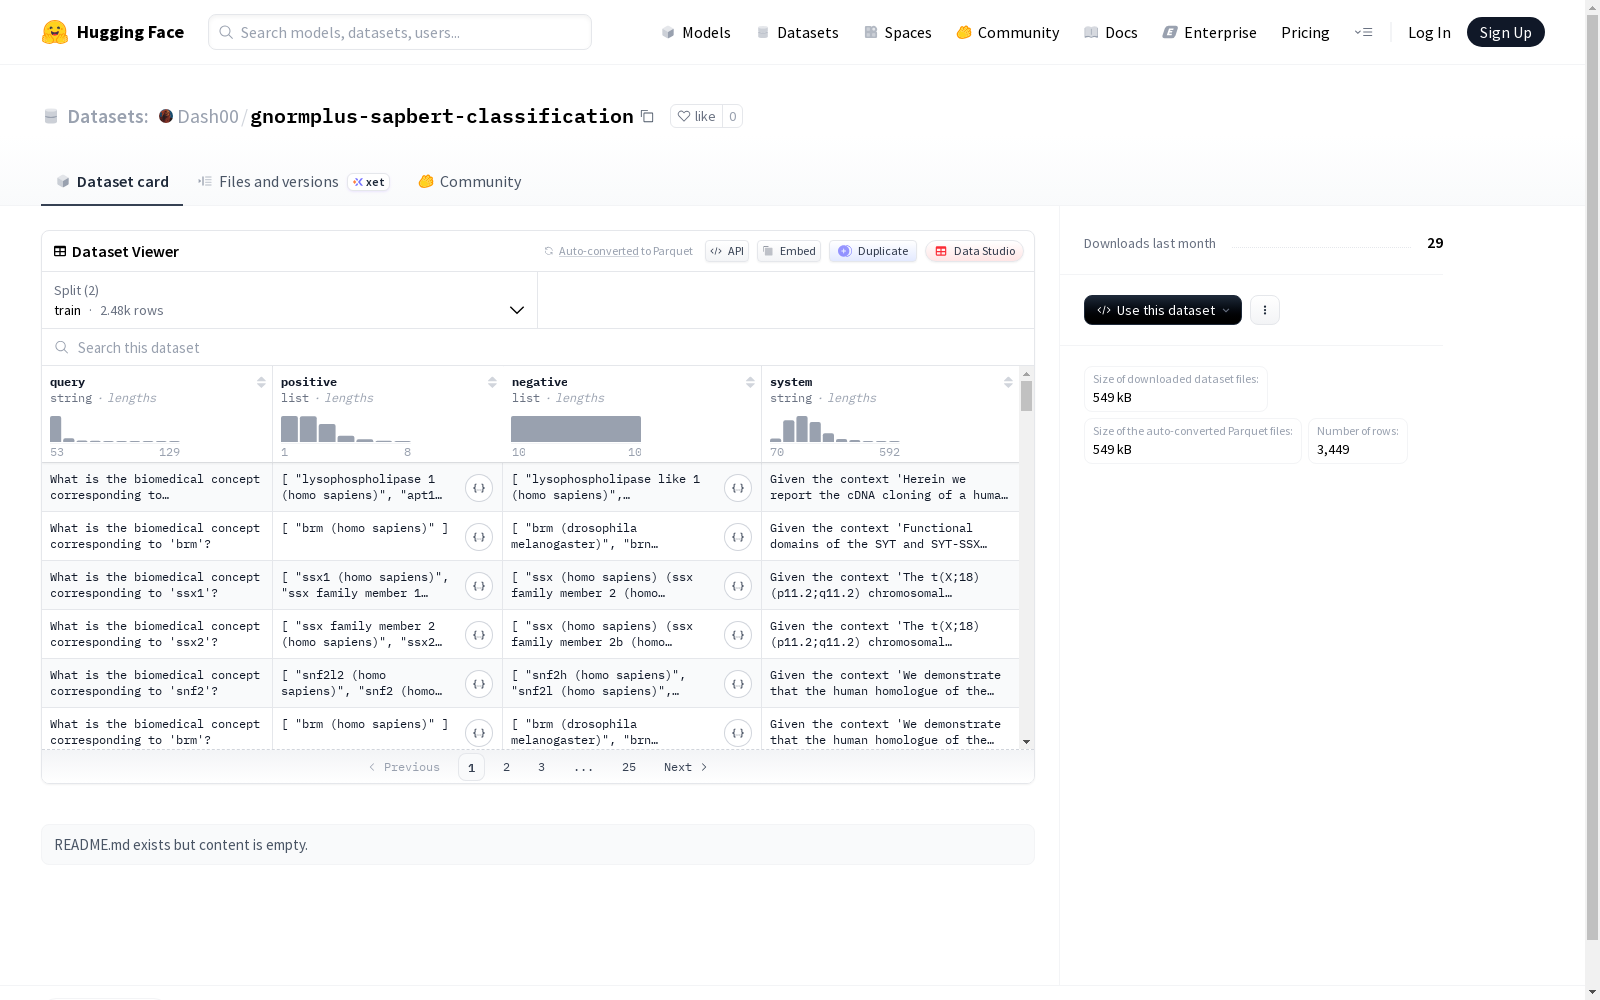
该数据集包含结构化文本数据,由2482个训练样本和967个测试样本组成,总大小约3.29MB。每个样本包含四个字段:1) 'query'(字符串类型,表示查询文本);2) 'positive'(字符串列表,表示相关正例);3) 'negative'(字符串列表,表示负例);4) 'system'(字符串类型,表示系统信息)。数据以train/test划分存储,可通过默认配置路径访问。适用于文本匹配、检索排序等任务的训练与评估。
This dataset contains structured textual data, consisting of 2482 training samples and 967 test samples, with a total size of approximately 3.29 MB. Each sample includes four fields: 1) 'query' (string type, representing the query text); 2) 'positive' (list of strings, representing relevant positive examples); 3) 'negative' (list of strings, representing negative examples); 4) 'system' (string type, representing system information). The data is stored in train/test splits and can be accessed via default configuration paths. It is suitable for training and evaluation of tasks such as text matching and retrieval ranking.
数据集概述
基本信息
- 数据集名称: gnormplus-sapbert-classification
- 托管平台: Hugging Face
- 数据集地址: https://huggingface.co/datasets/Dash00/gnormplus-sapbert-classification
数据集结构与特征
- 特征字段:
query: 字符串类型。positive: 字符串列表类型。negative: 字符串列表类型。system: 字符串类型。
数据划分与规模
- 数据划分:
train(训练集):- 样本数量: 2482
- 数据大小: 2084455 字节
test(测试集):- 样本数量: 967
- 数据大小: 1207472 字节
- 总体规模:
- 下载大小: 577270 字节
- 数据集总大小: 3291927 字节
配置与文件
- 默认配置名称:
default - 数据文件路径:
- 训练集:
data/train-* - 测试集:
data/test-*
- 训练集: