NVIDIA-Nemotron-IF-Chat-v2-rx
收藏资源简介:
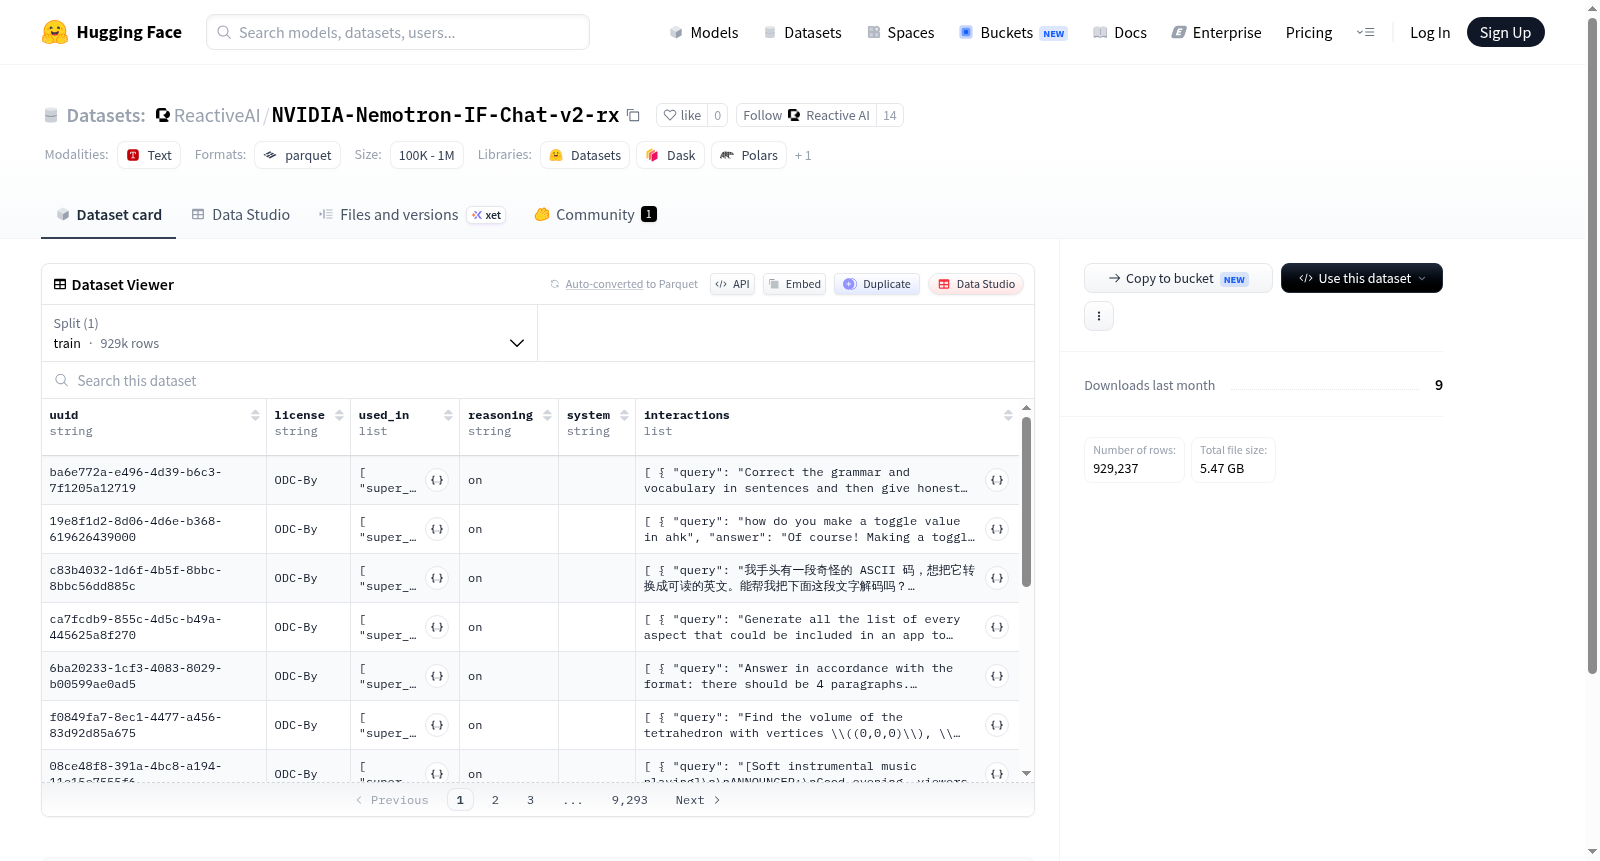
该数据集是一个大规模训练集,包含约92.9万条样本。每条样本由多个结构化字段组成:唯一标识符(uuid)、许可证信息(license)、用途列表(used_in)、推理过程描述(reasoning)、系统信息(system)以及一系列交互记录(interactions)。每个交互记录包括用户查询(query)、系统回答(answer)和模型思考过程(think)三个文本字段。该数据集适用于训练或评估具有推理和解释能力的对话系统或语言模型,特别关注思维链或逐步推理的任务场景。
This dataset is a large-scale training set containing approximately 929,000 samples. Each sample consists of multiple structured fields: unique identifier (uuid), license information (license), usage list (used_in), reasoning process description (reasoning), system information (system), and a series of interaction records (interactions). Each interaction record includes three text fields: user query (query), system response (answer), and model thinking process (think). This dataset is suitable for training or evaluating dialogue systems or language models with reasoning and explanation capabilities, with a particular focus on task scenarios involving chain-of-thought or step-by-step reasoning.
数据集名称为NVIDIA-Nemotron-IF-Chat-v2-rx,发布者为ReactiveAI,托管于Hugging Face平台。
数据集规模:
- 数据集总量约为9.7 GB(9,696,441,122字节)。
- 下载大小约为5.47 GB(5,468,208,623字节)。
- 包含929,237条样本,全部归属于训练集(train)。
数据字段结构: 每条样本包含以下字段:
- uuid(字符串):样本的唯一标识符。
- license(字符串):许可证信息。
- used_in(字符串列表):该样本被用于的用途或场景。
- reasoning(字符串):推理过程或逻辑说明。
- system(字符串):系统提示或系统设定信息。
- interactions(列表):包含多轮对话交互,每个交互项包含:
- query(字符串):用户提问。
- answer(字符串):模型回答。
- think(字符串):模型思考过程。
数据集用途: 可用于训练或评估对话式AI模型的指令跟随能力,特别是在包含推理过程的多轮对话场景中。