manojdahal191gom/claude-opus-4.6-10000x
收藏资源简介:
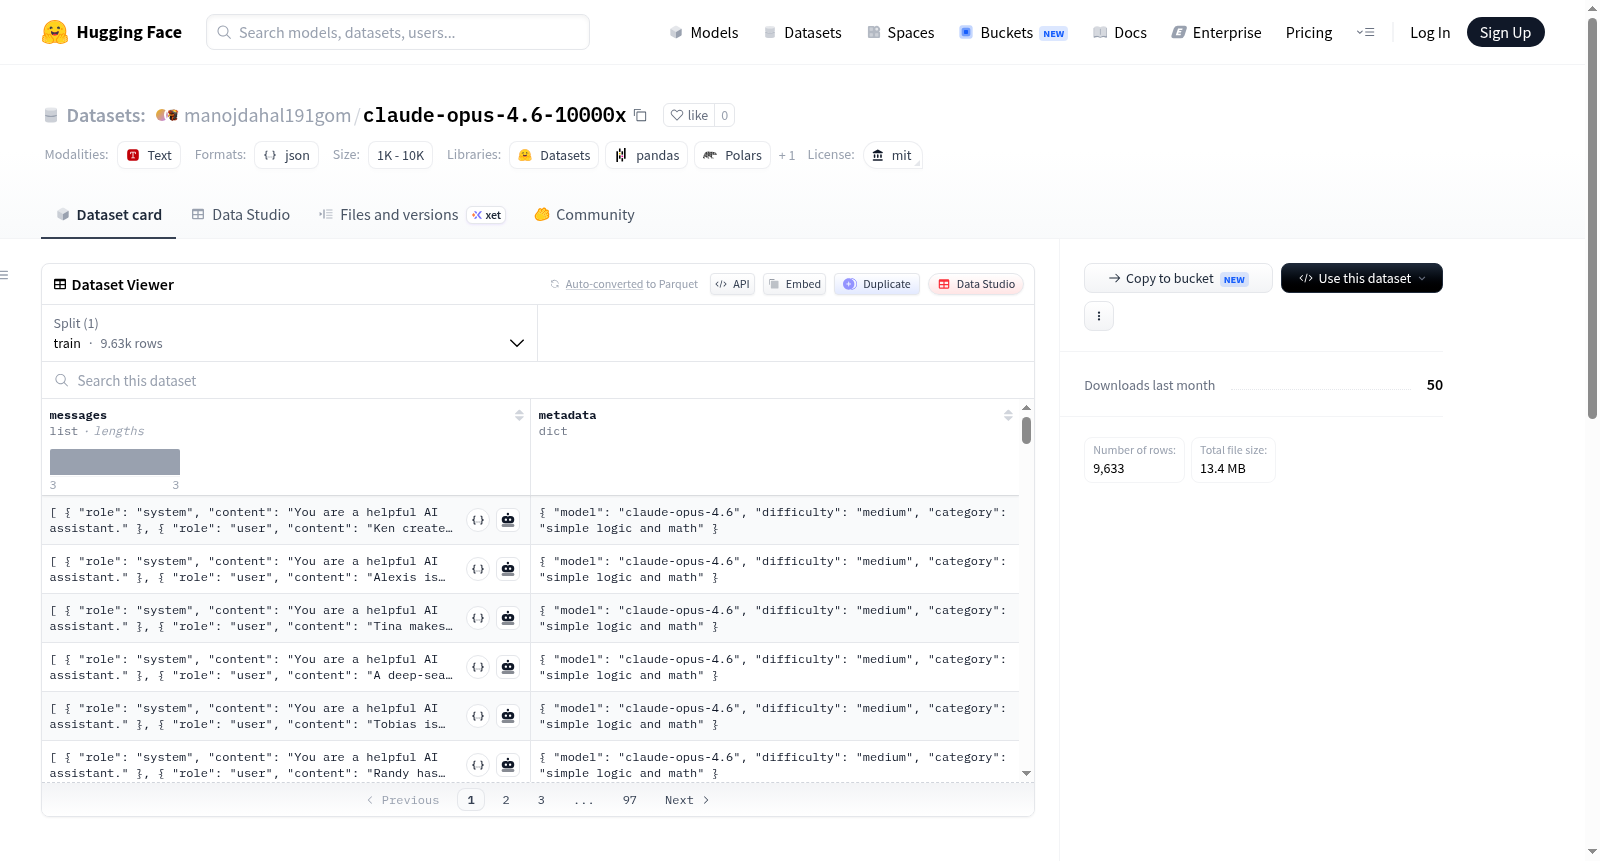
这是一个使用Claude Opus 4.6合成的高保真推理数据集,旨在捕获模型的内部思维链和推理轨迹,特别关注数学准确性和结构化逻辑演绎。该数据集结合了高难度数学问题(如GSM8K、MATH)、通用逻辑谜题和多步骤指令,每行数据包含一个隐藏的推理痕迹,模型在提供最终答案前会思考问题。通过让微调模型接触这些内部独白,模型可以学习过程导向的思维,而不仅仅是答案的模式匹配。数据集用于监督微调(SFT)和蒸馏,使较小的开源模型能够继承Claude Opus 4.6的复杂推理模式。微调于简单逻辑和数学有助于大语言模型建立认知基础,包括规则遵循(减少幻觉)、逐步验证(将复杂问题分解为可验证单元)和跨领域泛化(提升编码、法律分析和结构化写作等任务的能力)。
This is a high-fidelity reasoning dataset synthesized using Claude Opus 4.6, designed to capture the internal chain-of-thought and reasoning trajectories of models, with a particular focus on mathematical accuracy and structured logical deduction. This dataset combines high-difficulty mathematical problems (e.g., GSM8K, MATH), general logical puzzles, and multi-step instructions. Each row of data contains a hidden reasoning trace that records the model's thinking process before generating the final answer. By exposing fine-tuned models to these internal monologues, the models can learn process-oriented thinking rather than merely pattern-matching on final answers. This dataset is utilized for supervised fine-tuning (SFT) and knowledge distillation, enabling smaller open-source models to inherit the complex reasoning patterns of Claude Opus 4.6. Fine-tuning on simple logical and mathematical tasks helps large language models (LLMs) build foundational cognitive abilities, including rule adherence (reducing hallucinations), step-by-step verification (decomposing complex problems into verifiable units), and cross-domain generalization (enhancing performance on tasks such as coding, legal analysis, and structured writing).