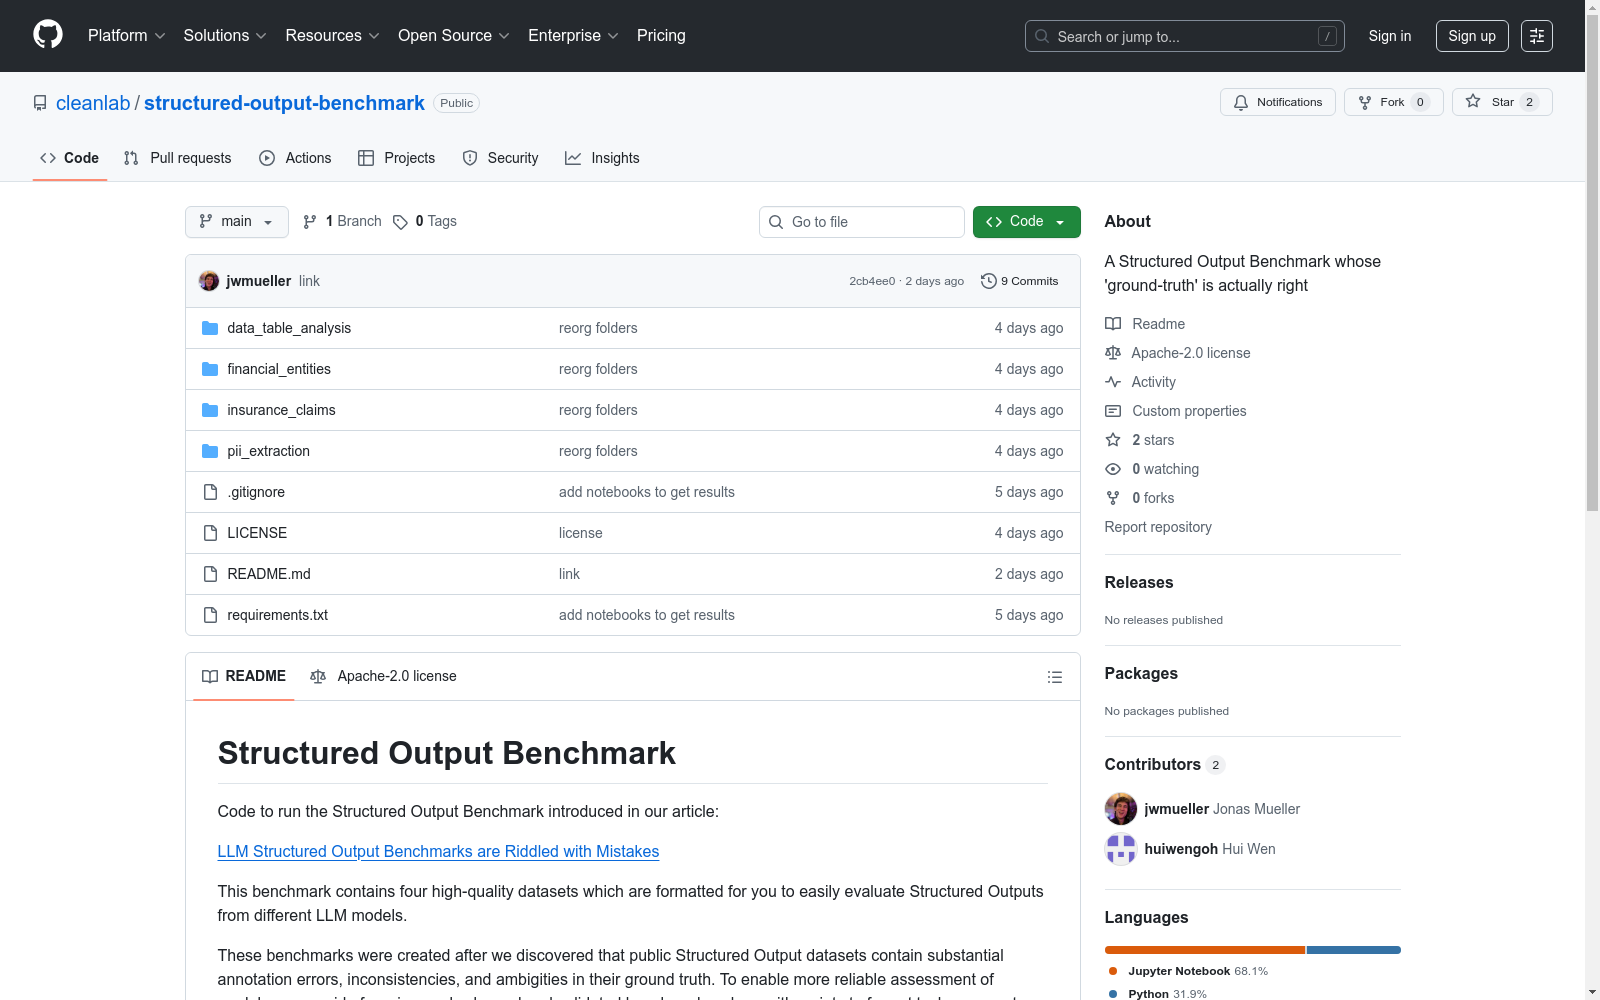
Structured Output Benchmark
收藏资源简介:
该基准包含四个高质量的数据集,这些数据集经过格式化,便于您轻松评估来自不同LLM模型的结构化输出。这些基准是在我们发现公共结构化输出数据集在其真实标注中存在大量标注错误、不一致和模糊性后创建的。为了实现对模型更可靠的评估,我们提供了四个经过严格清理和验证的基准,以及用于格式化任务、生成LLM响应和评估其正确性的脚本。
This benchmark comprises four high-quality datasets formatted to enable straightforward evaluation of structured outputs from diverse LLM models. This benchmark was developed following our discovery of extensive annotation errors, inconsistencies and ambiguities in the ground truth annotations of publicly available structured output datasets. To facilitate more reliable model evaluation, we have released four rigorously cleaned and validated datasets, alongside scripts for task formatting, LLM response generation and correctness assessment.
Structured Output Benchmark 数据集概述
数据集简介
此基准测试包含四个高质量数据集,旨在方便用户评估不同大语言模型的结构化输出能力。这些基准测试是在发现公开的结构化输出数据集存在大量标注错误、不一致和模糊性后创建的,旨在提供更可靠的模型评估。
数据集列表
| 数据集名称 | 描述 | 数据集链接 | 代码文件夹 |
|---|---|---|---|
| Data Table Analysis | 分析CSV表格并提取结构化元数据。 | https://huggingface.co/datasets/Cleanlab/data-table-analysis | data_table_analysis/ |
| Financial Entities Extraction | 从商业和金融文本中提取金融及上下文实体。 | https://huggingface.co/datasets/Cleanlab/fire-financial-ner-extraction | financial_entities/ |
| Insurance Claims Extraction | 从保险理赔文件中提取结构化字段。 | https://huggingface.co/datasets/Cleanlab/insurance-claims-extraction | insurance_claims/ |
| PII Extraction | 从文本中提取并分类不同类型的个人可识别信息。 | https://huggingface.co/datasets/Cleanlab/pii-extraction | pii_extraction/ |
数据集特点
- 高质量与已验证:所有数据集均经过严格清理和验证。
- 用途明确:专为评估大语言模型的结构化输出能力而设计。
- 配套工具:提供用于格式化任务、生成大语言模型响应和评估其正确性的脚本。