unjudged-nepali-legal-data-v7-instruct-test
收藏资源简介:
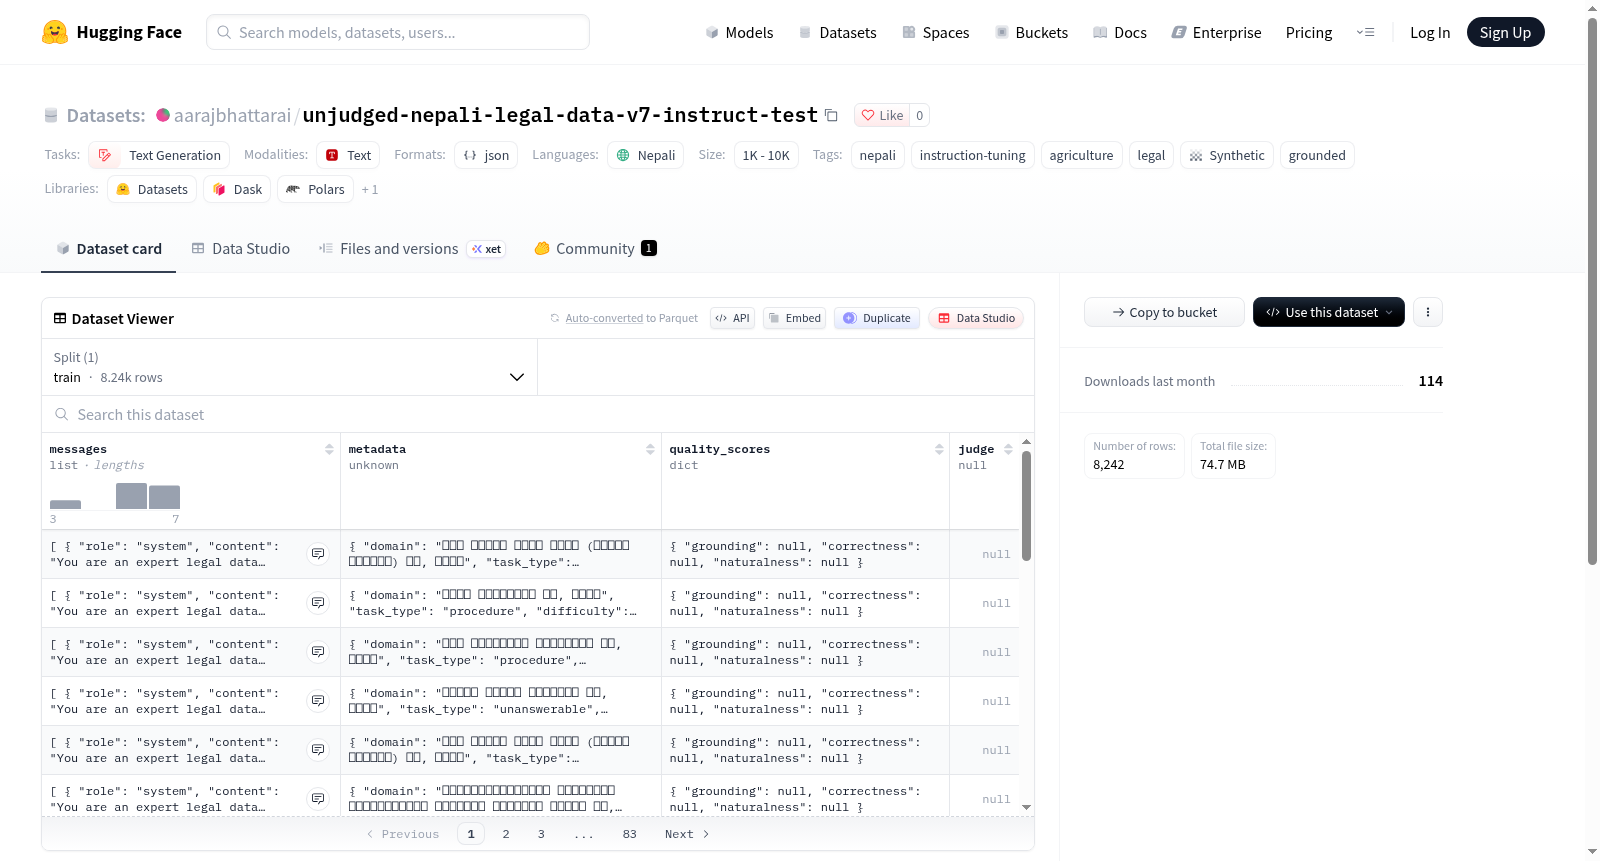
该数据集是一个尼泊尔语源文档锚定的合成指令微调数据集,当前标记为未判定(UNJUDGED)。它使用 NVIDIA NeMo Data Designer 从权威尼泊尔语文档生成,文档类型包括农业手册和法律文本,目标是构建与源文档紧密关联的尼泊尔语指令数据。数据中的回答严格基于源文档内容;对于无法回答的问题,数据会给出明确拒绝。记录采用 chat messages 格式,并附带 metadata 以及逐记录的 quality_scores。质量评分包括 grounding(源文档锚定)、correctness(正确性)和 naturalness(自然度),分值范围为 1-5,由 LLM-as-judge 评判。数据集按源文档组织,每个源文档对应一个 data/train-<shard>.jsonl 分片;重复运行时这些分片会以幂等方式覆盖。数据集语言为尼泊尔语(ne),任务类别为文本生成,标签涉及尼泊尔语、指令微调、农业、法律、合成、源锚定。注意事项:部分生成对话的 LLM 评判调用失败,导致其 quality_scores 为 null;使用前必须重新评判,且不应直接用于指令微调。
This dataset is a Nepali source-document-grounded synthetic instruction fine-tuning dataset, currently marked as UNJUDGED. It was generated from authoritative Nepali documents, including agricultural manuals and legal texts, using NVIDIA NeMo Data Designer, aiming to build Nepali instruction data tightly linked to source documents. Answers in the data are strictly based on source document content; for questions that cannot be answered, the data provides an explicit refusal. Records use the chat messages format and include metadata and per-record quality_scores. The quality scores include grounding (source-document grounding), correctness, and naturalness, with values from 1 to 5, judged by LLM-as-judge. The dataset is organized by source document, with each source document corresponding to one data/train-<shard>.jsonl shard; repeated runs overwrite these shards idempotently. The dataset language is Nepali (ne), the task category is text generation, and the tags involve Nepali, instruction fine-tuning, agriculture, law, synthetic, and source-grounded. Note: some LLM judge calls for generated conversations failed, causing their quality_scores to be null; before use, they must be re-judged, and the data should not be directly used for instruction fine-tuning.
数据集概述
- 数据集页面:https://huggingface.co/datasets/aarajbhattarai/unjudged-nepali-legal-data-v7-instruct-test
- 数据集名称:aarajbhattarai/unjudged-nepali-legal-data-v7-instruct-test
- 标题:Nepali Source-Grounded Instruction Dataset — UNJUDGED
基本属性
- 语言:ne
- 任务类别:text-generation
标签
- nepali
- instruction-tuning
- agriculture
- legal
- synthetic
- grounded
数据生成与组成
- 合成尼泊尔语指令微调数据。
- 使用 NVIDIA NeMo Data Designer 从权威尼泊尔语文档生成,来源文档包括农业手册和法律文本。
- 答案严格基于来源;不可回答问题会获得明确拒答。
- 记录使用聊天
messages格式,并包含metadata。 - 每条记录包含
quality_scores:grounding / correctness / naturalness,评分范围 1-5,由 LLM-as-judge 产生。 - 每个源文档对应一个 JSONL 分片文件,分片文件名模式为
train-<shard>.jsonl;重新运行时分片会幂等覆盖。
质量与使用警告
- LLM-judge 调用失败的生成对话,其
quality_scores为 null。 - 任何使用前需重新评判。
- 不要按原样用于指令微调。