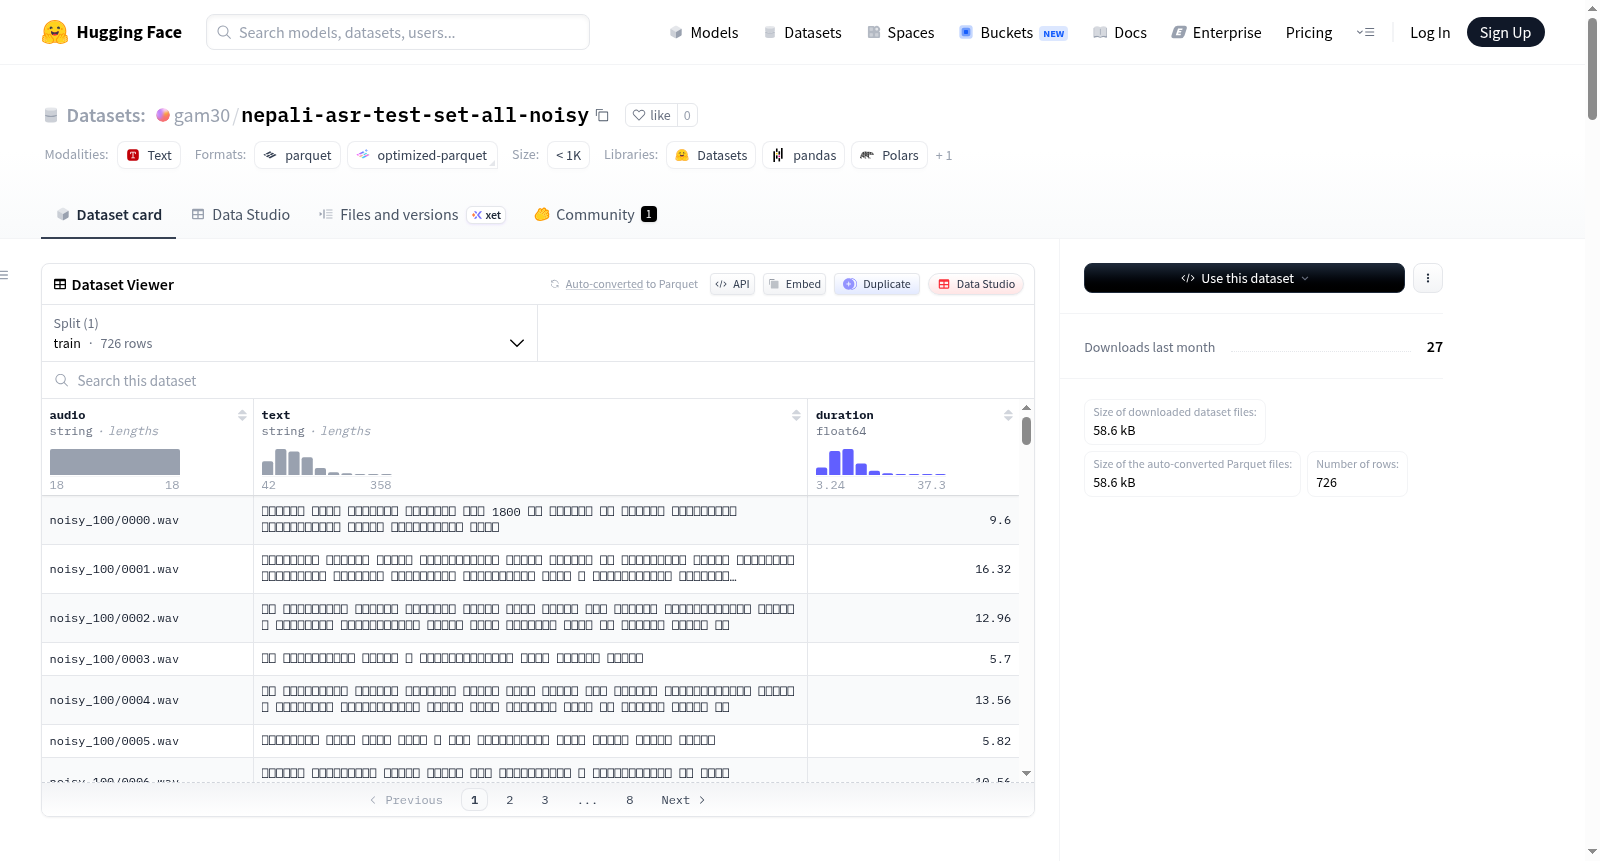
nepali-asr-test-set-all-noisy
收藏资源简介:
Nepali ASR Test Set - All Noisy 是一个专为自动语音识别(ASR)研究和测试而设计的尼泊尔语音数据集,包含726个带有合成噪声的语音样本。这些样本源自Google的FLEURS测试集,经过噪声增强处理,模拟了真实世界中的挑战性声学环境。数据集中的每个样本包含三个主要特征:音频文件路径(WAV格式,16 kHz采样率)、尼泊尔语文本转录(Unicode Devanagari-derived脚本)和音频时长(秒)。所有音频样本均混入了环境噪声(如人群、交通、建筑和风声),信噪比(SNR)为40%。该数据集适用于鲁棒ASR模型训练、噪声鲁棒性测试、领域适应、基准评估和语音增强研究。数据集总时长约2.28小时,平均每个样本时长22.4秒,采用CC-BY-4.0许可。
Nepali ASR Test Set - All Noisy is a Nepali speech dataset designed exclusively for automatic speech recognition (ASR) research and testing, consisting of 726 speech samples with synthetic noise. Derived from Google's FLEURS test set, these samples have undergone noise augmentation to simulate challenging real-world acoustic environments. Each sample in the dataset includes three core attributes: audio file path (in WAV format with a 16 kHz sampling rate), Nepali text transcription in Unicode Devanagari-derived script, and audio duration measured in seconds. All audio samples are mixed with environmental noises such as crowd chatter, traffic, construction work, and wind, with a signal-to-noise ratio (SNR) of 40%. This dataset is applicable for robust ASR model training, noise robustness testing, domain adaptation, benchmark evaluation, and speech enhancement research. The total duration of the dataset is approximately 2.28 hours, with an average duration of 22.4 seconds per sample, and it is licensed under CC-BY-4.0.
Nepali ASR Test Set - All Noisy 数据集概述
数据集基本信息
- 数据集名称:Nepali ASR Test Set - All Noisy
- 发布者:sangam
- 发布年份:2026
- 数据集ID:
gam30/nepali-asr-test-set-all-noisy - 最后更新:2024
- 数据版本:1.0
- 许可证:CC-BY-4.0 (继承自FLEURS数据集)
数据内容与来源
- 语言:尼泊尔语 (Nepali)
- 数据来源:源自FLEURS (Google Federated Learning for Emoji Recognition via Speech) 测试集
- 样本数量:726个音频样本
- 数据划分:仅包含一个“train”划分
- 总音频时长:约2.28小时
- 平均样本时长:约22.4秒
- 最短样本时长:约9.6秒
- 最长样本时长:约37.2秒
音频特征
- 音频格式:WAV
- 采样率:16,000 Hz (16 kHz)
- 声道:单声道 (Mono)
- 噪声覆盖:100%的样本均包含合成噪声
- 信噪比:40%噪声混合比 (Signal-to-Noise Ratio at 40%)
噪声特性
- 噪声类型:合成环境噪声
- 噪声来源:
- 人群噪声 (背景对话、环境杂音)
- 交通噪声 (车辆引擎、喇叭、道路声音)
- 施工噪声 (机械、工具、设备)
- 风声 (室外风、空气流动)
数据集结构特征
每个样本包含以下三个字段:
audio(字符串):带噪声的WAV音频文件路径。格式为noisy_100/{ID:04d}.wav,例如noisy_100/0000.wav。text(字符串):语音的完整尼泊尔语转录文本,使用Unicode天城文衍生文字。duration(浮点数):音频时长,单位为秒。
技术规格
- 下载大小:58,714字节
- 数据集大小:261,808字节
- 特征定义:
audio:字符串类型text:字符串类型duration:float64类型
主要用途
本数据集适用于:
- 鲁棒性ASR模型训练:在带噪声语音上训练模型。
- 噪声鲁棒性测试:评估ASR系统在噪声条件下的性能。
- 领域自适应:针对尼泊尔语对预训练模型进行微调。
- 基准评估:创建公平性和鲁棒性基准。
- 语音增强研究:测试去噪技术。
引用信息
如需在研究中引用此数据集,请使用: bibtex @dataset{nepali_asr_noisy_2024, title={Nepali ASR Test Set - All Noisy}, author={sangam}, year={2026}, publisher={Hugging Face}, url={https://huggingface.co/datasets/gam30/nepali-asr-test-set-all-noisy} }
原始FLEURS数据集引用: bibtex @dataset{fleurs2022, title={FLEURS: Few-shot Learning Evaluation of Universal Representations of Speech}, author={Conneau, Alexei and others}, year={2022}, publisher={Google Research} }
质量保证
- ✓ 所有726个音频文件均已验证并可访问。
- ✓ 所有转录文本均为UTF-8 Unicode格式。
- ✓ 时长元数据已计算并验证。
- ✓ 元数据为JSONL格式,具有一致的模式。
相关资源
- FLEURS数据集:https://github.com/google/fleurs