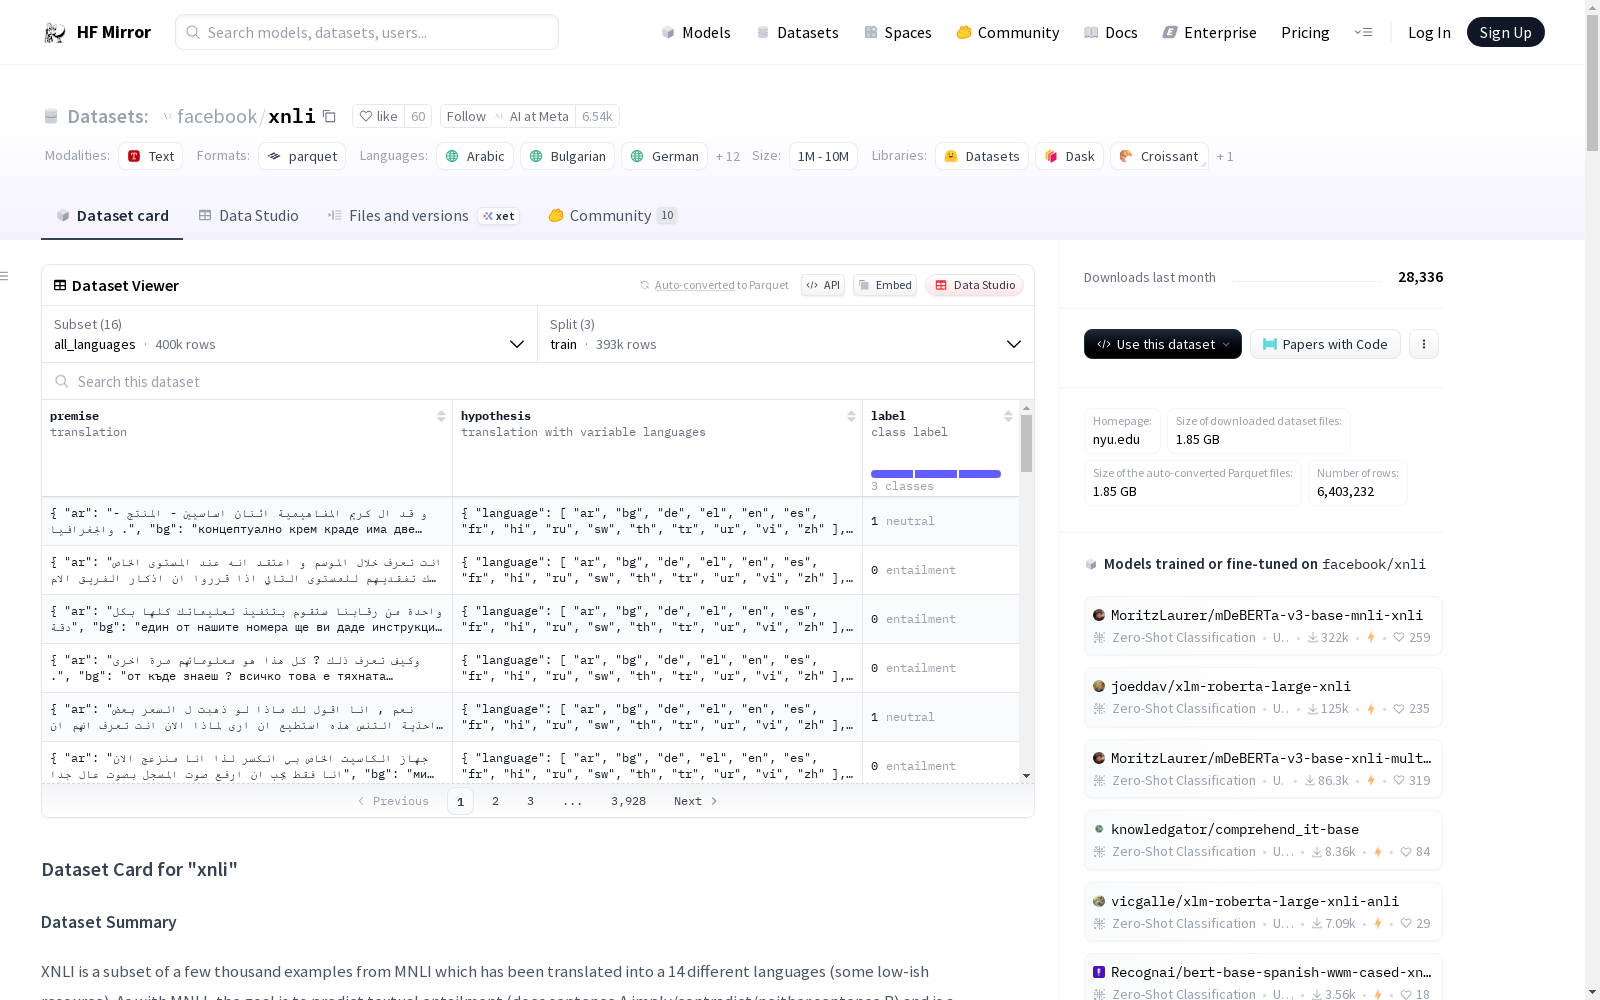
facebook/xnli
收藏资源简介:
XNLI数据集是MNLI数据集的一个子集,包含数千个例子,已被翻译成14种不同的语言(包括一些资源较少的语言)。与MNLI一样,目标是预测文本蕴含关系(句子A是否蕴含/矛盾/中立于句子B),这是一个分类任务(给定两个句子,预测三个标签之一)。数据集支持15种语言,包括阿拉伯语、保加利亚语、德语、希腊语、英语、西班牙语、法语、印地语、俄语、斯瓦希里语、泰语、土耳其语、乌尔都语、越南语和中文。
The XNLI dataset is a subset of the MNLI dataset, containing thousands of examples translated into 14 distinct languages, including some low-resource languages. Similar to MNLI, its objective is to predict textual entailment (whether Sentence A entails, contradicts, or is neutral towards Sentence B), which is a classification task where given two sentences, one of three labels is predicted. The dataset supports 15 languages in total, including Arabic, Bulgarian, German, Greek, English, Spanish, French, Hindi, Russian, Swahili, Thai, Turkish, Urdu, Vietnamese, and Chinese.
数据集概述
数据集描述
语言
- 支持的语言包括:阿拉伯语(ar)、保加利亚语(bg)、德语(de)、希腊语(el)、英语(en)、西班牙语(es)、法语(fr)、印地语(hi)、俄语(ru)、斯瓦希里语(sw)、泰语(th)、土耳其语(tr)、乌尔都语(ur)、越南语(vi)、中文(zh)。
数据集信息
-
配置名称:all_languages
- 特征:
- premise:多语言字符串变量,支持的语言包括:阿拉伯语、保加利亚语、德语、希腊语、英语、西班牙语、法语、印地语、俄语、斯瓦希里语、泰语、土耳其语、乌尔都语、越南语、中文。
- hypothesis:多语言字符串变量,支持的语言包括:阿拉伯语、保加利亚语、德语、希腊语、英语、西班牙语、法语、印地语、俄语、斯瓦希里语、泰语、土耳其语、乌尔都语、越南语、中文。
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)。
- 分割:
- train:392702个样本,1581471691字节
- test:5010个样本,19387432字节
- validation:2490个样本,9566179字节
- 下载大小:963942271字节
- 数据集大小:1610425302字节
- 特征:
-
配置名称:ar
- 特征:
- premise:字符串
- hypothesis:字符串
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)。
- 分割:
- train:392702个样本,107399614字节
- test:5010个样本,1294553字节
- validation:2490个样本,633001字节
- 下载大小:59215902字节
- 数据集大小:109327168字节
- 特征:
-
配置名称:bg
- 特征:
- premise:字符串
- hypothesis:字符串
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)。
- 分割:
- train:392702个样本,125973225字节
- test:5010个样本,1573034字节
- validation:2490个样本,774061字节
- 下载大小:66117878字节
- 数据集大小:128320320字节
- 特征:
-
配置名称:de
- 特征:
- premise:字符串
- hypothesis:字符串
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)。
- 分割:
- train:392702个样本,84684140字节
- test:5010个样本,996488字节
- validation:2490个样本,494604字节
- 下载大小:55973883字节
- 数据集大小:86175232字节
- 特征:
-
配置名称:el
- 特征:
- premise:字符串
- hypothesis:字符串
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)。
- 分割:
- train:392702个样本,139753358字节
- test:5010个样本,1704785字节
- validation:2490个样本,841226字节
- 下载大小:74551247字节
- 数据集大小:142299369字节
- 特征:
数据字段
-
all_languages:
- premise:多语言字符串变量
- hypothesis:多语言字符串变量
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)
-
ar:
- premise:字符串
- hypothesis:字符串
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)
-
bg:
- premise:字符串
- hypothesis:字符串
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)
-
de:
- premise:字符串
- hypothesis:字符串
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)
-
el:
- premise:字符串
- hypothesis:字符串
- label:分类标签,可能的值包括:entailment(0)、neutral(1)、contradiction(2)
数据分割
| 名称 | 训练集 | 验证集 | 测试集 |
|---|---|---|---|
| all_languages | 392702 | 2490 | 5010 |
| ar | 392702 | 2490 | 5010 |
| bg | 392702 | 2490 | 5010 |
| de | 392702 | 2490 | 5010 |
| el | 392702 | 2490 | 5010 |