stefanocarrera/autophagycode_D_he_train-mercury_Qwen3-4B_strategy_trust_t1.25_g6_run0_metrics
收藏资源简介:
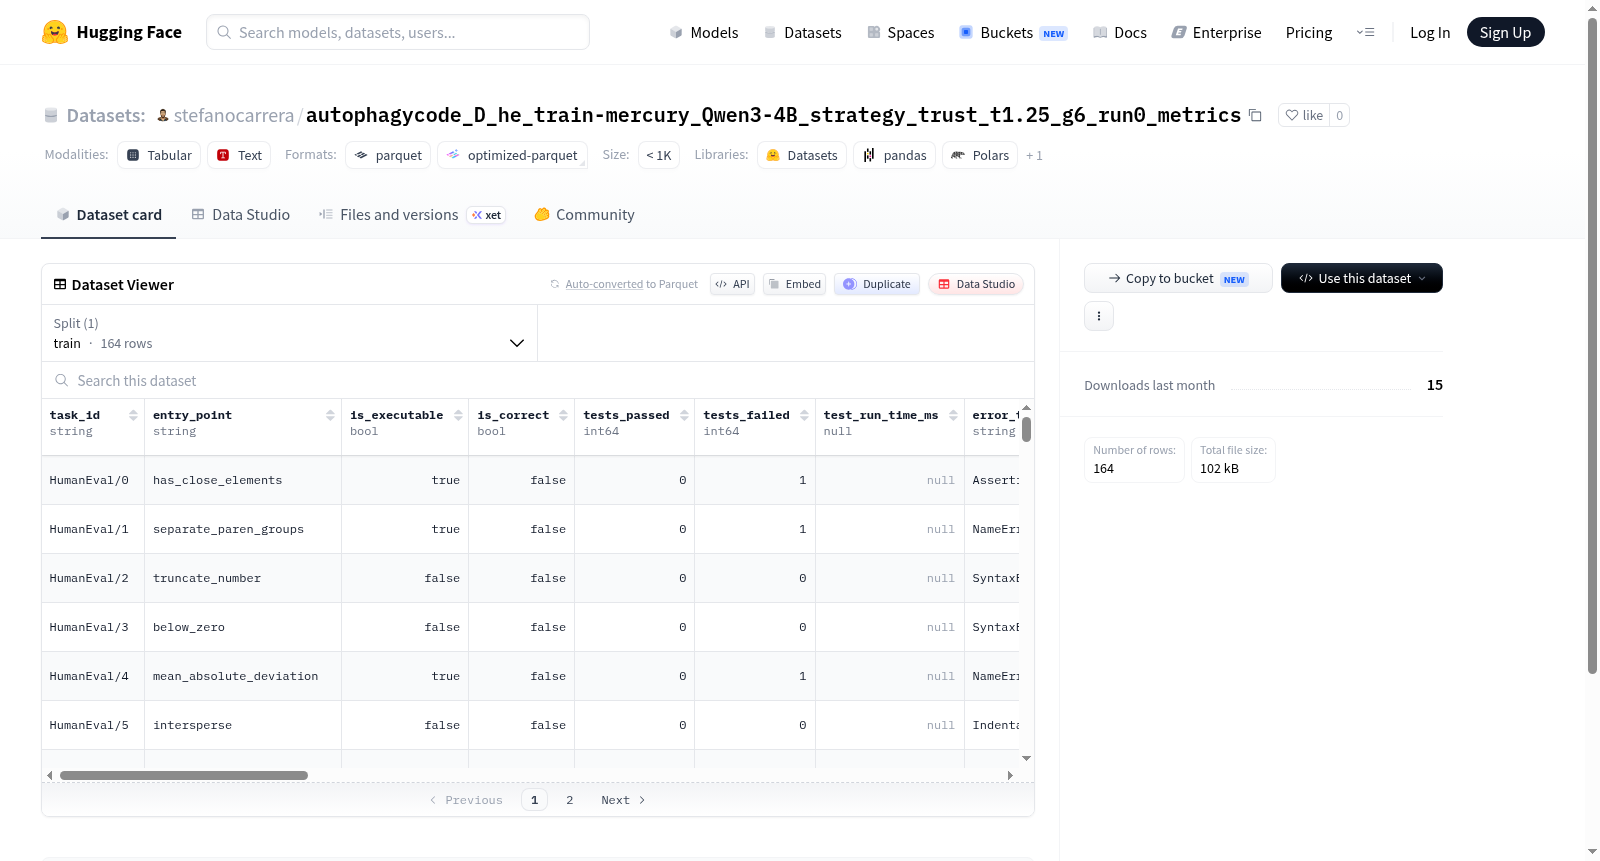
该数据集是一个用于代码分析和测试评估的数据集,包含编程任务的相关信息。数据集中的每条记录代表一个代码任务,具有任务ID、入口点、可执行性、正确性、通过和失败的测试数量等字段。此外,还包括代码复杂度度量(如Halstead度量、圈复杂度、可维护性指数)、代码行数(LOC和SLOC)、注释百分比、词汇多样性(TTR)、香农熵等特征。这些特征用于评估代码质量、可读性和复杂性。数据集分为训练集,包含164个示例,总大小约231KB,适用于机器学习或统计分析任务,例如预测代码正确性或分析代码属性。
This dataset is intended for code analysis and test evaluation, encompassing information related to programming tasks. Each record in the dataset represents a single code task, with fields including task ID, entry point, executability, correctness, counts of passed and failed tests, and others. Additionally, it includes code complexity metrics such as Halstead metrics, cyclomatic complexity, and maintainability index, alongside features like lines of code (LOC and SLOC), comment percentage, lexical diversity (TTR), and Shannon entropy. These features are used to assess code quality, readability, and complexity. The dataset is split into a training set, which contains 164 examples with a total size of approximately 231 KB. It is suitable for machine learning or statistical analysis tasks, such as predicting code correctness or analyzing code attributes.