CulturalGround-dpo
收藏资源简介:
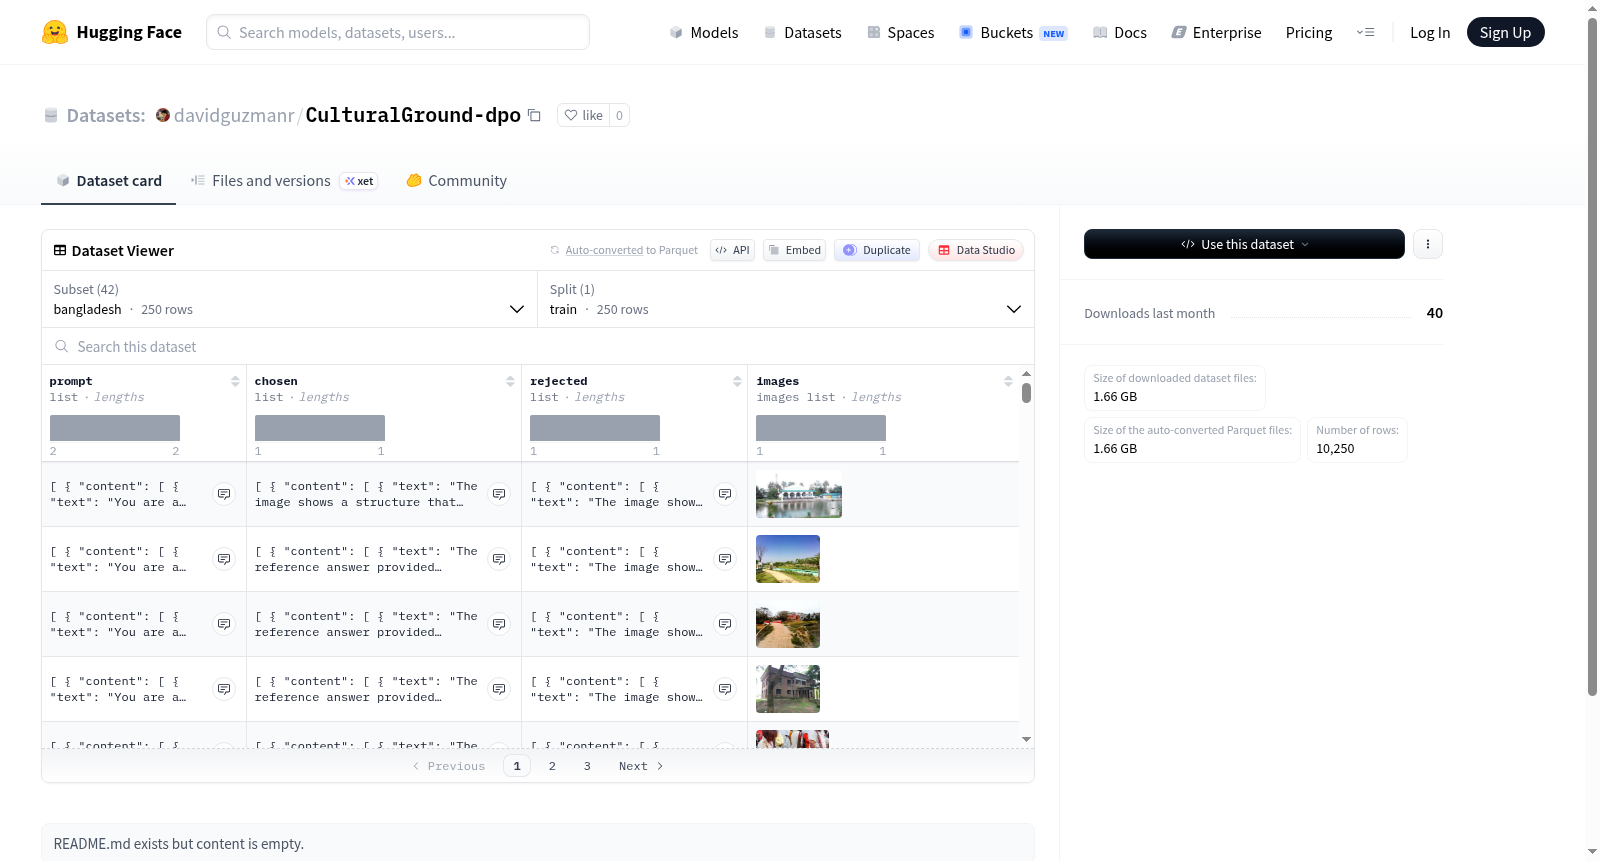
该数据集包含多个国家特定配置的对话数据,每个配置包含以下特征字段:'prompt'(提示)、'chosen'(采纳回复)和'rejected'(拒绝回复),这三个字段均包含'content'子字段(含'text'文本和'type'类型)以及'role'角色字段;此外还包含'images'图像列表字段。所有数据均采用'train'训练集划分,每个国家数据集包含250个样本,并标注了具体的字节大小。数据集适用于对话系统训练、偏好学习等自然语言处理任务。
This dataset comprises multiple country-specific conversational datasets. Each dataset includes the following feature fields: "prompt", "chosen" and "rejected". All three fields contain a "content" sub-field, which includes "text" and "type" sub-entries, as well as a "role" field. Additionally, an "images" list field is included. All data is split into the "train" set, with each country-specific dataset containing 250 samples, and their specific byte sizes are annotated. This dataset is applicable to natural language processing tasks such as conversational system training and preference learning.
CulturalGround-dpo 数据集概述
数据集基本信息
- 数据集名称: CulturalGround-dpo
- 托管地址: https://huggingface.co/datasets/davidguzmanr/CulturalGround-dpo
- 配置数量: 31个独立的国家/地区配置
数据集配置列表
数据集包含以下国家/地区的配置:
- bangladesh
- brazil
- bulgaria
- china
- czechia
- egypt
- ethiopia
- france
- germany
- greece
- india
- indonesia
- iran
- ireland
- israel
- italy
- japan
- mexico
- mongolia
- netherlands
- nigeria
- norway
- pakistan
- poland
- portugal
- romania
- russia
- rwanda
数据结构
特征字段
所有配置共享相同的特征结构:
- prompt: 提示信息
content: 内容列表text: 字符串类型type: 字符串类型
role: 字符串类型
- chosen: 优选回答
content: 内容列表text: 字符串类型type: 字符串类型
role: 字符串类型
- rejected: 拒绝回答
content: 内容列表text: 字符串类型type: 字符串类型
role: 字符串类型
- images: 图像列表
数据划分
- 划分名称: train
- 每个配置样本数: 250个示例
- 总样本数: 31个配置 × 250个示例 = 7,750个示例
存储信息
各配置存储详情
| 配置名称 | 数据集大小(字节) | 下载大小(字节) |
|---|---|---|
| bangladesh | 47,244,801 | 47,248,283 |
| brazil | 39,201,231 | 39,204,768 |
| bulgaria | 38,339,436 | 38,343,913 |
| china | 43,121,790 | 43,125,018 |
| czechia | 46,773,585 | 46,776,684 |
| egypt | 55,388,176 | 55,393,207 |
| ethiopia | 38,586,064 | 38,588,981 |
| france | 41,685,407 | 41,687,607 |
| germany | 41,746,228 | 41,748,589 |
| greece | 38,280,555 | 38,282,686 |
| india | 40,256,688 | 40,259,616 |
| indonesia | 37,527,831 | 37,532,150 |
| iran | 34,050,722 | 34,053,517 |
| ireland | 37,074,942 | 37,077,998 |
| israel | 33,247,088 | 33,249,036 |
| italy | 39,367,882 | 39,371,435 |
| japan | 40,937,793 | 40,940,667 |
| mexico | 55,789,938 | 55,793,720 |
| mongolia | 35,996,134 | 35,998,024 |
| netherlands | 38,460,243 | 38,463,576 |
| nigeria | 35,785,652 | 35,788,419 |
| norway | 37,137,641 | 37,140,567 |
| pakistan | 35,584,374 | 35,587,874 |
| poland | 38,685,866 | 38,687,905 |
| portugal | 39,893,995 | 39,899,270 |
| romania | 35,741,388 | 35,743,512 |
| russia | 46,020,851 | 46,024,196 |
| rwanda | 数据不完整 | 数据不完整 |
数据集用途
- 数据类型: 多模态数据(文本+图像)
- 数据格式: 适用于直接偏好优化(DPO)训练
- 应用场景: 跨文化对话生成模型的偏好学习