cryptpesa/kalenjin-speech-full
收藏资源简介:
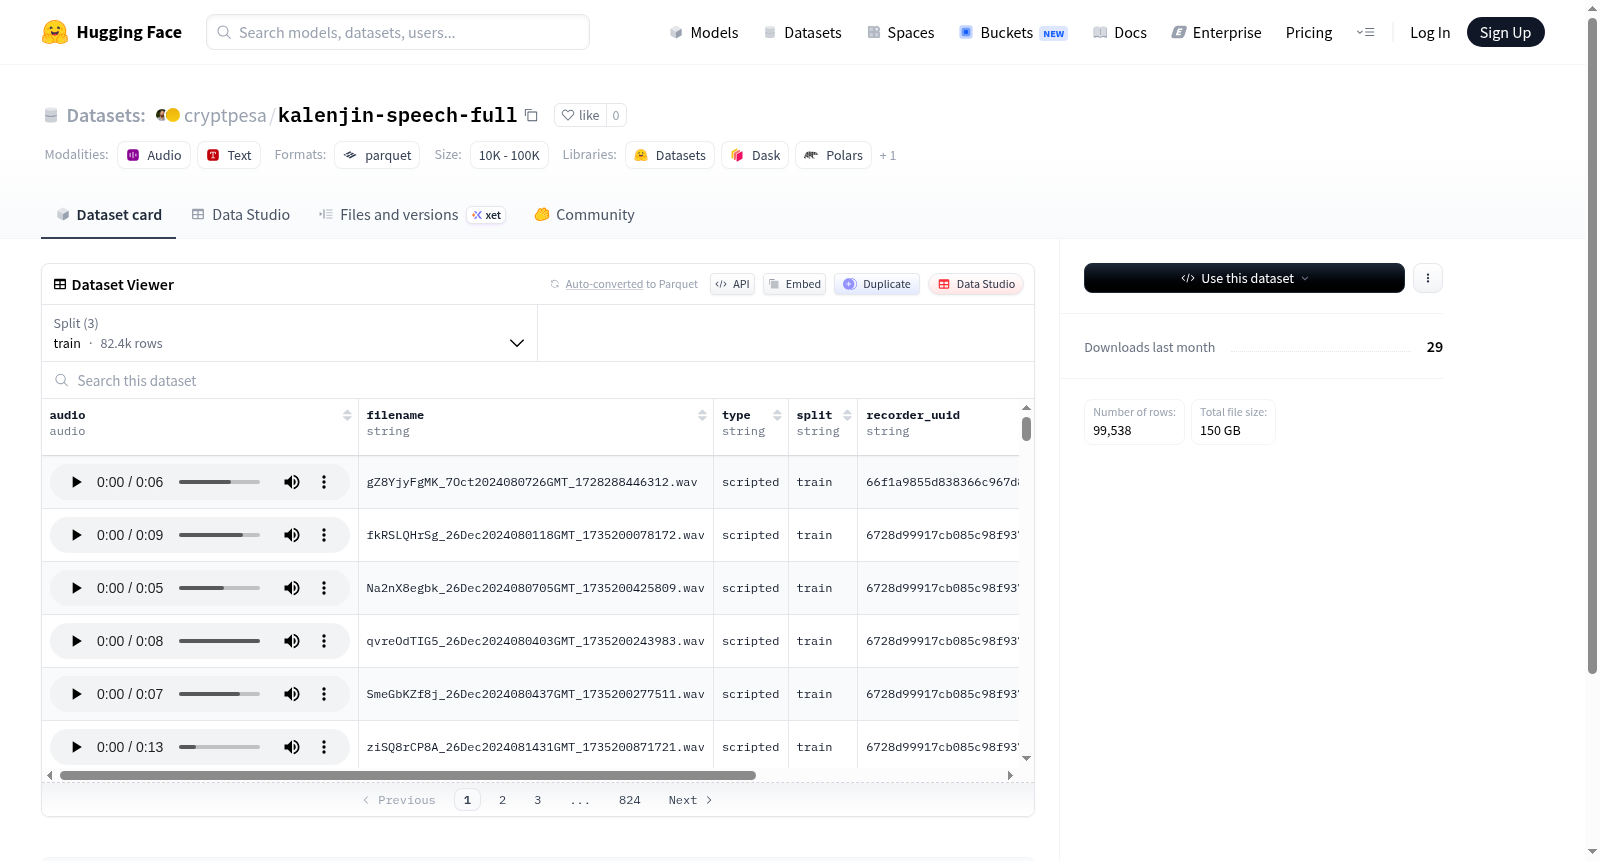
该数据集是一个多语言音频转录数据集,包含音频文件及其对应的转录文本,适用于语音识别任务。音频特征包括采样率为16kHz的音频数据,以及文件名、类型(如说话者或环境信息)、数据分割(训练、验证、测试)、记录者唯一标识符、领域分类、转录文本和语言标签。数据集总大小约为164GB,下载尺寸约为150GB,包含训练集(82,378个样本)、验证集(13,845个样本)和测试集(3,315个样本),支持多语言处理和分析。
This dataset is a multilingual audio transcription dataset containing audio files and their corresponding transcriptions, suitable for speech recognition tasks. The audio features include audio data with a sampling rate of 16 kHz, as well as file names, types (such as speaker or environment information), data splits (training, validation, test), unique identifiers of recorders, domain classifications, transcriptions and language tags. The total size of the dataset is approximately 164 GB, and the download size is approximately 150 GB. It consists of a training set (82,378 samples), a validation set (13,845 samples) and a test set (3,315 samples), and supports multilingual processing and analysis.