qwen-vl-lingala-dataset-augmented
收藏资源简介:
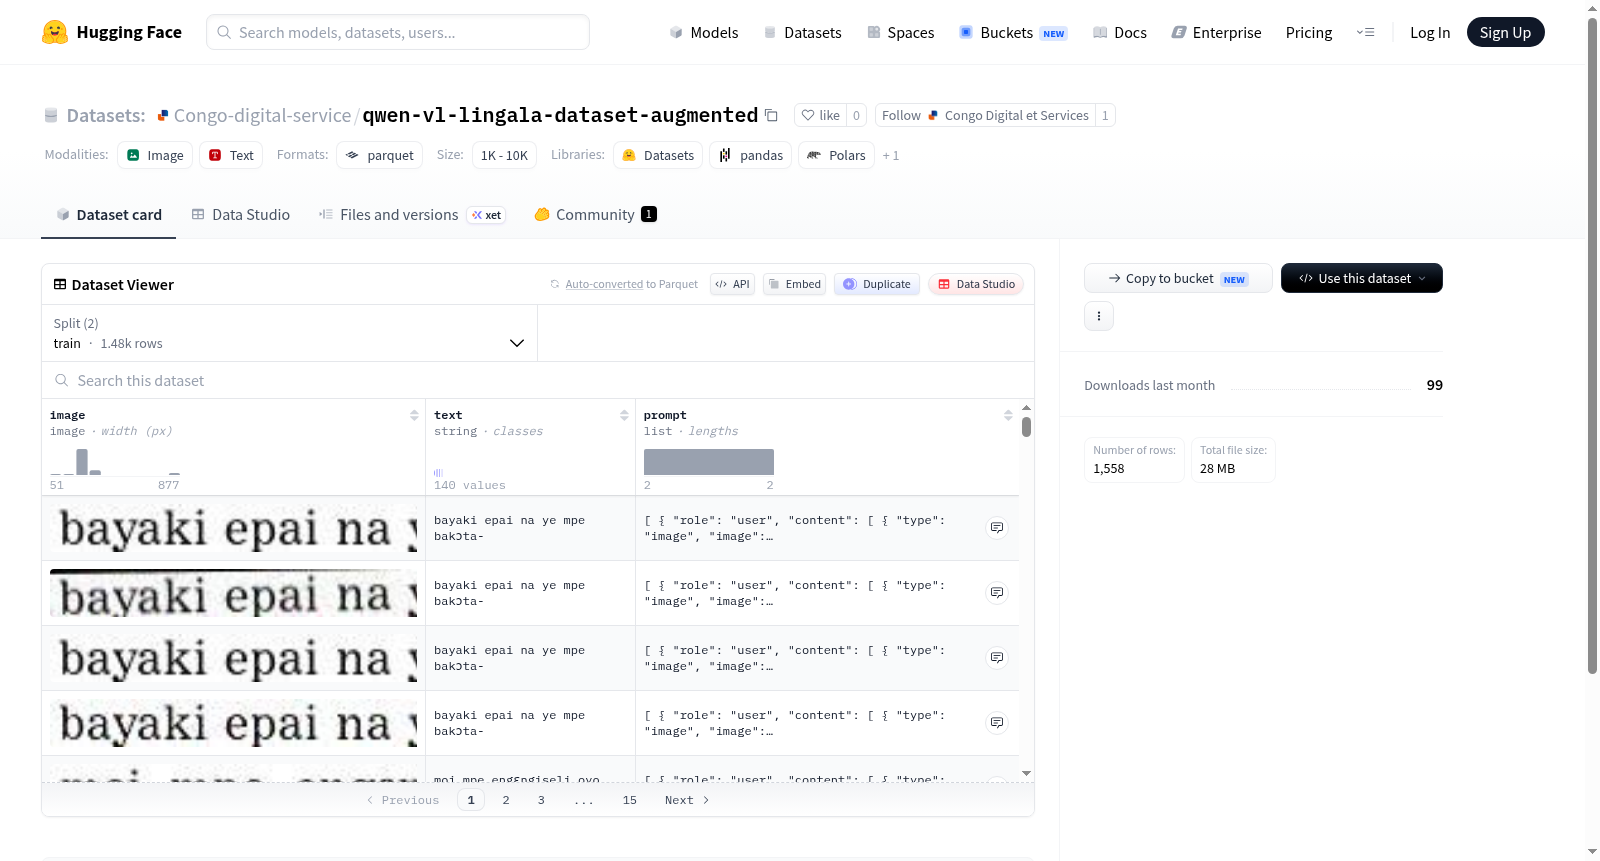
该数据集是一个多模态对话数据集,包含图像和文本两种模态。每个样本由图像(image)、文本(text)和对话提示(prompt)组成,其中prompt采用结构化对话格式,包含角色(role)和内容(content),内容可包含类型(type)、图像(image)和文本(text)字段。数据集划分为训练集(1476个样本)和测试集(82个样本),适用于多模态对话系统的训练与评估任务。
This dataset is a multimodal dialogue dataset, containing two modalities: image and text. Each sample consists of an image, text, and a dialogue prompt, where the prompt adopts a structured dialogue format containing roles and content, and the content can include type, image, and text fields. The dataset is divided into a training set (1476 samples) and a test set (82 samples), suitable for training and evaluating multimodal dialogue systems.
数据集概述:qwen-vl-lingala-dataset-augmented
基本信息
- 数据集地址:https://huggingface.co/datasets/Congo-digital-service/qwen-vl-lingala-dataset-augmented
- 数据集名称:qwen-vl-lingala-dataset-augmented
数据特征
该数据集包含以下三个特征字段:
- image:图像数据,类型为 image
- text:文本数据,类型为 string
- prompt:包含角色(role,string类型)和内容(content)的列表。其中内容进一步包含:
- type:类型标识(string)
- image:图像相关字符串(string)
- text:文本字符串(string)
数据划分
数据集分为训练集和测试集两个部分:
| 划分 | 样本数 | 字节大小 |
|---|---|---|
| 训练集(train) | 1,476 | 27,784,041 字节 |
| 测试集(test) | 82 | 1,122,191 字节 |
数据集规模
- 总下载大小:28,828,327 字节(约 27.5 MB)
- 总数据集大小:28,906,232 字节(约 27.6 MB)
- 总样本数:1,558 个
配置信息
- 配置名称:default(默认配置)
- 数据文件路径:
- 训练集:
data/train-* - 测试集:
data/test-*
- 训练集:
数据用途
该数据集包含图像和文本信息,包含 prompt 结构,适用于视觉语言模型(如 Qwen-VL)的训练和评估任务,涉及林加拉语(Lingala)相关的多模态数据处理。