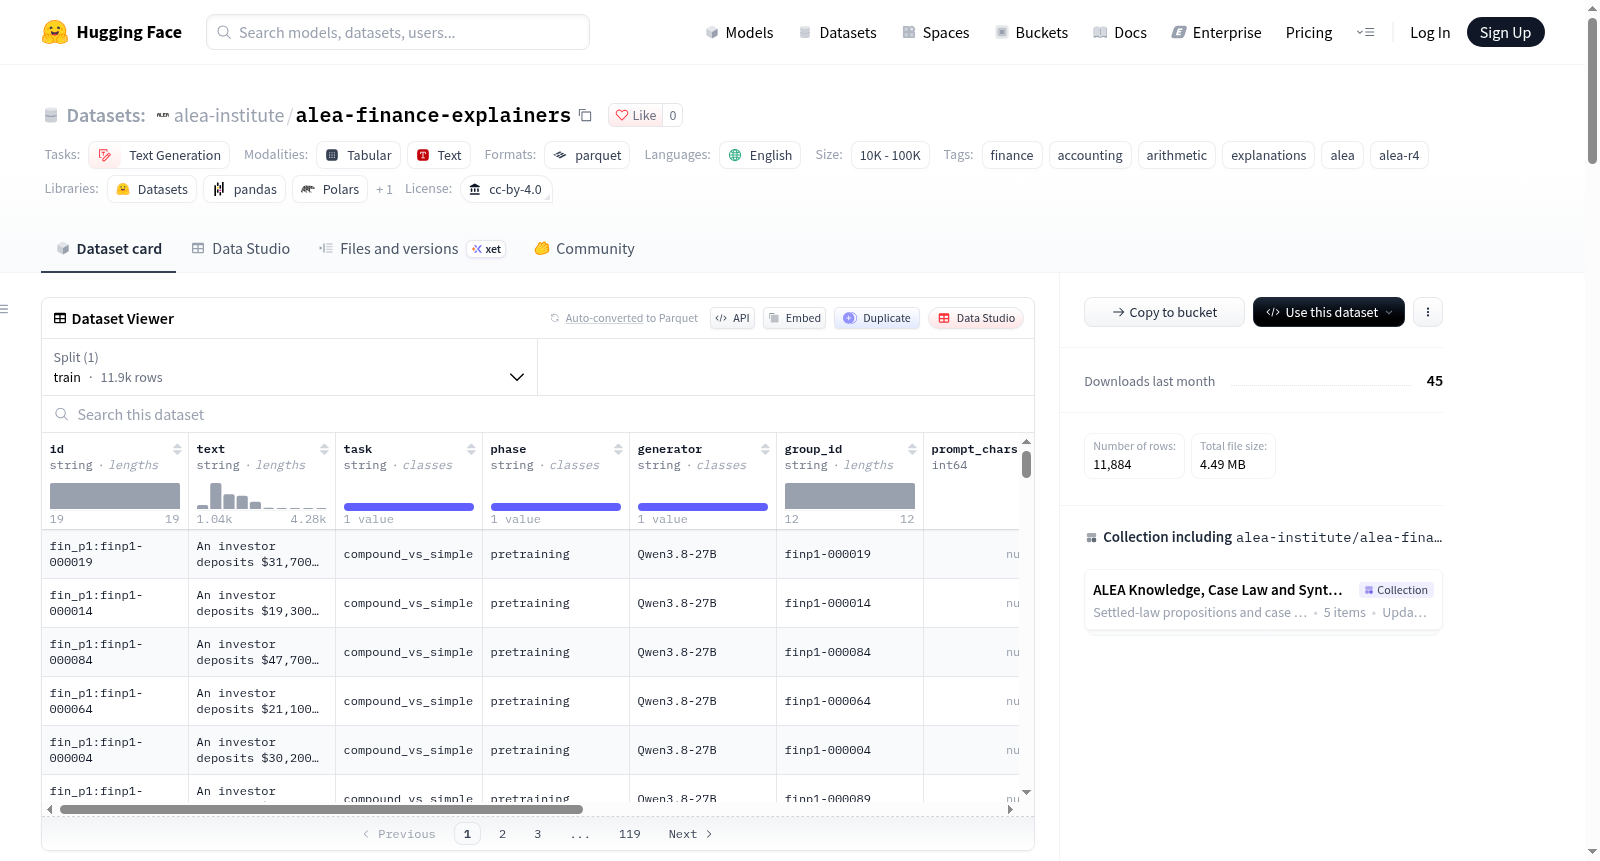
ALEA finance explainers 是由 ALEA Institute 发布的金融与会计概念解释数据集,主要用于文本生成和语言模型训练/预训练。文档为 plain-prose,通过具体数值示例解释金融与会计概念。原始覆盖五类任务:债券价格与市场利率、权责发生制与收付实现制、间接经营现金流、财务比率、复利与单利增长。语言为英语,任务类别为 text-generation,规模类别为 10K<n<100K,标签包括 finance、accounting、arithmetic、explanations、alea、alea-r4,许可证为 CC-BY-4.0,默认配置为 default,训练文件路径为 data/train-*.parquet。当前版本经过两次 2026-10-31 修订。第一次修订将文档从 59,841 条、25,320,824 tokens 减少到 23,450 条、9,460,417 tokens,删除包含 65 个 filler surnames 或 1,575 个组织名(以及姓氏 Olander)作为完整词出现的行;原因是这些名称来自小型固定池并在数据中重复,其中虚构公司组织名约每个名称对应 3,000 篇文档,剩余文档仍使用有限地名词汇。第二次修订进一步将文档从 23,450 条、9,460,417 tokens 减少到 11,884 条、4,422,367 tokens,删除包含生成器名称池中姓氏、组织名和虚构地名的行;原因是池中名称在数百到数千篇文档中复现,模型会学习名称而非任务。两次删除均为 detect-only 整行删除,未编辑文本,剩余行与最初发布的行逐字节一致,且剩余行不含这些池名。早期版本仍可在数据集历史中获取。经第二次修订后,按 task 统计仅 compound_vs_simple 保留 11,884 条文档、4,422,367 tokens,accrual_vs_cash、bond_price_vs_rate、indirect_cfo 和 ratios 均为 0;README 中较早的完整组成表描述的是原始发布或早期版本。原始完整组成包括:accrual_vs_cash 12,196 篇/5,338,246 tokens,indirect_cfo 12,166 篇/5,067,971 tokens,compound_vs_simple 11,884 篇/4,422,367 tokens,bond_price_vs_rate 11,857 篇/4,927,872 tokens,ratios 11,738 篇/5,564,368 tokens。该数据集包含 ALEA R4 模型在稳定预训练混合(第二阶段,每篇一遍)中训练过的该 family 文档;每行与训练文本逐字节一致,text_sha256 是 text 的 SHA-256。由同一代码生成的 held-out evaluation 项目不在本发布中。数据来源标注为 invented problems;制作时所有数字都在代码中从虚构输入计算,Qwen3.8-27B(开放权重,本地部署)根据计算步骤和结果撰写解释,并被要求不得更改或添加数字。数据验证要求包括:文本中的每个数字必须是输入、计算值或其声明的舍入值、年份或小计数;最终答案必须出现;方向词必须与计算出的方向一致;不得使用 markdown;需满足长度边界。去污染方面,与 held-out evaluation item(本 family 或兄弟 family)共享 word 13-gram 的训练行被移除,与 ALEA 评估集重叠的行按 ALEA 去污染政策移除或记录。抽样记录由独立审阅者盲审,其重新计算或重新推导答案;审阅中发现的缺陷在最终构建前通过修复生成器或删除受影响行处理。数据结构为表格,字段包括:id(生成器行 id,不总是唯一;少数 family 在变体间复用 id,少量完全重复文档被训练两次并出现两次)、text(与训练时完全一致的文档;聊天文档使用 ALEA chat template,控制 token 以文本形式出现:<|start|>、<|system|>、<|user|>、<|assistant|>、<|eot|>、<|end|>)、task(任务类型)、phase(生成器放置标签:plain documents 为 pretraining,instruction-framed tasks 为 midtraining;此处每行都在 R4 稳定预训练混合中训练)、generator(撰写该行的对象,deterministic 表示仅代码)、group_id(来源段落/记录组,同一组的所有变体共享)、prompt_chars(text 中请求部分的字符长度;plain documents 为 0,未记录处为 null)、n_tokens(在 alea-v2b-sw32k 下的 token 数,包括文档起止 token)、text_sha256(text 的 SHA-256)、meta(JSON,包含生成器结构化字段:source、presentation、answer form、gold values、checks)。已知局限是文档为生成文本,比自然文本更重复。许可证方面,本编译和生成文本采用 CC-BY-4.0;公共领域和公共记录来源文本保持其状态;Wikidata 为 CC0;OpenGloss 和 SHELF 为 CC-BY-4.0。数据集由 ALEA Institute 发布。
ALEA finance explainers is a finance and accounting concept explanation dataset released by ALEA Institute, mainly used for text generation and language model training/pretraining. Its documents are in plain prose and explain finance and accounting concepts through concrete numerical examples. It originally covered five task categories: bond price vs market rate, accrual vs cash accounting, indirect operating cash flow, financial ratios, and compound vs simple growth. The language is English, the task category is text-generation, the size category is 10K<n<100K, tags include finance, accounting, arithmetic, explanations, alea, and alea-r4, the license is CC-BY-4.0, the default configuration is default, and the training files are data/train-*.parquet. The current version has undergone two revisions dated 2026-10-31. The first revision reduced the dataset from 59,841 documents and 25,320,824 tokens to 23,450 documents and 9,460,417 tokens by removing rows containing 65 filler surnames or 1,575 organization names, as well as the surname Olander, as whole words; these names came from a small fixed pool and repeated in the data, with fictional company or organization names appearing in about 3,000 documents each, and remaining documents still use a limited place-name vocabulary. The second revision further reduced the dataset from 23,450 documents and 9,460,417 tokens to 11,884 documents and 4,422,367 tokens by removing rows containing surnames, organization names, and fictional place names from the generator name pool; these pool names appeared in hundreds to thousands of documents, causing models to learn names rather than tasks. Both removals were detect-only whole-row deletions without editing the text, remaining rows are byte-for-byte identical to the originally released rows, and the remaining rows do not contain these pool names. Earlier versions remain available in dataset history. After the second revision, by task only compound_vs_simple retains 11,884 documents and 4,422,367 tokens, while accrual_vs_cash, bond_price_vs_rate, indirect_cfo, and ratios are all 0; the earlier full composition table in the README describes the original release or an earlier version. The original full composition includes: accrual_vs_cash 12,196 documents / 5,338,246 tokens, indirect_cfo 12,166 documents / 5,067,971 tokens, compound_vs_simple 11,884 documents / 4,422,367 tokens, bond_price_vs_rate 11,857 documents / 4,927,872 tokens, and ratios 11,738 documents / 5,564,368 tokens. The dataset contains this family of documents trained by the ALEA R4 model in a stable pretraining mixture (stage two, one pass per document); each row is byte-for-byte identical to the training text, and text_sha256 is the SHA-256 of text. Held-out evaluation items generated by the same code are not included in this release. The data source is labeled as invented problems; during production all numbers were computed in code from fictional inputs, and Qwen3.8-27B (open weights, locally deployed) wrote explanations based on the calculation steps and results, and was required not to change or add numbers. Data validation requirements include: every number in the text must be an input, a computed value or its declared rounded value, a year, or a small count; the final answer must appear; direction words must match the computed direction; markdown must not be used; and length bounds must be satisfied. For decontamination, training rows sharing word 13-grams with held-out evaluation items (from this family or sibling families) were removed, and rows overlapping the ALEA evaluation set were removed or recorded according to the ALEA decontamination policy. Sampled records were blind-reviewed by independent reviewers, who recomputed or rederived the answers; defects found in review were handled before final construction by fixing the generator or deleting affected rows. The data structure is tabular, with fields: id (generator row id, not always unique; some families reuse ids across variants, and a few exactly duplicated documents were trained twice and appear twice), text (the document exactly as used in training; chat documents use the ALEA chat template, with control tokens appearing as text: <|start|>, <|system|>, <|user|>, <|assistant|>, <|eot|>, <|end|>), task (task type), phase (generator placement label: pretraining for plain documents, midtraining for instruction-framed tasks; here every row was trained in the R4 stable pretraining mixture), generator (the entity that wrote the row, where deterministic means code only), group_id (source paragraph/record group; all variants from the same group share it), prompt_chars (character length of the request portion in text; 0 for plain documents and null where not recorded), n_tokens (token count under alea-v2b-sw32k, including document start and end tokens), text_sha256 (SHA-256 of text), and meta (JSON containing generator structured fields: source, presentation, answer form, gold values, checks). A known limitation is that the documents are generated text and more repetitive than natural text. Regarding licensing, this compilation and generated text use CC-BY-4.0; public domain and public record source texts remain in their status; Wikidata is CC0; OpenGloss and SHELF are CC-BY-4.0. The dataset is released by ALEA Institute.