autophagycode_D_train_Qwen3-8B_lr0.0001_c142_trust_g2
收藏资源简介:
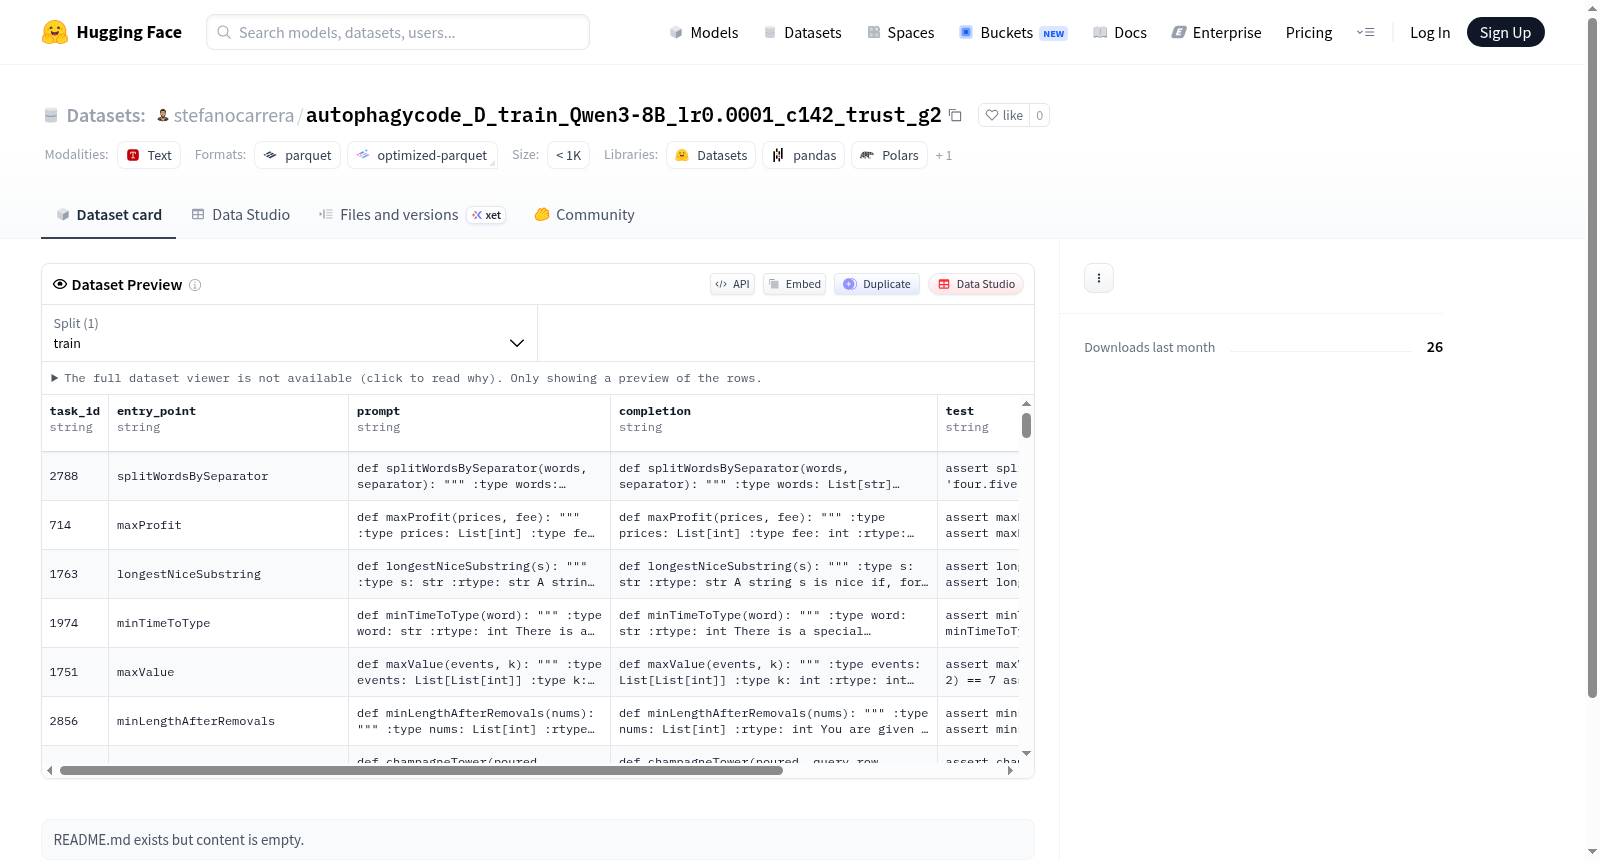
该数据集包含142个训练样本,总大小约284KB。每个样本包含5个结构化字段:task_id(任务标识符,字符串类型)、entry_point(入口点,字符串类型)、prompt(提示文本,字符串类型)、completion(补全内容,字符串类型)和test(测试内容,字符串类型)。数据集仅提供训练集划分,未说明具体应用场景或数据来源,但从字段命名推测可能与代码生成或文本补全任务相关。
This dataset contains 142 training samples with a total size of approximately 284 KB. Each sample includes 5 structured fields: task_id (task identifier, string type), entry_point (entry point, string type), prompt (prompt text, string type), completion (completion content, string type), and test (test content, string type). Only a training set split is provided for this dataset, with no specific application scenario or data source specified. Nonetheless, based on the field naming conventions, it can be inferred that the dataset is related to code generation or text completion tasks.
数据集概述
基本信息
- 数据集名称: autophagycode_D_train_Qwen3-8B_lr0.0001_c142_trust_g2
- 托管平台: Hugging Face Datasets
- 数据集地址: https://huggingface.co/datasets/stefanocarrera/autophagycode_D_train_Qwen3-8B_lr0.0001_c142_trust_g2
数据集结构与内容
数据字段
- task_id: 任务标识符(字符串类型)
- entry_point: 入口点(字符串类型)
- prompt: 提示文本(字符串类型)
- completion: 完成文本(字符串类型)
- test: 测试内容(字符串类型)
数据划分
- 训练集:
- 样本数量: 142
- 数据大小: 271,377 字节
- 下载大小: 127,164 字节
配置信息
- 默认配置名称: default
- 数据文件路径:
data/train-*