M-LongDoc
收藏资源简介:
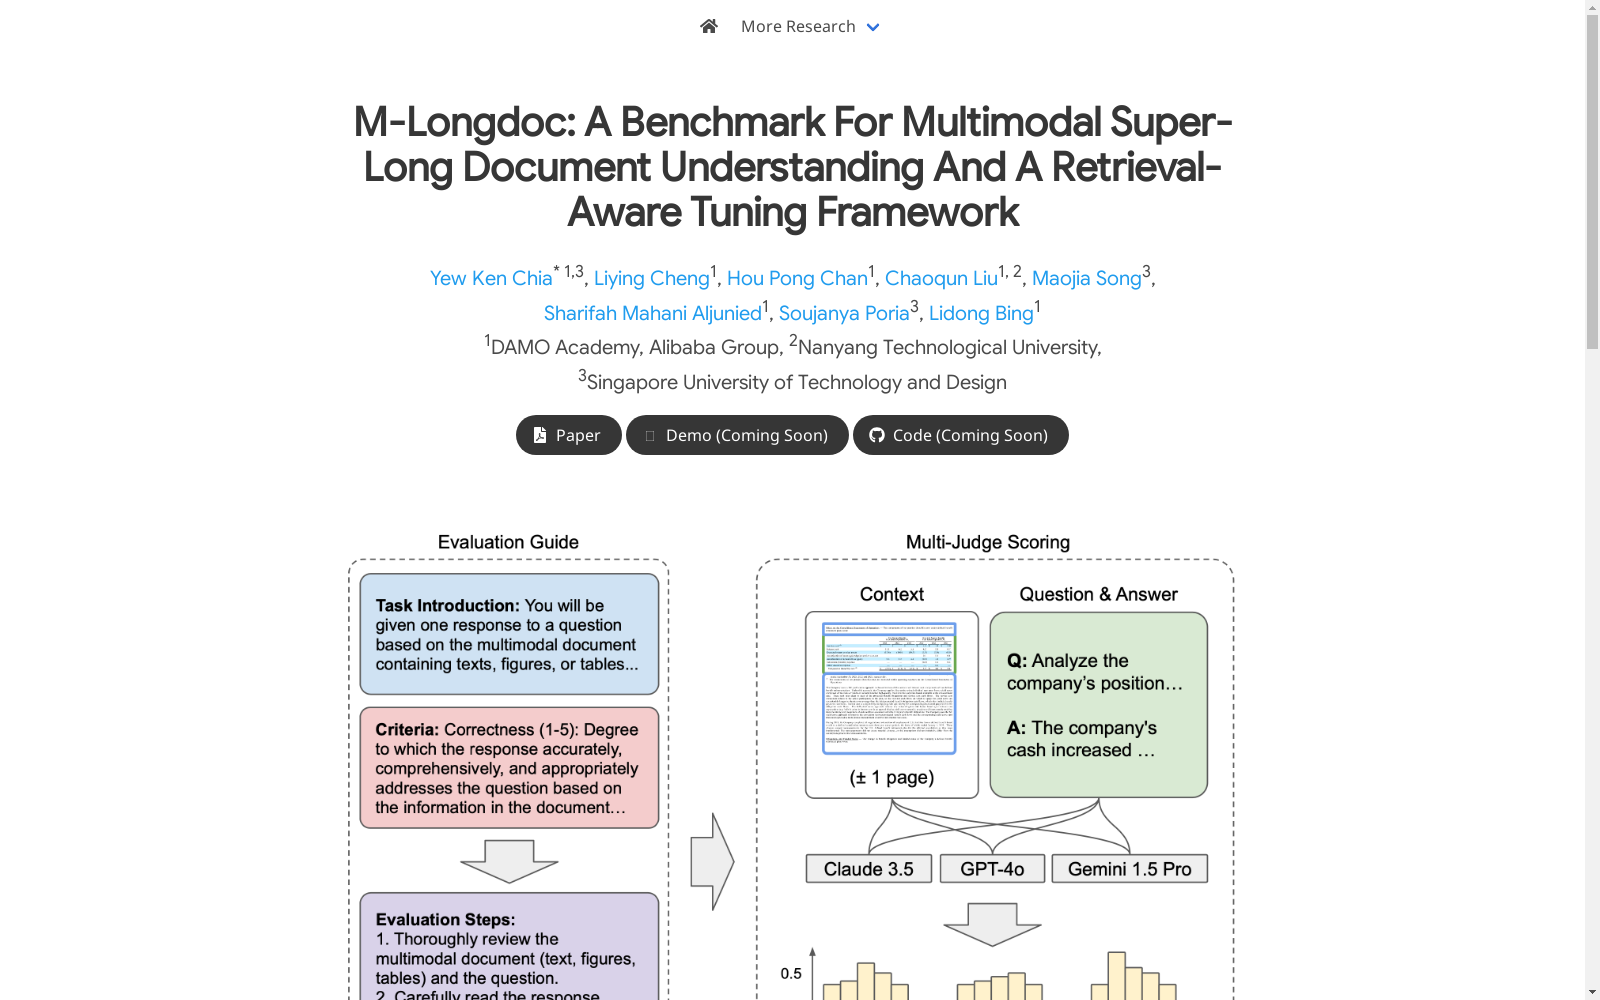
M-LongDoc数据集由新加坡科技设计大学创建,旨在评估大型多模态模型在长文档理解中的表现。该数据集包含851个样本,涵盖了数百页的长文档,内容包括文本、图表和表格,涉及学术、金融和产品领域。数据集的创建过程包括从公开资源中手动收集高质量的多模态文档,并通过半自动化的方式生成多样化和挑战性的开放式问题。M-LongDoc的应用领域广泛,旨在解决多模态长文档理解中的复杂问题,如信息检索和问答系统。
The M-LongDoc dataset was developed by the Singapore University of Technology and Design, with the goal of evaluating the performance of large multimodal models in long document understanding tasks. This dataset comprises 851 samples, covering hundreds of pages of long documents that contain text, charts and tables, spanning academic, financial and product-related domains. The dataset construction process involves manually collecting high-quality multimodal documents from public resources, and generating diverse and challenging open-ended questions through a semi-automated approach. Boasting wide-ranging application prospects, M-LongDoc is designed to tackle complex issues in multimodal long document understanding, such as information retrieval and question answering systems.