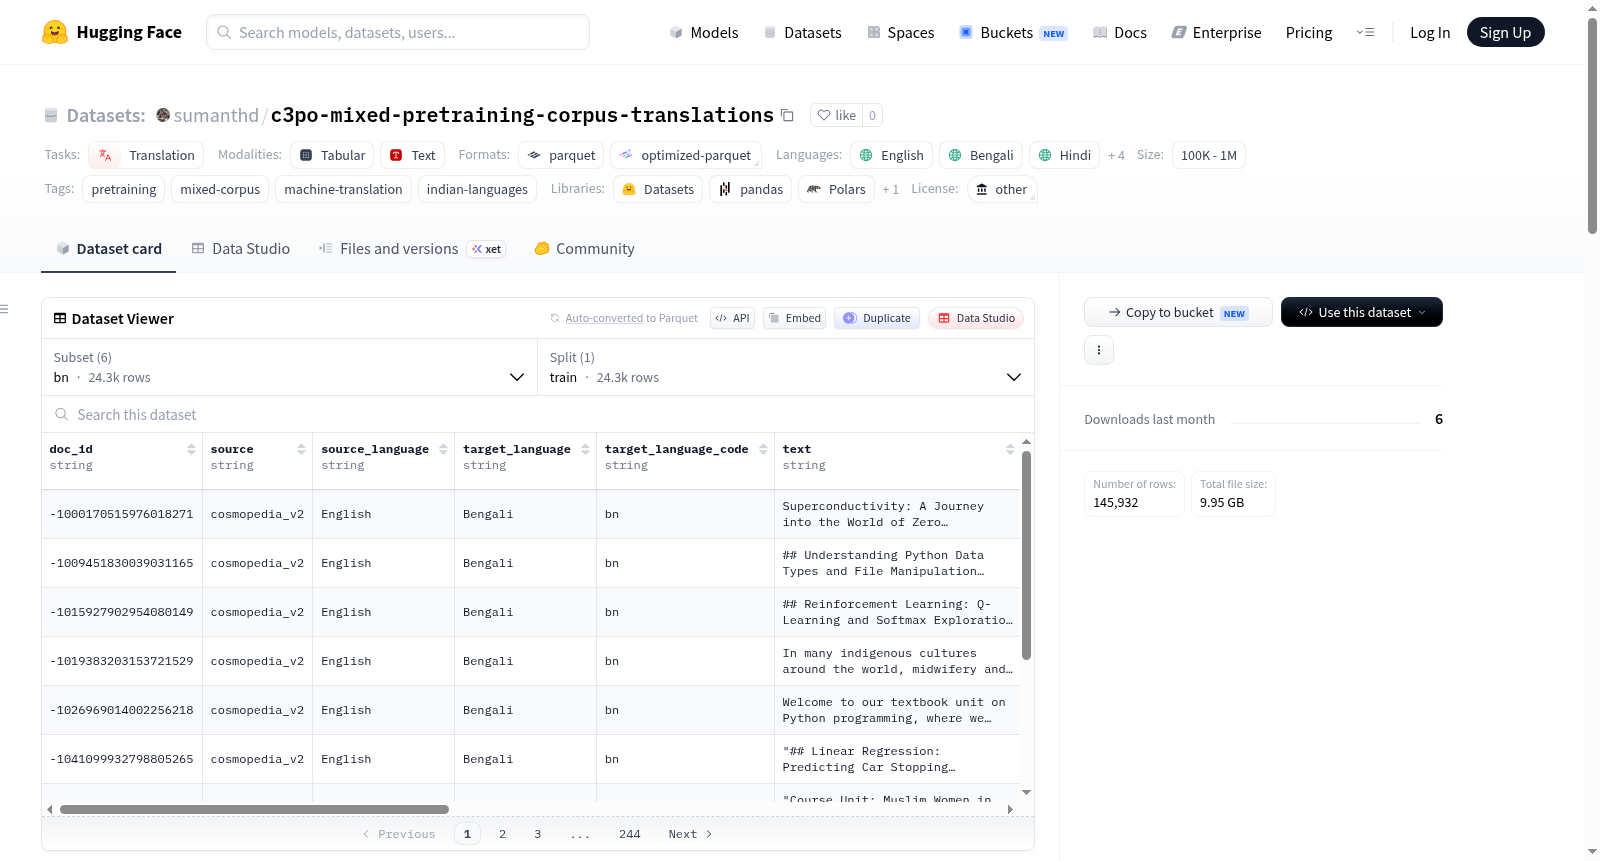
c3po-mixed-pretraining-corpus-translations
收藏资源简介:
C3PO混合预训练语料库翻译数据集是一个机器翻译数据集,旨在将英语文档翻译成多种印度语言。该数据集基于源语料库sumanthd/c3po-mixed-pretraining-corpus构建,使用Gemma 4 31B模型通过vLLM进行翻译。翻译过程将文档在段落/句子边界处分割成约4k令牌的块,翻译后再拼接成完整文档,并保留了每个翻译块的元数据。数据集总规模为72,966行,目前包含三个独立的语言配置(子集):印地语(hi)、泰卢固语(te)和孟加拉语(bn),每个配置包含24,322个文档。每个数据样本包含丰富的字段信息,如文档ID、源标识、源语言(始终为英语)、目标语言及其ISO代码、原始英语文本、完整的翻译文本、以JSON格式存储的分块翻译元数据、源特定元数据、令牌计数、分块数量、使用的翻译模型标识、vLLM服务器信息以及创建和最终完成的时间戳。该数据集适用于机器翻译模型训练、多语言预训练以及印度语言的自然语言处理研究。
The C3PO Mixed Pretraining Corpus Translation Dataset is a machine translation dataset designed to translate English documents into multiple Indian languages. Built upon the source corpus `sumanthd/c3po-mixed-pretraining-corpus`, this dataset is translated using the Gemma 4 31B model via vLLM. During the translation process, documents are split into chunks of approximately 4k tokens at paragraph or sentence boundaries, then concatenated back into complete documents after translation, with metadata retained for each translated chunk. The dataset has a total of 72,966 rows, and currently includes three independent language subsets: Hindi (hi), Telugu (te), and Bengali (bn), with each subset containing 24,322 documents. Each data sample contains comprehensive fields including document ID, source identifier, source language (always English), target language and its ISO code, original English text, full translated text, chunked translation metadata stored in JSON format, source-specific metadata, token count, number of chunks, identifier of the used translation model, vLLM server information, and timestamps for creation and final completion. This dataset is suitable for machine translation model training, multilingual pre-training, and natural language processing research on Indian languages.
数据集概述
数据集名称: C3PO Mixed Pretraining Corpus Translations
许可证: 其他(other)
任务类别: 翻译(translation)
语言: 英语翻译至6种印度语言(孟加拉语、印地语、卡纳达语、马拉雅拉姆语、泰米尔语、泰卢固语)
标签: 预训练、混合语料、机器翻译、印度语言
数据规模: 10K < n < 100K
发布者: sumanthd
描述
该数据集是 sumanthd/c3po-mixed-pretraining-corpus 的英语到印度语言的翻译版本。每个语言在 Hub 上作为一个独立的 dataset config(子集),便于浏览。
文档通过 Gemma 4 31B 模型(使用 vLLM)以约 4k token 的块进行翻译,分段边界在段落/句子边界,然后拼接为完整文档。单个块翻译结果保留在 chunks_json 字段中。
统计信息
| 项目 | 数值 |
|---|---|
| 总行数 | 145,932 |
| 源语料 | sumanthd/c3po-mixed-pretraining-corpus |
| 翻译模型 | /scratch/shared/oss-models/gemma-4-31B-it |
| 发布日期 | 2026-06-08T16:27:56+00:00 |
配置(各语言子集)
| 配置名 | 语言 | 文档数 |
|---|---|---|
bn |
孟加拉语 | 24,322 |
hi |
印地语 | 24,322 |
kn |
卡纳达语 | 24,322 |
ml |
马拉雅拉姆语 | 24,322 |
ta |
泰米尔语 | 24,322 |
te |
泰卢固语 | 24,322 |
注意:部分语言在翻译完成后将作为新的配置添加。
数据模式
| 字段名 | 类型 | 描述 |
|---|---|---|
doc_id |
string | 源文档 ID |
source |
string | 源类别(如 wikipedia、proof_pile 等) |
source_language |
string | 始终为 English |
target_language |
string | 目标语言名称 |
target_language_code |
string | ISO 639-1 语言代码 |
text |
string | 英语源文档 |
translated_text |
string | 拼接后的完整翻译 |
chunks_json |
string | 块元数据的 JSON 数组(源文本和翻译文本、字符跨度) |
metadata_json |
string | 源特定元数据的 JSON 对象 |
token_count |
int | 源 token 数(使用 Gemma tokenizer) |
chunk_count |
int | 翻译块数量 |
model |
string | 翻译模型 ID |
vllm_server |
string | 使用的 vLLM 路由器 |
created_at |
string | 翻译时间戳(UTC) |
finalized_at |
string | 最终拼接时间戳(UTC) |
加载方式(示例)
python from datasets import load_dataset import json
选择一个语言配置
bn = load_dataset("sumanthd/c3po-mixed-pretraining-corpus-translations", "bn", split="train") hi = load_dataset("sumanthd/c3po-mixed-pretraining-corpus-translations", "hi", split="train") kn = load_dataset("sumanthd/c3po-mixed-pretraining-corpus-translations", "kn", split="train") ml = load_dataset("sumanthd/c3po-mixed-pretraining-corpus-translations", "ml", split="train") ta = load_dataset("sumanthd/c3po-mixed-pretraining-corpus-translations", "ta", split="train") te = load_dataset("sumanthd/c3po-mixed-pretraining-corpus-translations", "te", split="train")
print(hi[0]["translated_text"][:200]) chunks = json.loads(hi[0]["chunks_json"]) print(chunks[0].keys())