SPADE-customer-service-dialogue
收藏资源简介:
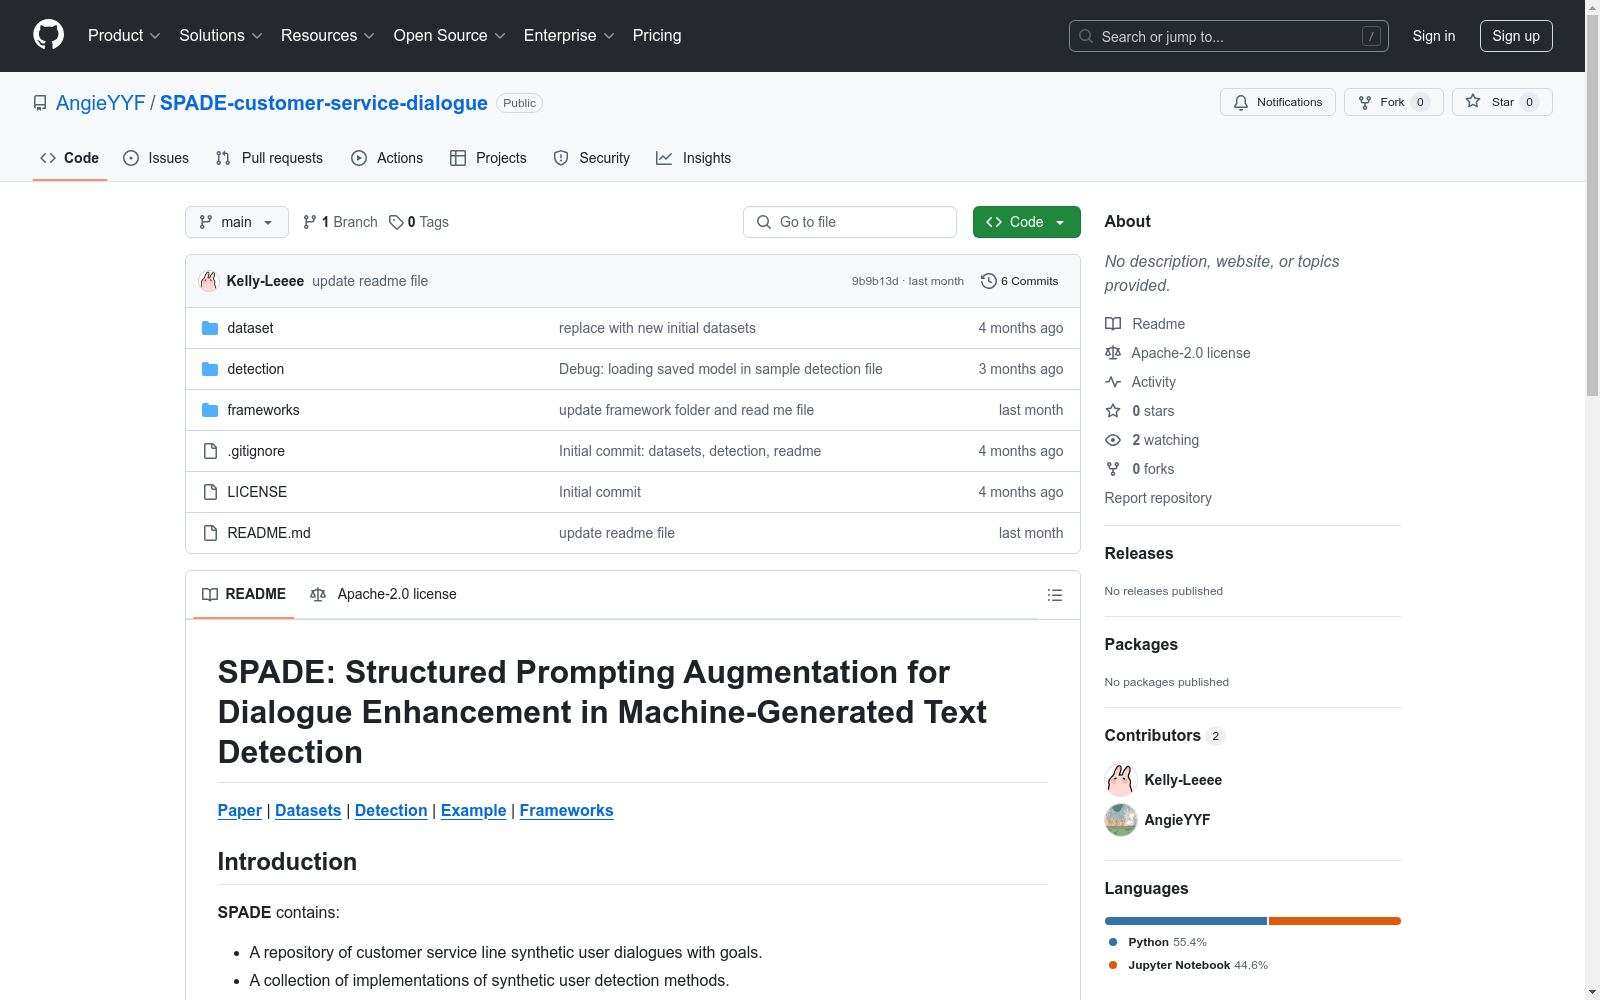
SPADE-customer-service-dialogue数据集是由The University of Melbourne的研究团队开发,旨在解决机器生成文本检测问题。该数据集包含14个通过结构化提示方法生成的对话数据集,采用多种数据增强框架,以降低传统数据收集方法的成本。数据集适用于多个领域,对话内容流畅、符合用户目标,并通过自动化和手动质量保证确保质量。该数据集可应用于机器生成文本检测的对话场景,特别是在线对话检测。
The SPADE-customer-service-dialogue dataset was developed by a research team from The University of Melbourne to address the task of machine-generated text detection. It consists of 14 dialogue datasets generated using structured prompting methodologies, and integrates multiple data augmentation frameworks to lower the costs associated with traditional data collection practices. The dataset is applicable across diverse domains, with fluent, user-goal-aligned dialogue content, and its quality is verified through both automated and manual quality assurance procedures. It can be utilized for machine-generated text detection in dialogue scenarios, particularly for online conversation detection.