tsw0411/real_dia_dataset
收藏资源简介:
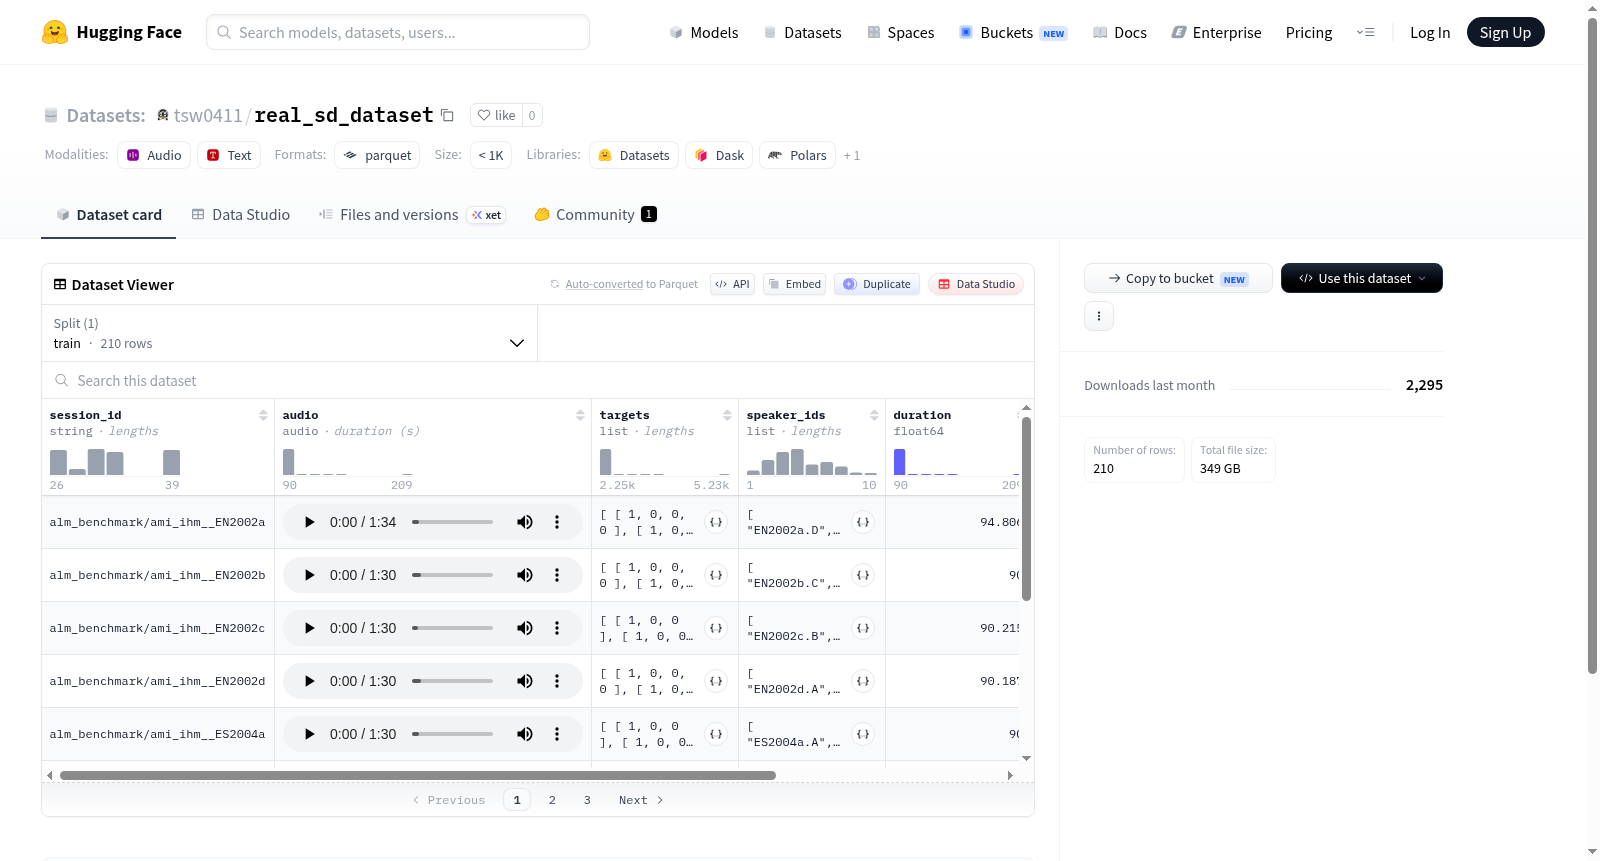
该数据集是一个音频处理数据集,包含210个训练样本,每个样本具有会话ID、音频数据、目标序列、说话者ID序列、持续时间、说话者数量和有效偏移序列等特征。音频数据以音频格式存储,目标序列为整数序列的序列,说话者ID序列为字符串序列。数据集总大小约为651.5MB,下载大小约为613.9MB,适用于多说话者音频分析或语音处理任务,如说话人识别或音频分割。
This dataset is an audio processing dataset comprising 210 training samples. Each sample contains features including session ID, audio data, target sequence, speaker ID sequence, duration, number of speakers, and valid offset sequence. The audio data is stored in audio formats, where the target sequence is a sequence of integer sequences, and the speaker ID sequence for each sample is a sequence of strings. The total size of the dataset is approximately 651.5 MB, with a download size of around 613.9 MB. This dataset is applicable to multi-speaker audio analysis or speech processing tasks such as speaker recognition or audio segmentation.