Legal-QE
收藏资源简介:
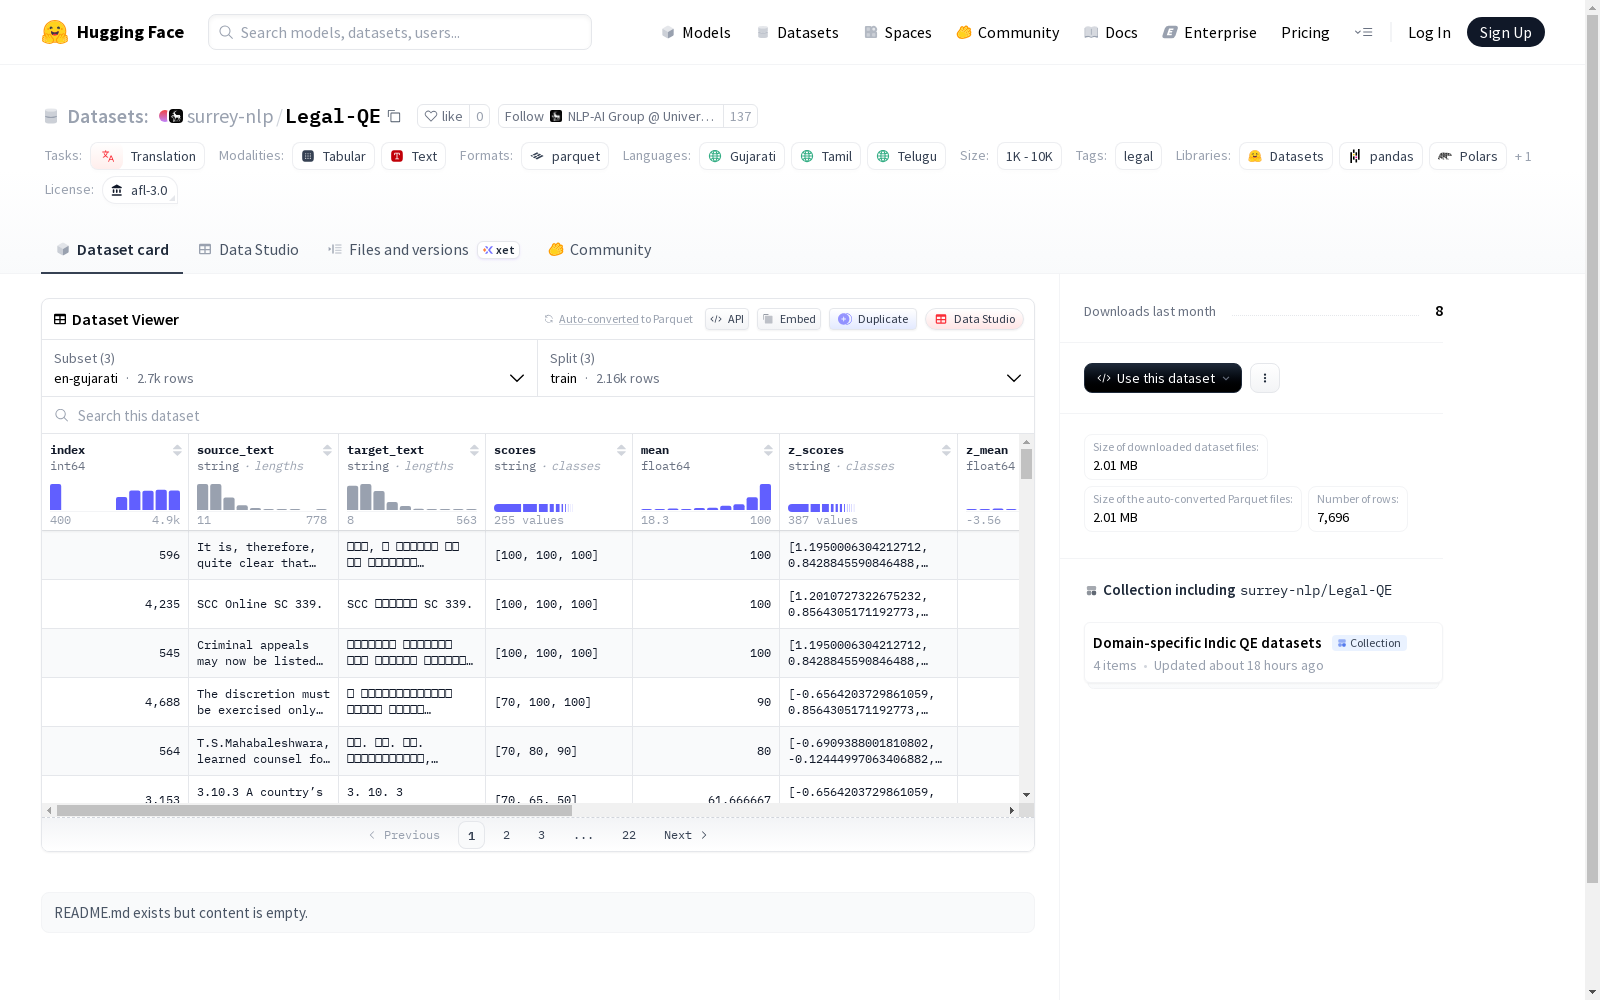
该数据集是一个多语言法律领域平行语料库,包含英语与三种印度语言(古吉拉特语、泰米尔语、泰卢固语)之间的双向翻译数据。数据集规模介于1万至10万条之间,采用AFL-3.0许可证发布。每个语言对(en-gu/en-ta/en-te)配置包含完全相同的字段结构:索引编号、源文本、目标文本、质量评分(含原始分与标准化分数)、文本领域标签、唯一标识符以及语言对元数据。数据已划分为训练集(2160/1836/2160条)、验证集(270/230/270条)和测试集(270/230/270条),主要适用于机器翻译模型训练与评估任务,特别针对法律文本的专业翻译场景。
This dataset is a multilingual parallel corpus for the legal domain, containing bidirectional translation data between English and three Indian languages (Gujarati, Tamil, Telugu). The dataset has a scale ranging from 10,000 to 100,000 entries and is released under the AFL-3.0 license. Each language pair (en-gu/en-ta/en-te) configuration features an identical field structure: index number, source text, target text, quality score (including raw score and normalized score), text domain label, unique identifier, and language pair metadata. The data has been split into training set (2160/1836/2160 entries), validation set (270/230/270 entries), and test set (270/230/270 entries). It is primarily intended for machine translation model training and evaluation tasks, specifically targeting professional translation scenarios for legal texts.