FineMed
收藏资源简介:
FineMed是由复旦大学计算机科学学院开发的高质量医学对话数据集,旨在提升大型语言模型在医学领域的推理能力。该数据集包含约300,000条样本,涵盖复杂的医学指令和长形式推理数据。数据来源包括互联网语料库(如Common Crawl)和医学知识文本,通过指令生成、评分、过滤和响应生成四个步骤合成。FineMed数据集的应用领域主要集中在医学对话理解和复杂医学任务推理,旨在解决现有医学语言模型在深度推理能力上的不足,提升模型在疾病诊断和治疗规划等任务中的表现。
FineMed is a high-quality medical dialogue dataset developed by the School of Computer Science, Fudan University, aimed at enhancing the reasoning capabilities of large language models (LLMs) in the medical field. This dataset contains approximately 300,000 samples, covering complex medical instructions and long-form reasoning data. Its data sources include internet corpora (such as Common Crawl) and medical knowledge texts, and it is synthesized via four sequential steps: instruction generation, scoring, filtering, and response generation. The primary application domains of the FineMed dataset focus on medical dialogue understanding and complex medical task reasoning, aiming to address the limitations of existing medical language models in terms of deep reasoning capabilities and improve the performance of models in tasks such as disease diagnosis and treatment planning.
FineMed 数据集概述
数据集来源
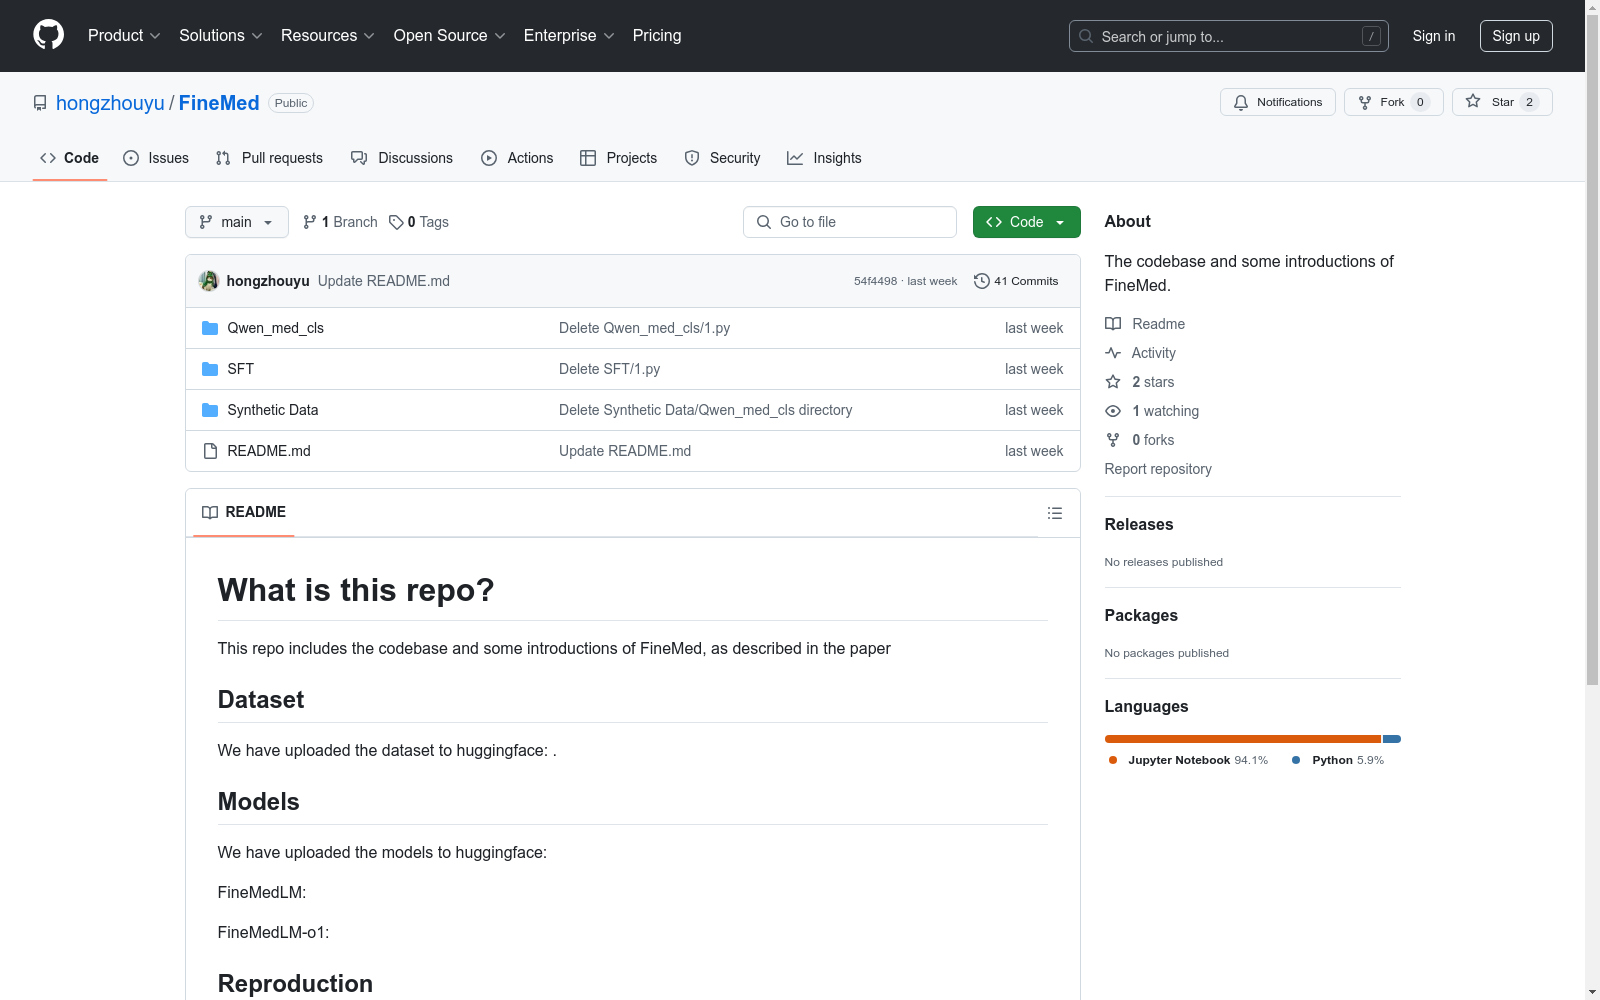
- 数据集由 FineMed 项目提供,相关代码和介绍可在 GitHub 仓库中找到。
数据集存储位置
- 数据集已上传至 Hugging Face 平台。
模型存储位置
- FineMedLM 和 FineMedLM-o1 模型已上传至 Hugging Face 平台。
研究复现步骤
- 生成合成数据(Synthetic Data)。
- 运行 Qwen_med_cls。
- 进行监督微调(SFT)。
引用信息
- 如果 FineMed 或该仓库对您的研究有帮助,请使用提供的 BibTeX 条目进行引用。