MedSynVQA-5K-qwen-glm
收藏资源简介:
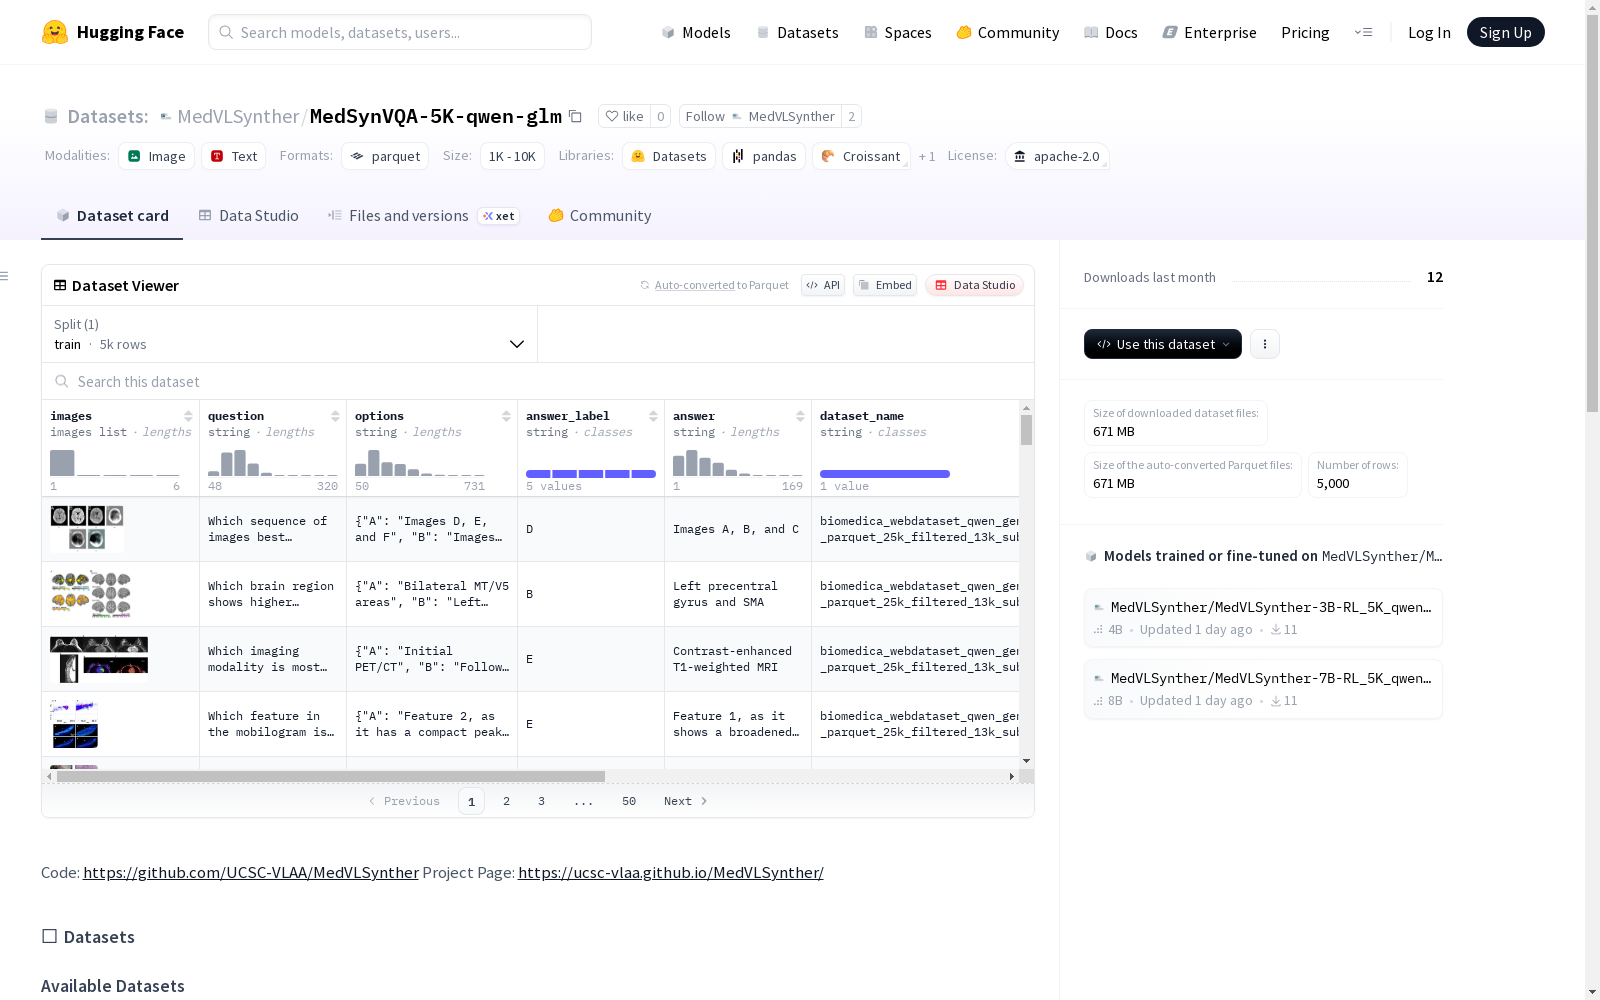
MedSynVQA数据集是一个用于医学视觉问答的任务的数据集,它包含完整的训练集和多个子集,用于RLVR和SFT训练。数据集中的图像和文本模态结合,提供了问题、选项、正确答案和推理过程等信息。
The MedSynVQA dataset is a specialized dataset for medical visual question answering (VQA) tasks. It includes a complete training set and multiple subsets, which are intended for RLVR and SFT training. The dataset combines image and text modalities, providing information such as questions, options, correct answers, and reasoning processes.
MedSynVQA-5K-qwen-glm 数据集概述
基本信息
- 许可证: Apache-2.0
- 模态: 图像-文本
- 样本数量: 5K
数据集用途
- 主要用途: 生成器和验证器选择消融实验
- 训练类型: 支持RLVR训练
生成与验证配置
- 生成器: Qwen2.5-VL 72B
- 验证器: GLM-4.5V 108B
数据格式
python { "images": [PIL.Image], # 图像列表 "question": str, # 问题文本 "options": Dict[str, str], # 多项选择选项 "answer_label": str, # 正确答案标签(A、B、C、D、E) "answer": str, # 完整答案文本 "reasoning": str, # 思维链推理(可选) "dataset_name": str, # 源数据集名称 "dataset_index": int # 唯一样本标识符 }
相关资源
- 代码仓库: https://github.com/UCSC-VLAA/MedVLSynther
- 项目页面: https://ucsc-vlaa.github.io/MedVLSynther/