synthetic-retrieval
收藏资源简介:
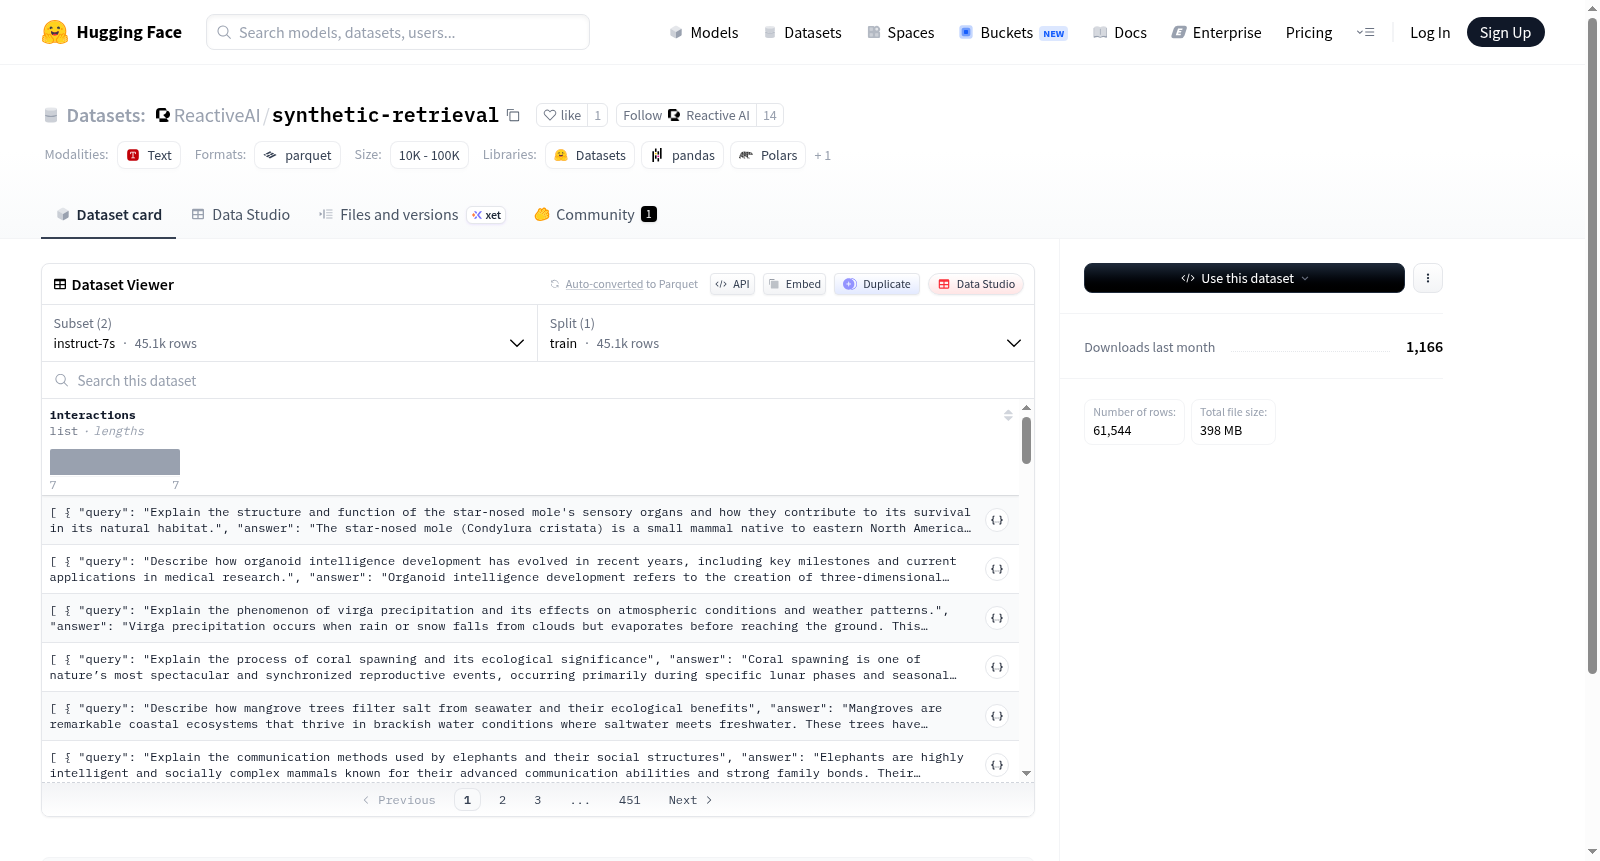
该数据集包含两个独立配置,分别针对不同的自然语言处理任务。第一个配置为“instruct-7s”,包含45,094个训练样本,数据格式为对话交互形式,每个样本包含“query”(查询/指令)和“answer”(回答)两个文本字段,适用于指令遵循、对话生成或问答任务。第二个配置为“reasoning-7s”,包含15,950个训练样本,其结构在查询和回答的基础上增加了“think”(思考/推理过程)字段,形成了“query-think-answer”的三段式结构,适用于需要展示推理链的复杂推理、问题求解或思维链提示任务。两个配置的数据均以纯文本字符串形式存储,仅提供训练分割。
This dataset includes two independent configurations designed for distinct natural language processing (NLP) tasks. The first configuration, labeled "instruct-7s", comprises 45,094 training samples in conversational interaction format. Each sample contains two text fields: "query" (query/instruction) and "answer" (response), and is suitable for instruction following, dialogue generation, or question answering tasks. The second configuration, labeled "reasoning-7s", contains 15,950 training samples. Based on the query and answer fields, it adds a "think" (thinking/reasoning process) field to form a three-part "query-think-answer" structure, which is applicable to complex reasoning, problem-solving, or Chain-of-Thought (CoT) prompting tasks that require presenting reasoning chains. Data for both configurations is stored as plain text strings, and only the training split is provided.