OCR-Data
收藏资源简介:
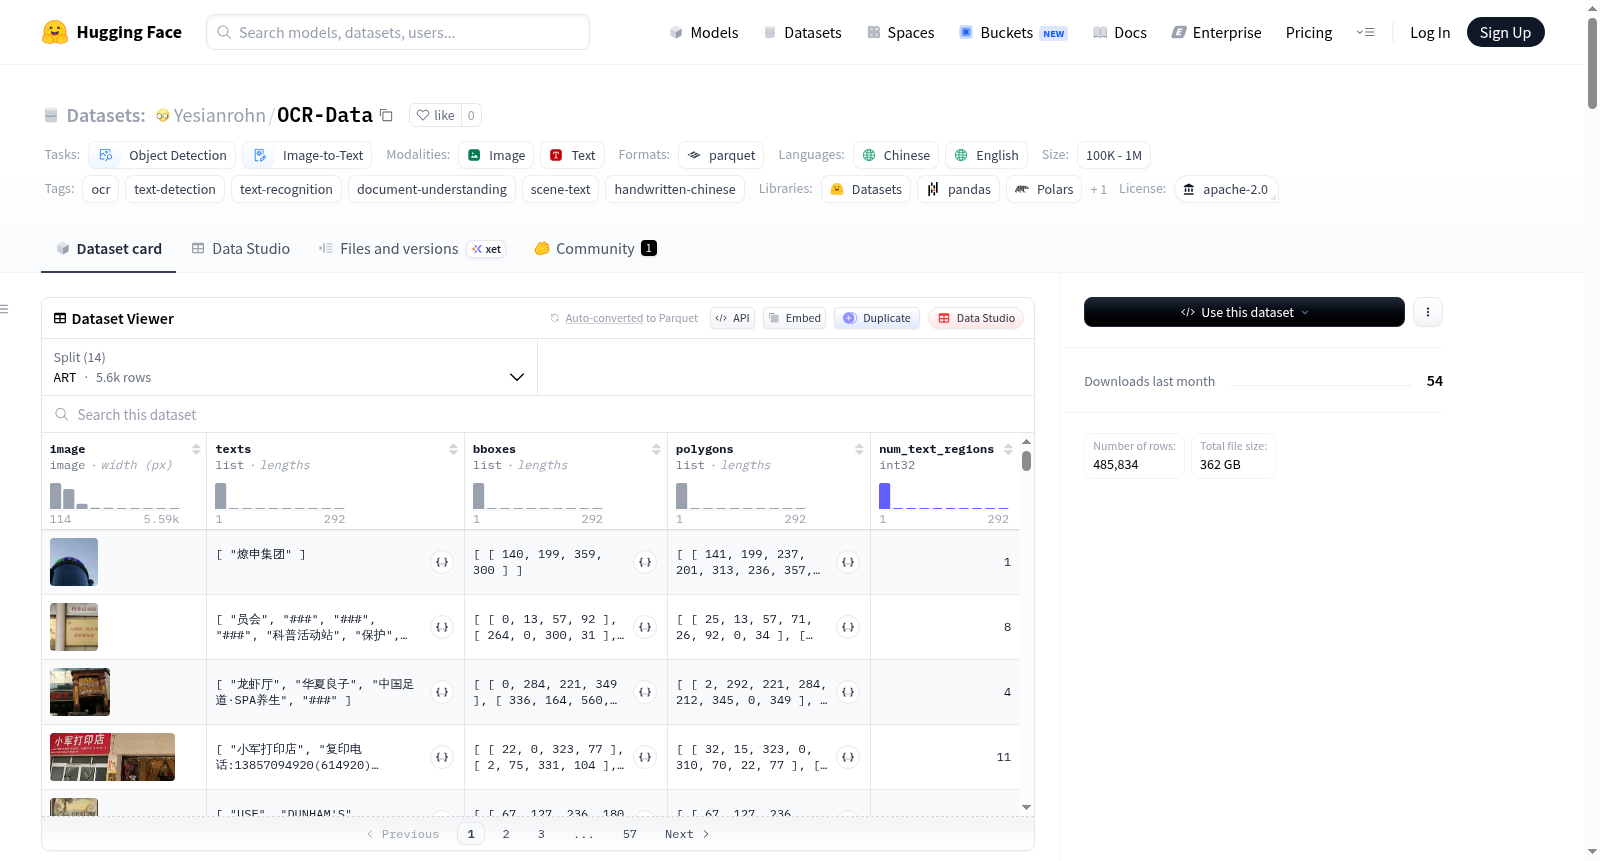
OCR文本检测与识别数据集是一个大规模、多来源的OCR数据集,集成了14个公开基准数据集,用于场景图像和手写文档中的文本检测与识别。每张图像均包含以下标注信息:每个文本区域的转录文本、轴对齐矩形边界框(bounding boxes)以及精确的多边形坐标边界点。数据集以HuggingFace Parquet格式存储,图像以原始字节形式嵌入,支持高效流式加载和零配置使用。每个源基准数据集作为独立的分割存储,用户可以自由加载单个子集或组合多个子集。 数据集包含以下主要特征: - `image`:文档/场景图像(以原始字节形式嵌入) - `texts`:每个文本区域的转录文本字符串列表 - `bboxes`:每个文本区域的轴对齐边界框坐标 `[x_min, y_min, x_max, y_max]` - `polygons`:每个文本区域的多边形坐标平面数组 `[x1, y1, x2, y2, ...]` - `num_text_regions`:图像中的文本区域总数 该数据集适用于多种OCR相关任务,包括但不限于:场景文本检测与识别、手写中文识别、文档理解等。数据集支持多种使用方式,包括全量加载、按分割加载、流式处理以及多分割组合等。
The OCR Text Detection and Recognition Dataset is a large-scale, multi-source OCR dataset that incorporates 14 publicly available benchmark datasets, tailored for text detection and recognition tasks in both scene images and handwritten documents. Each image includes the following annotation information: the transcribed text of each text region, axis-aligned rectangular bounding boxes, and precise polygonal boundary coordinate points. The dataset is stored in the HuggingFace Parquet format, with images embedded in their original byte form, supporting efficient streaming loading and zero-configuration usage. Each source benchmark dataset is stored as an independent data split, allowing users to freely load a single subset or combine multiple subsets. The dataset includes the following core features: - `image`: Document or scene images embedded in their original byte format - `texts`: A list of transcribed text strings corresponding to each text region - `bboxes`: Axis-aligned bounding box coordinates for each text region, formatted as `[x_min, y_min, x_max, y_max]` - `polygons`: 2D arrays of polygonal coordinates for each text region, formatted as `[x1, y1, x2, y2, ...]` - `num_text_regions`: The total number of text regions in the image This dataset is applicable to a wide range of OCR-related tasks, including but not limited to scene text detection and recognition, handwritten Chinese text recognition, document understanding, and more. The dataset supports multiple usage modes, including full dataset loading, split-based loading, streaming processing, and multi-split combination, among others.