earth-love-united-climate-knowledge
收藏资源简介:
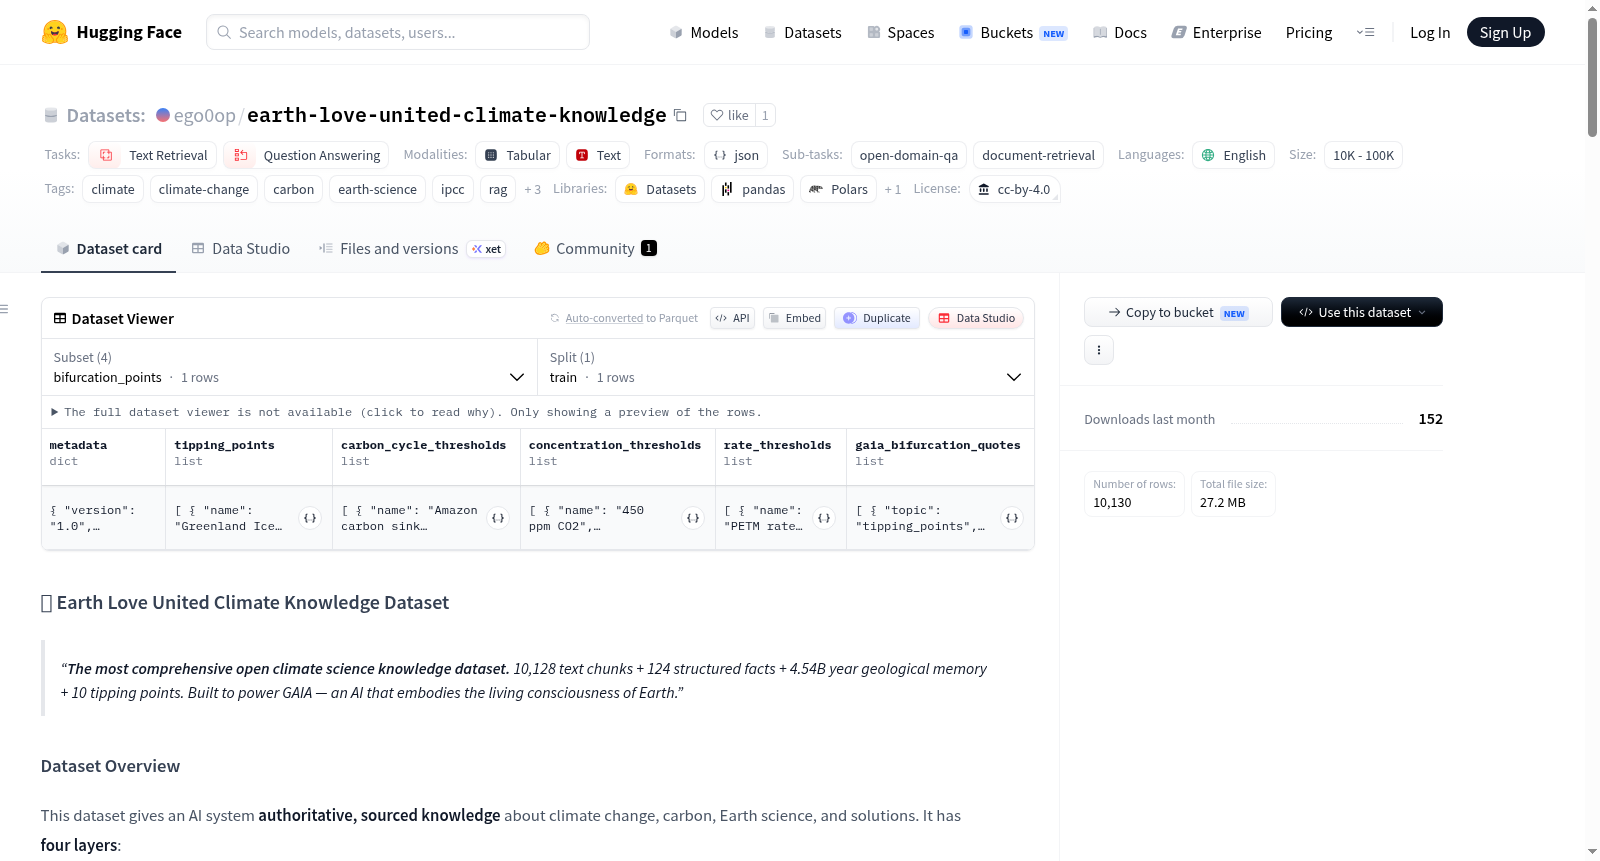
Earth Love United Climate Knowledge数据集是一个全面、权威的气候科学知识数据集,专为支持气候AI系统(如GAIA)而设计。数据集包含三个层次:文本知识层(10,128个清理和分块的文本片段,来源包括Wikipedia、arXiv、IPCC AR6、Project Drawdown、US EPA、Earth Love United原创研究和气候经济学,涵盖气候科学、影响、解决方案、政策、正义、生物多样性和区域研究)、气候事实层(124个结构化数据点,每个包含数值、单位、来源、年份和置信度,覆盖大气浓度、全球温度、碳预算、海平面、碳库、生态系统碳数据、解决方案指标、排放部门、气候敏感性和海洋酸化)和地质记忆层(涵盖地球45.4亿年历史,包括4个时代、44个主要事件、比较数据和GAIA语音引用)。文件格式包括JSONL格式文本块、JSON格式结构化事实和地质记忆,以及压缩倒排索引文件,字段含id、来源、标题、文本、日期、主题和置信度(置信度分为非常高、高和中等)。适用于RAG(检索增强生成)、问答系统、气候教育、事实核查和研究等任务,旨在为气候AI聊天机器人、交互式学习体验和气候传播研究提供权威知识支持。数据集采用多种许可证(如CC-BY-4.0、CC-BY-SA 3.0和公共领域),确保商业可行性。
The Earth Love United Climate Knowledge Dataset is a comprehensive and authoritative climate science knowledge dataset specifically designed to support climate AI systems such as GAIA. The dataset comprises three core tiers: the Text Knowledge Tier, which holds 10,128 cleaned and chunked text fragments sourced from Wikipedia, arXiv, IPCC AR6, Project Drawdown, US EPA, Earth Love United's original research, and climate economics literature, covering topics including climate science, climate impacts, mitigation solutions, policies, climate justice, biodiversity, and regional climate studies; the Climate Fact Tier, which features 124 structured data points each with values, units, source citations, years, and confidence ratings, covering atmospheric greenhouse gas concentrations, global temperature trends, carbon budgets, sea level rise, carbon pools, ecosystem carbon data, solution metrics, emission sectors, climate sensitivity, and ocean acidification; and the Geological Memory Tier, which encompasses Earth's 4.54-billion-year history, including 4 major geological eras, 44 key events, comparative datasets, and GAIA voice citations. Its supported file formats include JSONL-formatted text chunks, JSON-formatted structured facts and geological memory datasets, as well as compressed inverted index files, with standard fields including id, source, title, text, date, topic, and confidence level (confidence levels are classified into three tiers: "Very High", "High", and "Medium"). This dataset is applicable to tasks such as retrieval-augmented generation (RAG), question answering systems, climate education, fact-checking, and academic research, aiming to provide authoritative knowledge support for climate AI chatbots, interactive learning experiences, and climate communication research. It adopts multiple licenses including CC-BY-4.0, CC-BY-SA 3.0, and Public Domain to ensure commercial viability.