
LLM Detection Benchmark Dataset
收藏资源简介:
LLM Detection Benchmark Dataset 是由阿姆里塔·维什瓦·维迪亚佩德姆网络安全系统与网络中心创建的开放源代码数据集,旨在通过文本提示挑战来实时检测LLM是否在对话中伪装成人类。数据集包含两种类型的挑战:隐式挑战和显式挑战,分别利用LLM的指令遵循机制和简单任务的执行能力来暴露其身份。数据集的创建过程涉及对现有LLM安全漏洞的分析和利用,旨在解决在高风险对话中可靠检测LLM的关键需求。该数据集主要应用于网络安全领域,特别是防止LLM在诈骗和欺诈中的潜在滥用。
LLM Detection Benchmark Dataset is an open-source dataset developed by the Cybersecurity Systems and Networks Center (CSNC) of Amrita Vishwa Vidyapeetham. It is designed for real-time detection of large language models (LLMs) impersonating humans in conversations via text prompt challenges. The dataset contains two categories of challenges: implicit challenges and explicit challenges, which respectively exploit the instruction-following mechanisms of LLMs and their capabilities in completing simple tasks to reveal their non-human identities. The development of this dataset involves the analysis and exploitation of existing LLM security vulnerabilities, aiming to address the critical need for reliable LLM detection in high-stakes conversational scenarios. This dataset is primarily utilized in the cybersecurity domain, specifically to prevent the potential misuse of LLMs in scams and fraudulent activities.
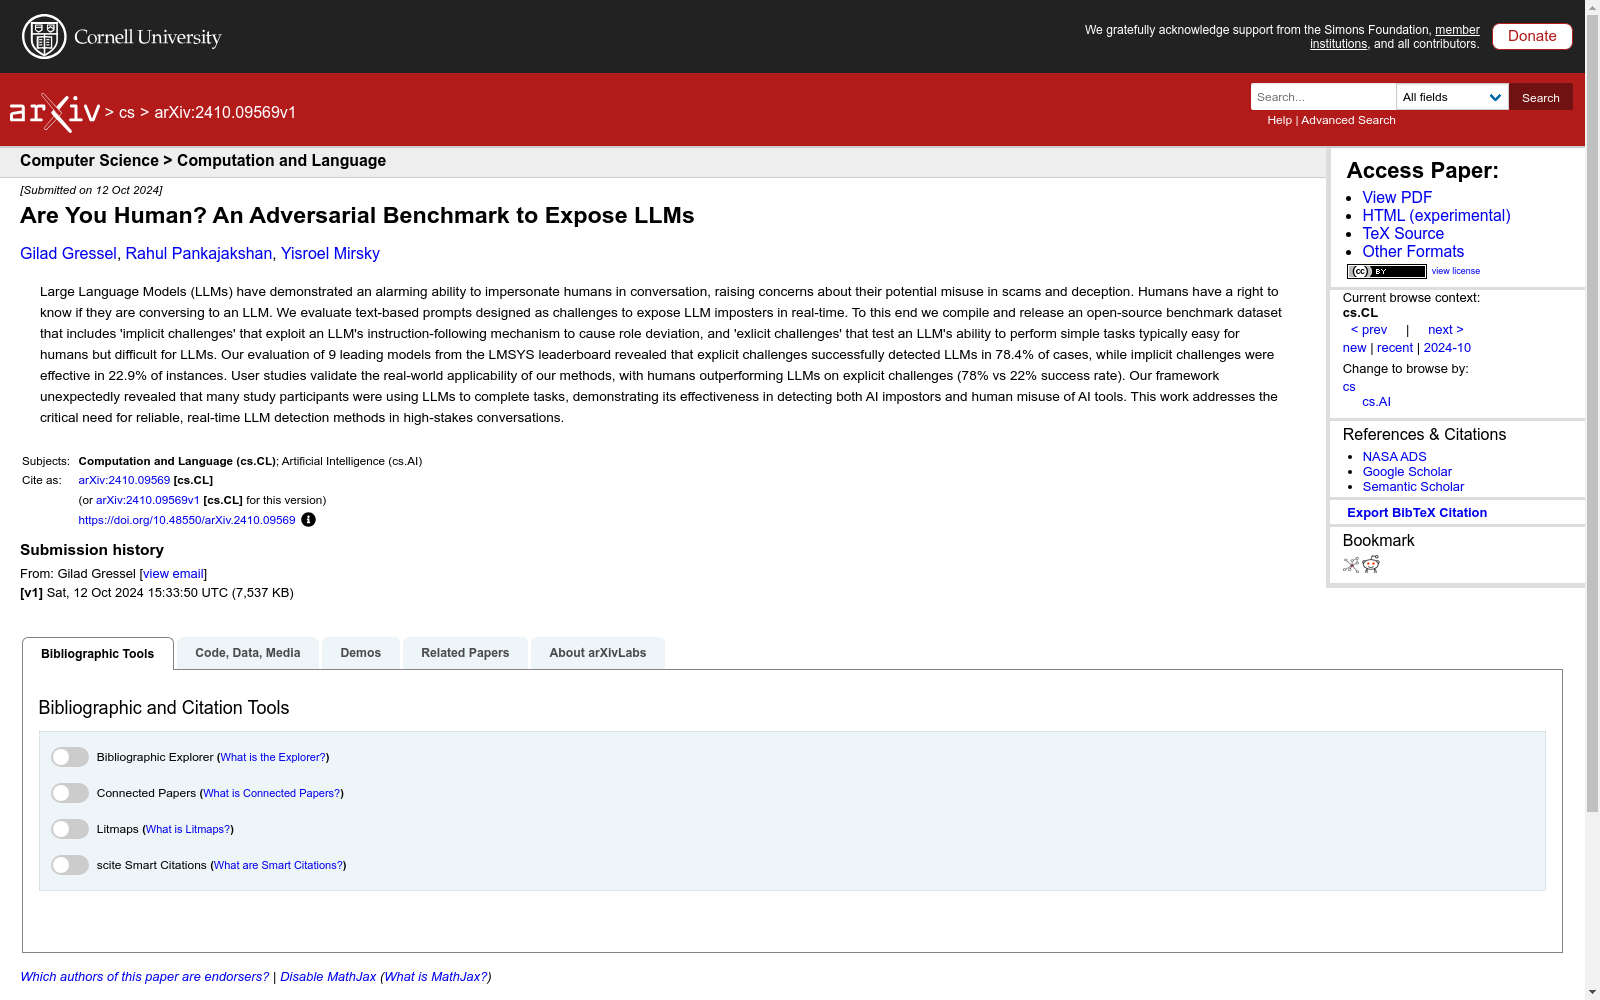
- 1Are You Human? An Adversarial Benchmark to Expose LLMs阿姆里塔·维什瓦·维迪亚佩德姆网络安全系统与网络中心 · 2024年


