sample-thai
收藏资源简介:
该存储库包含一个工具和经过清理的JSONL文本数据样本,旨在提高数据质量,使其更适合各种自然语言处理(NLP)任务。清理过程的主要目标是去除噪声、标准化格式并提高信噪比,从而使数据更适合用于训练、微调和评估机器学习模型。数据集来源于Hugging Face数据集`ChavyvAkvar/fineweb-2-1M-Sample-Thai`,并经过HTML标签去除、URL去除、空白字符标准化、非打印字符过滤和Unicode替换字符去除等清理步骤。清理后的数据格式为JSONL,包含文本内容及其元数据,如唯一标识符、文本哈希、文本长度、原始URL、域名、URL路径、日期、语言代码、清理时间戳等。该数据集适用于语言模型预训练、微调、文本分类、信息检索和数据分析等用途。
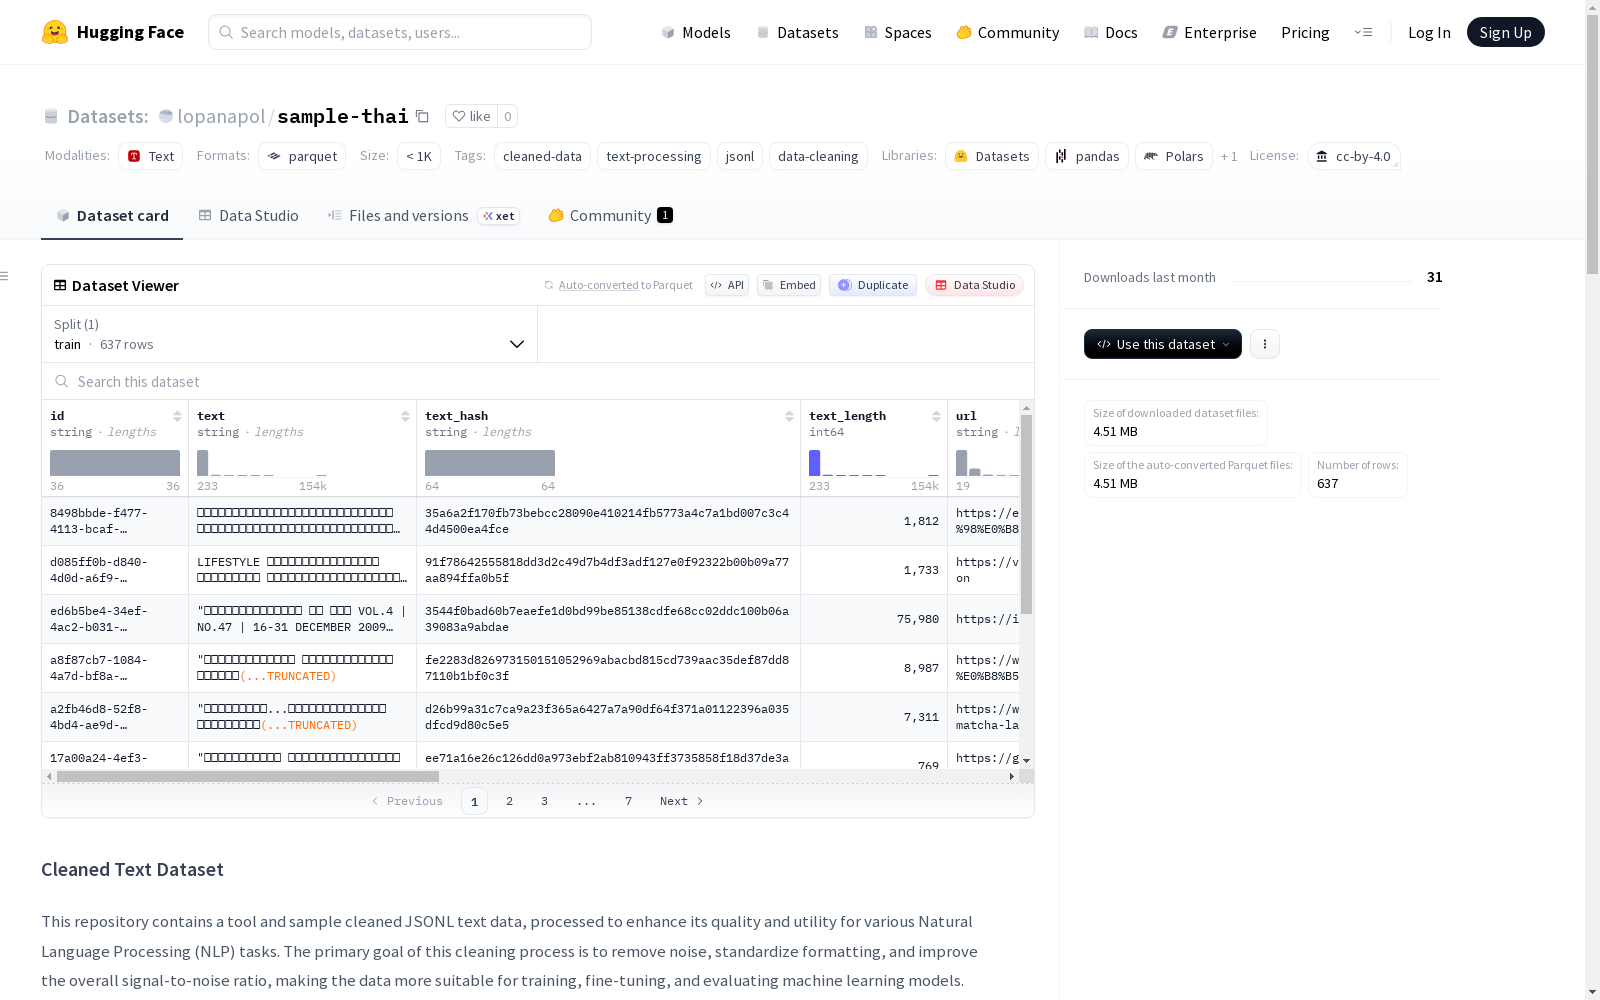
This repository includes a utility tool and cleaned JSONL text data samples, developed to improve data quality and make it more suitable for a wide range of natural language processing (NLP) tasks. The core objectives of the data cleaning process are to remove noise, standardize formats, and increase the signal-to-noise ratio, thus making the data more appropriate for training, fine-tuning, and evaluating machine learning models. The dataset is derived from the Hugging Face dataset `ChavyvAkvar/fineweb-2-1M-Sample-Thai`, and has undergone a series of cleaning steps such as HTML tag removal, URL elimination, whitespace standardization, non-printable character filtering, and Unicode replacement character removal. The cleaned data is formatted as JSONL, containing text content and its associated metadata including unique identifiers, text hashes, text lengths, original URLs, domain names, URL paths, dates, language codes, cleaning timestamps, and other relevant fields. This dataset is applicable for scenarios like language model pre-training, fine-tuning, text classification, information retrieval, and data analysis.
数据集概述
基本信息
- 数据集名称: Cleaned Text Dataset
- 托管地址: https://huggingface.co/datasets/lopanapol/sample-thai
- 许可证: cc-by-4.0
- 标签: cleaned-data, text-processing, jsonl, data-cleaning
数据来源
数据内容与结构
- 数据格式: JSONL
- 数据清洗: 是
- 语言: 主要为泰语(根据
language字段推断,如"tha") - 数据量:
- 训练集样本数: 637
- 训练集大小: 11,617,421 字节
- 下载大小: 4,510,703 字节
- 数据集总大小: 11,617,421 字节
- 数据特征(Features):
id(string): 唯一标识符,已去除"urn:uuid:"前缀。text(string): 清洗后的文本内容。text_hash(string): 文本内容的SHA256哈希值,用于去重和完整性校验。text_length(int64): 文本内容的字符长度。url(string): 原始内容的URL。domain(string): 从URL中提取的域名。url_path(string): 从URL中提取的路径。date(timestamp[s]): 原始数据收集的日期(ISO 8601格式)。language(string): 检测到的语言代码。cleaned_timestamp(string): 执行清洗操作的时间戳(ISO 8601 UTC格式)。source_name(string): 原始数据源的可读名称(可选)。
数据清洗方法
清洗过程通过minimal.py中的clean_text_data函数实现,对每条记录的text字段应用以下转换:
- 移除HTML标签: 清除所有HTML或XML标签。
- 移除URL: 清除以
http://或https://开头的URL。 - 空白字符规范化: 将换行符替换为单个空格,合并连续空格,去除首尾空格。
- 过滤不可打印字符: 移除所有不可打印的Unicode字符。
- 移除Unicode替换字符: 明确移除U+FFFD字符(通常显示为�)。
清洗目的
- 提升模型性能。
- 降低数据噪声。
- 标准化数据格式。
- 增强文本可读性。
潜在用途
- 语言模型预训练。
- 模型微调(如摘要、问答、文本生成)。
- 文本分类。
- 信息检索。
- 数据分析。