MusicSet
收藏资源简介:
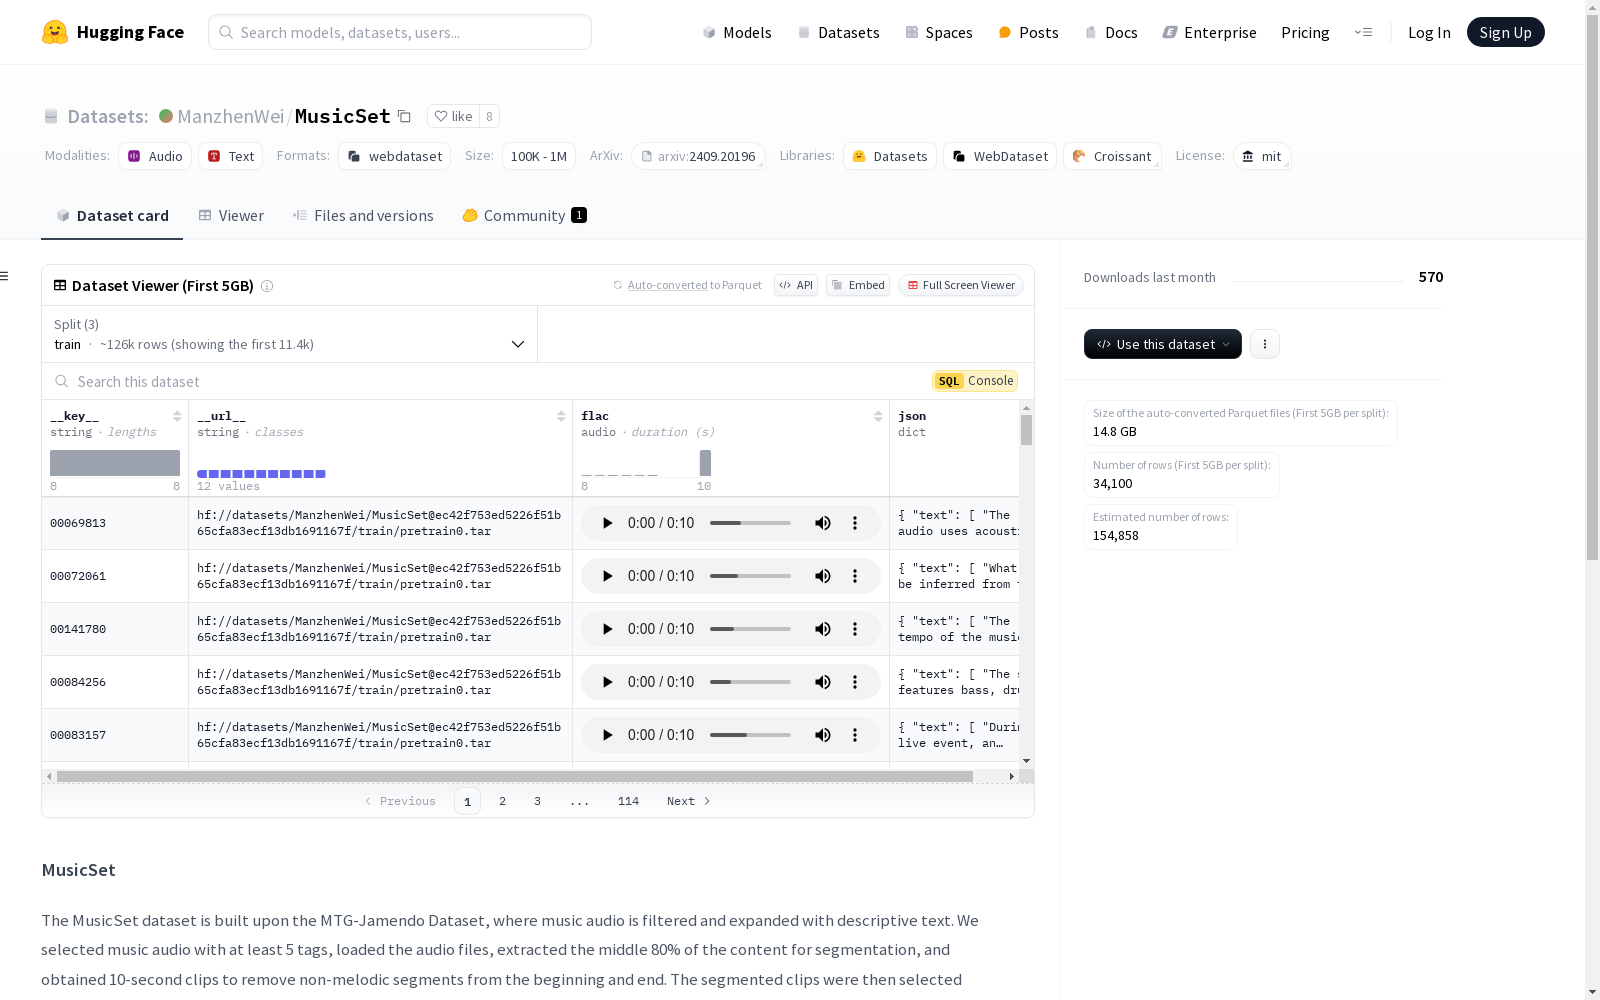
MusicSet数据集基于MTG-Jamendo数据集构建,专注于带有丰富描述文本的音乐音频。该数据集通过选择至少有5个标签的音乐音频,提取音频中间的80%并分割成10秒的片段,去除非旋律部分。这些片段被保存为单独的WAV文件,其描述信息存储在JSON文件中。文本描述通过deepseek API生成,该API学习了musiccaps数据集的文本描述风格,并将多个标签整合成完整的描述。最终的MusicSet数据集包含约150,000个10秒的音乐-文本对,结合了musicbench和musiccaps数据集的元素。
The MusicSet dataset is constructed based on the MTG-Jamendo dataset, focusing on musical audio with rich descriptive texts. It selects audio tracks with at least 5 tags, extracts the middle 80% portion of each selected track, splits the portion into 10-second segments, and removes non-melodic parts. These segments are saved as separate WAV files, and their descriptive information is stored in a JSON file. The text descriptions are generated via the DeepSeek API, which learns the descriptive text style of the MusicCaps dataset and integrates multiple tags into complete, coherent descriptions. The final MusicSet dataset contains approximately 150,000 10-second music-text pairs, incorporating elements from both the MusicBench and MusicCaps datasets.
MusicSet 数据集
概述
MusicSet 数据集基于 MTG-Jamendo 数据集构建,通过筛选和扩展音乐音频并添加描述性文本。数据集包含约 150,000 个 10 秒的音乐-文本对。
数据处理
- 音频筛选:选择至少有 5 个标签的音乐音频。
- 音频分割:加载音频文件,提取中间 80% 的内容进行分割,生成 10 秒的片段,去除开头和结尾的非旋律部分。
- 标签扩展:通过调用 deepseek API,将多个标签扩展为完整的描述文本。
- 数据整合:将生成的音乐-文本对与 musicbench 和 musiccaps 数据集整合,形成最终的 MusicSet 数据集。
数据格式
- 音频文件:保存为单独的 WAV 文件。
- 描述信息:保存为 JSON 文件。
引用
bibtex @article{wei2024melodyneedmusicgeneration, title={Melody Is All You Need For Music Generation}, author={Shaopeng Wei and Manzhen Wei and Haoyu Wang and Yu Zhao and Gang Kou}, year={2024}, eprint={2409.20196}, archivePrefix={arXiv}, primaryClass={cs.SD}, url={https://arxiv.org/abs/2409.20196}, }