
Bulwer-Lytton Fiction Contest Dataset
收藏资源简介:
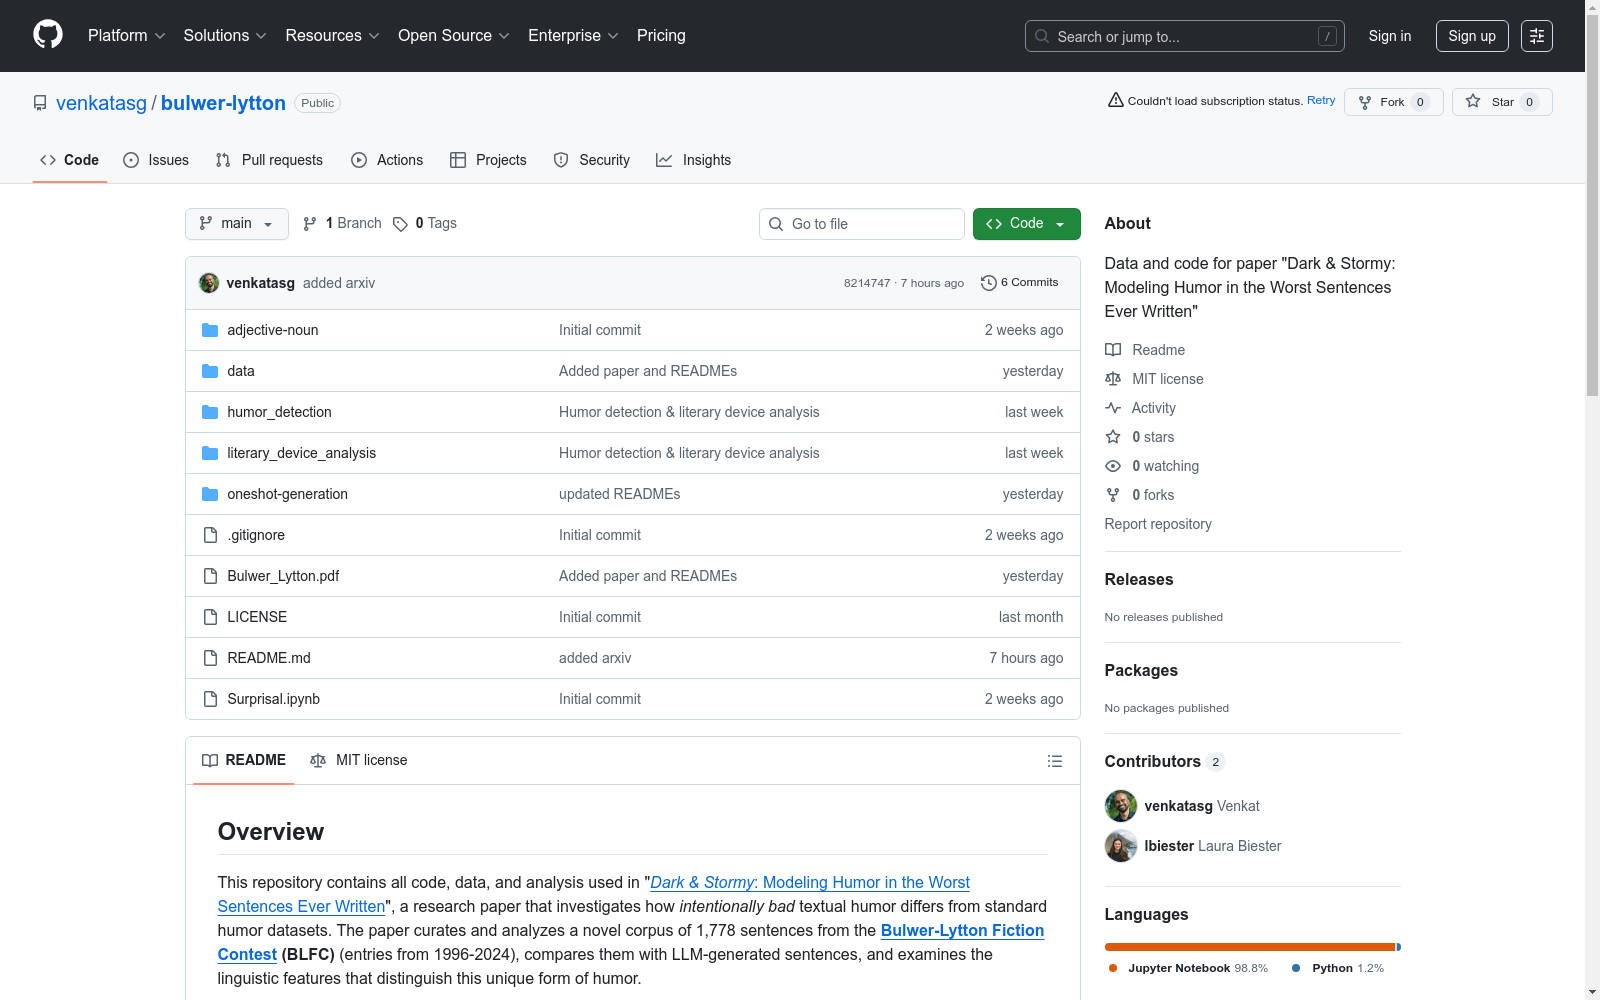
该数据集由伊萨卡学院计算机科学系的Venkata S Govindarajan和Laura Biester创建,包含1778个故意写得很糟糕的幽默句子。数据集来源于Bulwer-Lytton小说大赛,旨在研究这种独特幽默形式的特征,并分析大型语言模型(LLM)生成的句子与人类创作的句子之间的差异。数据集可用于幽默检测、生成和编辑等自然语言处理任务,旨在解决现有幽默数据集无法充分涵盖的幽默形式问题。
Created by Venkata S Govindarajan and Laura Biester from the Department of Computer Science, Ithaca College, this dataset comprises 1778 intentionally poorly-written humorous sentences. Derived from the Bulwer-Lytton Fiction Contest, it is intended to explore the characteristics of this unique form of humor and analyze the discrepancies between sentences generated by large language models (LLMs) and those authored by humans. This dataset supports natural language processing tasks including humor detection, generation and editing, and aims to address the gap where existing humor datasets fail to sufficiently cover this specific type of humor.
数据集概述
数据集来源
- 数据来源于布尔沃-利顿小说竞赛(BLFC)1996-2024年的参赛作品
- 包含1,778条人工撰写的句子
研究背景
- 研究论文《Dark & Stormy: Modeling Humor in the Worst Sentences Ever Written》分析了故意糟糕的文本幽默与标准幽默数据集的差异
- 比较了人工撰写句子与LLM生成句子的特征差异
主要发现
- 标准RoBERTa幽默检测模型在BLFC句子上表现不佳
- BLFC句子相比标准幽默数据集更频繁使用反讽、元小说、隐喻和明喻等文学手法
- BLFC句子包含更多语义偏离的形容词-名词二元组(10%的BLFC形容词-名词在DCLM语料库中出现次数少于100次)
- LLM能够模仿BLFC幽默形式,但会过度夸张其特征
- BLFC句子的惊奇值分布模式与标准幽默数据集不同
数据集内容
- Bulwer-Lytton.tsv:1,778条人工撰写的BLFC参赛作品
- LLM.txt:来自各种LLM的合成句子
研究限制
- 仅关注单一形式的故意糟糕幽默(BLFC参赛作品)
- 幽默检测模型可能无法完全捕捉幽默复杂性
- 文学手法分析仅限于GPT-4识别的8个特征
- 惊奇值分析未通过人工标注直接暗示幽默位置
- LLM评估侧重于风格差异,而非主观质量判断
引用信息
@misc{govindarajan2025darkstormymodeling, title={Dark & Stormy: Modeling Humor in the Worst Sentences Ever Written}, author={Venkata S Govindarajan and Laura Biester}, year={2025}, eprint={2510.24538}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2510.24538}, }
- 1Dark & Stormy: Modeling Humor in the Worst Sentences Ever Written伊萨卡学院计算机科学系 · 2025年


