VerboVision/dados_sinteticos_metodologia_bert_20_pct_combinado
收藏资源简介:
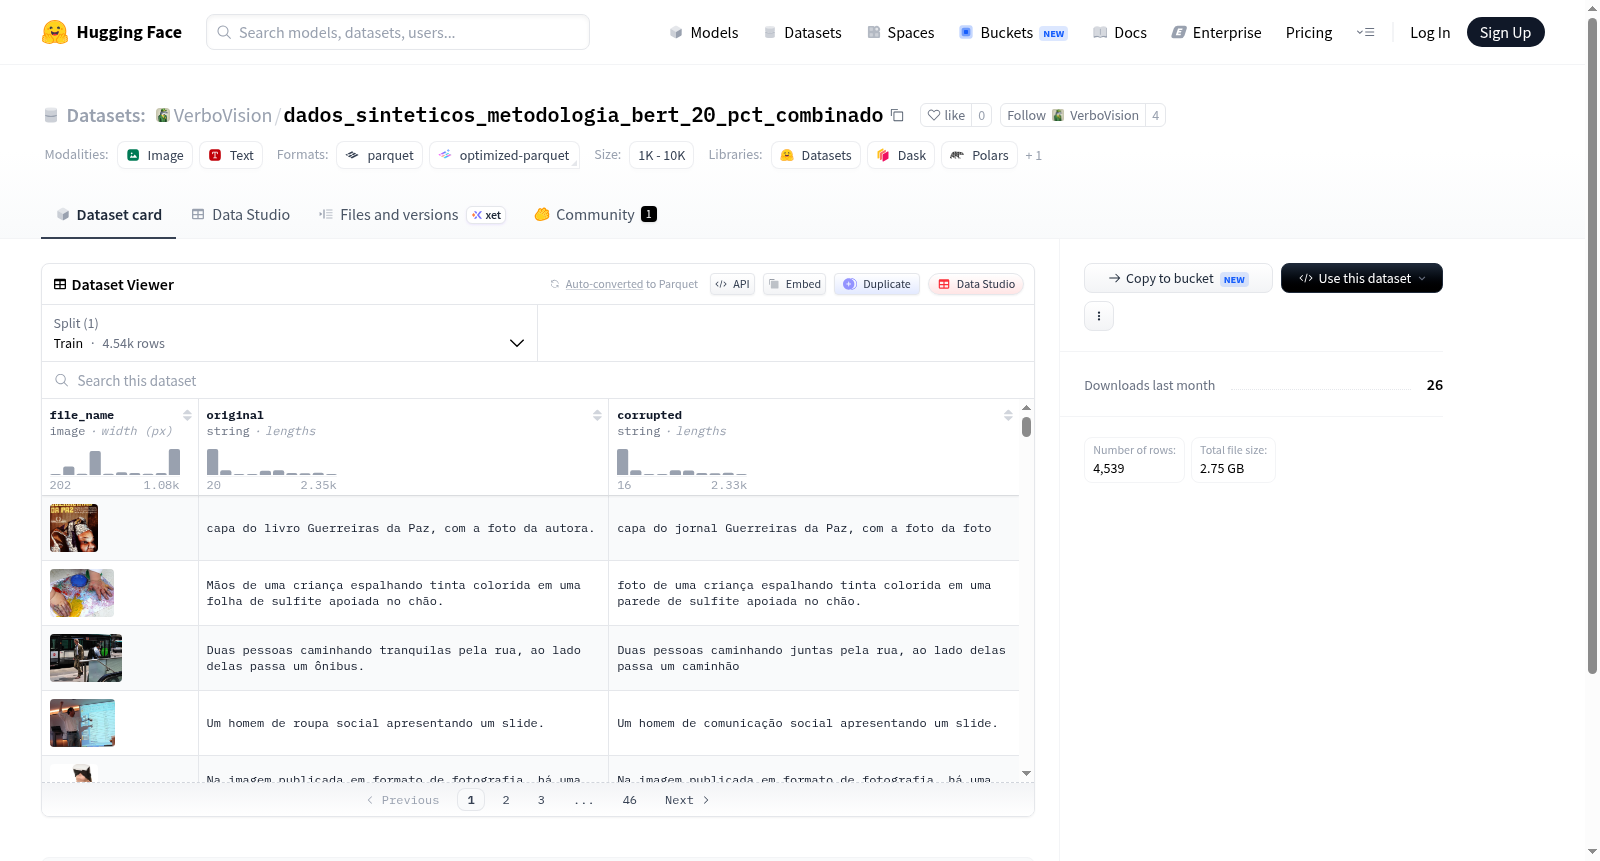
该数据集是一个包含图像和字符串配对的数据集,主要用于处理图像与文本关联的任务。数据特征包括file_name(图像文件名)、original(原始文本字符串)和corrupted(损坏或修改后的文本字符串),可能用于文本修复、图像-文本匹配或数据增强等应用。数据集仅包含一个训练集(Train),共有4539个样本,总数据大小约为2.75 GB,下载大小约为2.75 GB。数据文件位于默认配置的路径data/Train-*下。
This dataset is a paired dataset containing images and text strings, primarily intended for image-text association tasks. Its data features include file_name (image file name), original (original text string), and corrupted (damaged or modified text string), which can be applied to scenarios such as text restoration, image-text matching, or data augmentation. This dataset only contains one training subset (Train), with a total of 4539 samples. The total data size is approximately 2.75 GB, and the download size is also about 2.75 GB. The data files are located under the default configured path data/Train-*.