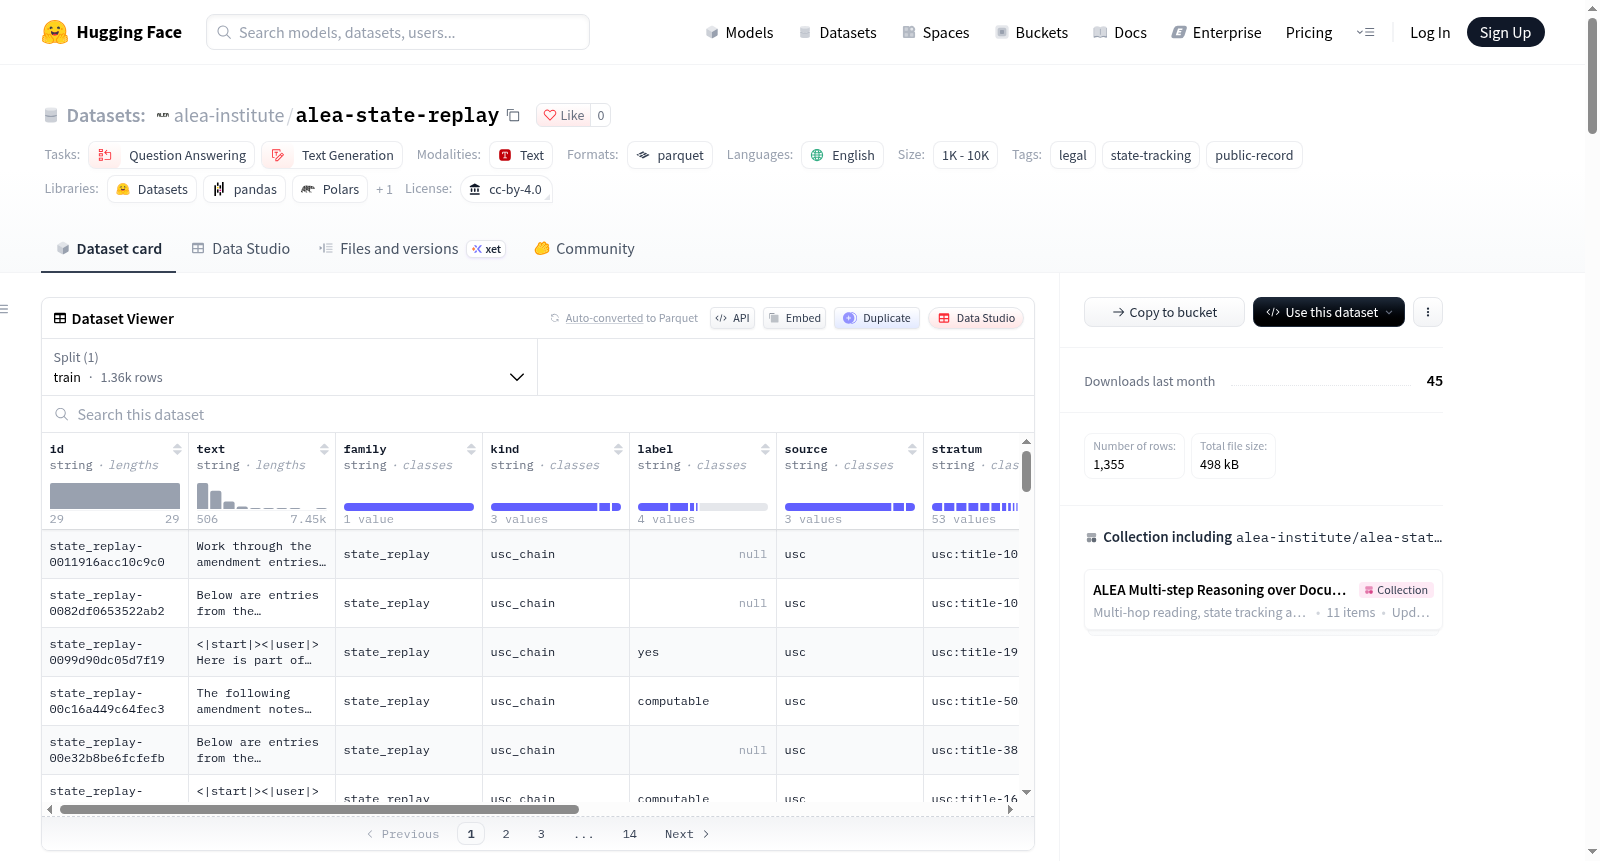
alea-state-replay
收藏资源简介:
ALEA state_replay 是一个面向多步状态跟踪的法律领域数据集,许可证为 CC-BY-4.0,语言为英语,任务类别包括问答和文本生成,标签包括 legal、state-tracking、public-record,规模类别为 1K<n<10K。每个示例展示一段真实法律更新序列,问题需要按顺序应用若干更新才能回答。数据不含任何语言模型生成内容:条目逐字引用,问题由人工撰写,答案通过代码回放序列计算。示例覆盖四类来源:联邦法院 docket(15-60 个连续条目,问题涉及给定条目后哪些动议仍待决、待决数量、某动议在某条目后是否仍待决、哪个条目裁定某动议或最后裁定的动议;规则为动议自提交起待决,直到按其 docket 编号被命令裁定);美国法典修正历史(3-6 个关联条目,每步用新数值替换旧数值,如金额、日期、年份、计数);联邦公报修正链(3-6 个连续最终规则指令,通过 remove X and add in its place Y 修改同一 CFR 条款);CFR 年度版本(同一段落出现在 4-8 个年度版本中,其中一个数值随时间变化)。跨修正来源的问题包括:所有变化后的数值;给定年份或给定版本之后的数值;数值变化次数;哪部法律、规则或版本设定了某数值;某时点的 yes/no 检查。条目可按最旧在前、最新在前或打乱列出,重排条目会标记年份或日期。部分文档省略一段 docket 条目、一个修正或一个版本,省略标记位于真实位置;依赖省略项的问题回答为 cannot be determined 并给出理由,不依赖者正常回答;约 40% 含省略文档包含不可判定问题,它们在一到三个问题中含零、一或两个此类问题,且每个不可判定问题也在另一个显示完整序列的文档中有答案。约四分之一回答会在最终 Answer: 行前逐步回放序列。README 修订部分说明 2026-10-31 第二遍发布移除了 docket_state 文档:全量从 2,571 篇、2,991,233 tokens 降至 1,355 篇、688,734 tokens;保留 usc_chain 1,112 篇、cfr_editions 130 篇、fr_chain 113 篇。移除为仅检测删除,整行丢弃,剩余行与原始发布逐字节一致,早期版本仍在数据集历史中;卡片其他位于修订部分之外的计数和数字描述原始完整集,除非另有重述。发布版本包括 Release 1(重建):1,840 篇、2.20M tokens;Release 2(新增):731 篇、0.80M tokens,且 Release 2 行绝不与 Release 1 共享 group。两个 release 合计的公开记录文本来自 KL3M 语料:CourtListener / RECAP 联邦 docket 条目 1,216 篇(47.3%);美国法典 Amendments notes(2023 版及 2018/2012/2008/2004/2000/1994 版)1,112 篇(43.3%);CFR 年度版本 1996-2023 共 130 篇(5.1%);联邦公报最终规则 2000-2023 修正指令 113 篇(4.4%)。每个 release 内,任何法院、美国法典标题、CFR 标题或机构均不超过文档的 4.9%。答案生成方面,docket 使用严格规则读取动议和裁定,并丢弃含部分裁定、多请求动议、错误提交/重新提交/撤销、解析器不计的类动议文件、仅注明或推迟动议的命令、未命名编号却似裁定的命令等窗口;修正链要求每一步旧值等于上一步新值,美国法典最终值对照法条文本检查,CFR 段落除一个变化数值外必须跨版本一致。cannot be determined 答案占全部问题的 7.1%,仅在省略项可改变答案时给出;yes/no 答案在变化点两侧成对出现。原始规模为 2,571 篇文档、3.0M tokens(alea-v2b-sw32k),worked responses 占 27%;问题类型计数为:某时点数值或状态 2,010;某时点 yes/no 1,775;变化次数或待决动议数量 1,005;哪一步/法律/版本/条目 894;最终状态 587。质量检查包括:仅问题分类器(词袋模型,5 折分组)在每个带标签问题类型上距多数先验不超过 4.1 个百分点;捷径基线接近或低于先验,包括回答首个或最后提及的数值、pending unless some order mentions the motion、omission marker means cannot be determined(85.5% 对 92.8% 先验)、motion filed just before omission means cannot be determined、按问题数量预测弃答;代码检查包括有序列表中省略标记位于真实位置(0 违规)、无 gap 文档使用 shown/listed 规则表述、答案无占位文本;还进行了去污染检查(对照 ALEA 评估套件和留出集,1.5% groups 的留出探针集不在此发布中)和人工审查(超过 150 篇文档逐一手工回放答案,两个 release 每轮独立盲审 60 篇,并额外检查 30 篇重写的 gap 规则;发现的问题均通过收紧生成器修复)。已知问题(2026-10-31)指出,docket_state 文档(原始 2,571 篇中的 1,216 篇,47.3%)带有标签线索:在 22 个只看到部分输入的检查中 14 个被猜对,且判断 docket gap 是否重要的规则仅从 gap 就能复现 82% 标签;该章节称集合尚未更改,并计划用 hard negatives 重新生成。README 的修订部分称 docket_state 已在第二遍中移除,而 Known issues 仍描述其存在且未更改,卡片内部存在版本说明不一致。局限包括:docket 条目保留 CM/ECF 措辞和缩写;pending 遵循所述规则(需要编号命令),可能与实际案件处理不同;修正链仅覆盖通过简单替换改变的数值;源文本按印刷保留,包括历史 CFR 版本中的偶发拼写错误。
ALEA state_replay is a legal-domain dataset for multi-step state tracking, licensed under CC-BY-4.0, in English, with task categories of question answering and text generation, tags legal, state-tracking, and public-record, and size category 1K<n<10K. Each example shows a real sequence of legal updates, and the questions must apply several updates in order to be answered. The data contains no language-model-generated content: entries are quoted verbatim, questions are human-written, and answers are computed by code replaying the sequences. Examples cover four source types: federal court dockets (15-60 consecutive entries; questions ask which motions remain pending after a given entry, the number pending, whether a motion remains pending after a given entry, which entry resolved a motion, or the last resolved motion; the rule is that a motion is pending from filing until an order resolves it by docket number); United States Code amendment histories (3-6 linked entries, each step replacing an old value with a new value such as amount, date, year, or count); Federal Register amendment chains (3-6 consecutive final rule directives that modify the same CFR provision via remove X and add in its place Y); and CFR annual editions (the same paragraph appearing in 4-8 annual editions, with one numeric value changing over time). Questions across amendment sources include: the value after all changes; the value at or after a given year or edition; the number of changes; which law, rule, or edition set a value; and yes/no checks at a point in time. Entries may be listed oldest-first, newest-first, or shuffled, and reordered entries are marked with year or date. Some documents omit a docket entry, an amendment, or an edition, with the omission marker at the true position; questions that depend on the omitted item are answered cannot be determined with a reason, while independent questions are answered normally; about 40% of documents with omissions contain undeterminable questions, having zero, one, or two such questions among one to three questions, and every undeterminable question also has an answer in another document showing the full sequence. About one quarter of answers replay the sequence step by step before the final Answer: line. The revision section notes that the 2026-10-31 second pass removed docket_state documents: the full set dropped from 2,571 documents and 2,991,233 tokens to 1,355 documents and 688,734 tokens; retained are usc_chain 1,112, cfr_editions 130, and fr_chain 113. Removal was detect-only, dropping whole lines; remaining lines are byte-for-byte identical to the original release, and earlier versions remain in dataset history; other counts and numbers on the card outside the revision section describe the original full set unless otherwise restated. Release versions include Release 1 (reconstructed): 1,840 documents and 2.20M tokens; Release 2 (new): 731 documents and 0.80M tokens, with Release 2 rows never sharing a group with Release 1. Across both releases, public-record text comes from the KL3M corpus: CourtListener / RECAP federal docket entries 1,216 (47.3%); United States Code Amendments notes (2023 edition and 2018/2012/2008/2004/2000/1994 editions) 1,112 (43.3%); CFR annual editions 1996-2023, 130 (5.1%); and Federal Register final rule amendment directives 2000-2023, 113 (4.4%). Within each release, no court, U.S. Code title, CFR title, or agency exceeds 4.9% of documents. For answer generation, docket uses strict rules to read motions and resolutions and discards windows with partial resolutions, multi-request motions, erroneous filing/refiling/withdrawal, motion-like documents not counted by the parser, orders merely noting or deferring a motion, and orders that look like resolutions without named numbers; amendment chains require each steps old value to equal the previous steps new value; U.S. Code final values are checked against statutory text; and CFR paragraphs must be consistent across editions except for one changed numeric value. cannot be determined answers make up 7.1% of all questions and are given only when an omitted item can change the answer; yes/no answers appear in pairs around change points. Original size was 2,571 documents and 3.0M tokens (alea-v2b-sw32k), with worked responses at 27%; question-type counts are: value or status at a point 2,010; yes/no at a point 1,775; number of changes or pending motions 1,005; which step/law/edition/entry 894; final status 587. Quality checks include: a question-only classifier (bag-of-words, 5-fold grouped) within 4.1 percentage points of the majority prior on every labeled question type; shortcut baselines close to or below the prior, including answering the first or last mentioned value, pending unless some order mentions the motion, omission marker means cannot be determined (85.5% versus 92.8% prior), motion filed just before omission means cannot be determined, and predicting abstention by question count; code checks include omission markers at true positions in ordered lists (0 violations), no-gap documents using shown/listed rule wording, and no placeholder text in answers; decontamination checks against the ALEA evaluation suite and held-out sets (held-out probe sets for 1.5% of groups are not in this release); and human review (over 150 documents with manually replayed answers, 60 independently blind-reviewed documents per release round, plus 30 rewritten gap-rule checks; all found issues were fixed by tightening the generator). Known issues (2026-10-31) state that docket_state documents (1,216 of the original 2,571, 47.3%) contain label cues: 14 of 22 checks seeing only partial input were guessed correctly, and the rule for deciding whether a docket gap matters reproduces 82% of labels from the gap alone; that section says the set has not yet been changed and plans to regenerate with hard negatives. The README revision section says docket_state was removed in the second pass, while Known issues still describes it as present and unchanged, so the card has an internal version inconsistency. Limitations include: docket entries preserve CM/ECF wording and abbreviations; pending follows the stated rule (requiring a numbered order) and may differ from actual case handling; amendment chains cover only numeric values changed by simple replacement; and source text is preserved as printed, including occasional typographical errors in historical CFR editions.
ALEA state_replay 数据集概述
数据集页面:https://huggingface.co/datasets/alea-institute/alea-state-replay
基本属性
- pretty_name:ALEA state_replay
- 许可证:cc-by-4.0
- 语言:en
- 任务类别:question-answering、text-generation
- 标签:legal、state-tracking、public-record
- 大小类别:1K<n<10K
数据集描述
- 每个示例展示真实更新序列。
- 问题必须按顺序应用多个更新才能回答。
- 无语言模型撰写该数据任何部分。
- 条目逐字引用,问题使用手写措辞,每个答案通过代码重放序列计算。
修订信息(2026-10-31,第二轮)
- 移除
docket_state文档,共 1,216 个。 - 原因:
docket_state类型未通过检查。评审者仅查看部分输入时猜标签,22 个中 14 个正确;其标签遵循 gap rule,可从 gap 复现 82% 标签。其他类型(US Code、CFR、Federal Register chains)通过检查。 - 移除为仅检测:整行按规则删除,未编辑文本;每个剩余行与最初发布行字节一致。
- 早期版本仍保留在数据集历史中。
- README 中其他地方描述全集的计数和数字,除非在该修订段重述,否则指原始发布。
| scope | documents before | documents after | tokens before | tokens after |
|---|---|---|---|---|
| all | 2,571 | 1,355 | 2,991,233 | 688,734 |
按 kind:
| kind | before | after |
|---|---|---|
docket_state |
1,216 | 0 |
usc_chain |
1,112 | 1,112 |
cfr_editions |
130 | 130 |
fr_chain |
113 | 113 |
示例覆盖内容
Federal court dockets
- 来自地区法院 docket 的 15-60 个连续条目。
- 问题包括:
- 给定条目后哪些动议仍待决;
- 有多少待决;
- 动议 K 在条目 M 之后是否仍待决;
- 哪个条目裁定了某动议,或最后裁定了哪个动议。
- 每个 prompt 中均说明规则:动议从提交起待决,直到有命令按其 docket number 裁定。
U.S. Code amendment histories
- 来自某 section 的 Amendments note 的 3 到 6 个链接条目。
- 每个条目用新数值替代前一个数值(金额限制、日期、年份、计数)。
Federal Register amendment chains
- 3 到 6 个连续 final-rule 指令,通过“removing X and adding in its place Y”修订同一 CFR provision。
CFR annual editions
- 一段文字如 Code of Federal Regulations 的 4 到 8 个年度版本中印刷内容,其中一个数值随时间变化。
三类修订来源的问题
- 所有变更后的数值;
- 给定年份时的数值,或给定版本之后版本中的数值;
- 数值变更了多少次;
- 哪部法律、规则或版本设定了某数值;
- 某一时间点的 yes/no 检查。
条目按从旧到新、从新到旧(如 Code 中印刷)或打乱列出;重新排序的条目会标记年份或日期。
含省略条目的文档
- 一些文档省略一段 docket 条目、一个 amendment 或一个 edition。
- 当列表有序时,省略标记位于被省略项的真实位置。
- 含 docket gap 的 prompts 说明省略条目可能包含 orders,且每个动议最多被裁定一次。
- 答案依赖省略项的问题回答为“cannot be determined”,并给出原因。
- 不依赖省略项的问题正常回答。
- 约 40% 含省略的文档包含不可确定问题。它们在 1 到 3 个问题中包含 0、1 或 2 个此类问题。
- 每个不可确定问题也在另一个展示完整序列的文档中回答。
- 约四分之一响应在最终
Answer:行前逐步重放序列。
发布版本
- Release 1(重建):docket 和 U.S. Code 行被重新生成,含更清晰的省略 docket 条目规则措辞、更严格的 docket 过滤、更多样化的 omission 文档:1,840 documents,2.20M tokens。
- Release 2(新增):新增来自 CFR annual-edition chains、Federal Register amendment chains、Release 1 未使用的 U.S. Code chains、Release 1 未使用的 dockets:731 documents,0.80M tokens。
- Release 2 的行从不与 Release 1 共享同一 group。
来源
来自 KL3M corpus 的公共记录文本(两个发布合并):
| source | docs | share |
|---|---|---|
| CourtListener / RECAP federal docket entries | 1,216 | 47.3% |
| U.S. Code Amendments notes(2023 release 及 2018 / 2012 / 2008 / 2004 / 2000 / 1994 editions) | 1,112 | 43.3% |
| CFR annual editions 1996-2023 | 130 | 5.1% |
| Federal Register final rules 2000-2023(amendatory instructions) | 113 | 4.4% |
- 在每个 release 内,任何法院、U.S. Code title、CFR title 或 agency 不超过文档的 4.9%。
答案生成方式
Dockets
- 动议和裁定按严格规则读取。
- 含以下内容的窗口被丢弃:
- partial rulings;
- 含多个请求的 motions;
- 标记为 filed in error、refiled 或 stricken 的 filings;
- parser 不计入的 motion-like filings;
- 注明或推迟动议而非裁定动议的 orders;
- 看似裁定动议但未指名其 number 的 orders。
Amendment chains
- 每一步的旧值必须等于前一步的新值。
- U.S. Code 最终值对照 statute text 检查。
- CFR 段落在各版本中必须相同,除发生变化的那个数值。
其他
- “Cannot be determined”答案占所有问题的 7.1%。
- 仅当省略项可改变答案时给出。
- Yes/no 答案在变化点两侧成对出现。
规模
原始发布规模:
- 2,571 documents,3.0 million tokens(alea-v2b-sw32k)。
- Worked responses:27%。
| question type | count |
|---|---|
| value or state at a point | 2,010 |
| yes/no at a point | 1,775 |
| count of changes or of pending motions | 1,005 |
| which step / law / edition / entry | 894 |
| final state | 587 |
检查
Question-only classifiers
- 对问题文本使用 bag of words,5-fold grouped:对每个带标签问题类型,均在多数先验的 4.1 个百分点内。
Shortcut baselines
均接近或低于其先验:
- 用最先或最后提到的值回答;
- “除非某 order 提及该 motion,否则为 pending”;
- “omission marker 意味着 cannot be determined”(85.5% vs 92.8% prior);
- “紧接 omission 前提交的 motion 意味着 cannot be determined”;
- 根据问题数量预测 abstention。
Code checks
- 有序列表中的 omission markers 位于真实位置(0 violations)。
- 无 gap document 使用“shown / listed”规则措辞。
- 答案中无 placeholder text。
Decontamination
- 已对照 ALEA evaluation suites 和 held-out sets 检查。
- 一个 held-out probe set(1.5% of groups)不属于本次发布。
Review
- 超过 150 个文档被阅读,每个答案均手工重放。
- 两个 release 均进行每轮 60 个文档的独立盲审,另加 30 个文档检查重写的 gap rule。
- 发现的问题均通过收紧 generator 修复:
- 与所述规则冲突的 abstentions;
- parser 跳过的 motion types;
- 位置错误的 omission markers;
- question-count 和 position cues。
- 最终轮未发现严重问题。
已知问题(2026-10-31)
docket_state文档(2,571 中的 1,216,47.3%)带有 label cue:在 22 个评审者仅看到部分输入的检查项中,14 个被正确猜出。- 决定 docket gap 是否 material 的规则仅从 gap 即可复现 82% 标签。
- 该集合尚未被更改。
- 计划发布带 hard negatives 的重新生成版本。
限制
- Docket entries 保留 CM/ECF 措辞和缩写。
- “Pending”遵循所述规则(需要 numbered order),可能与案件实际处理方式不同。
- Amendment chains 仅覆盖通过简单替换变化的数值。
- 源文本按印刷保留,包括历史 CFR 版本中的偶发拼写错误。