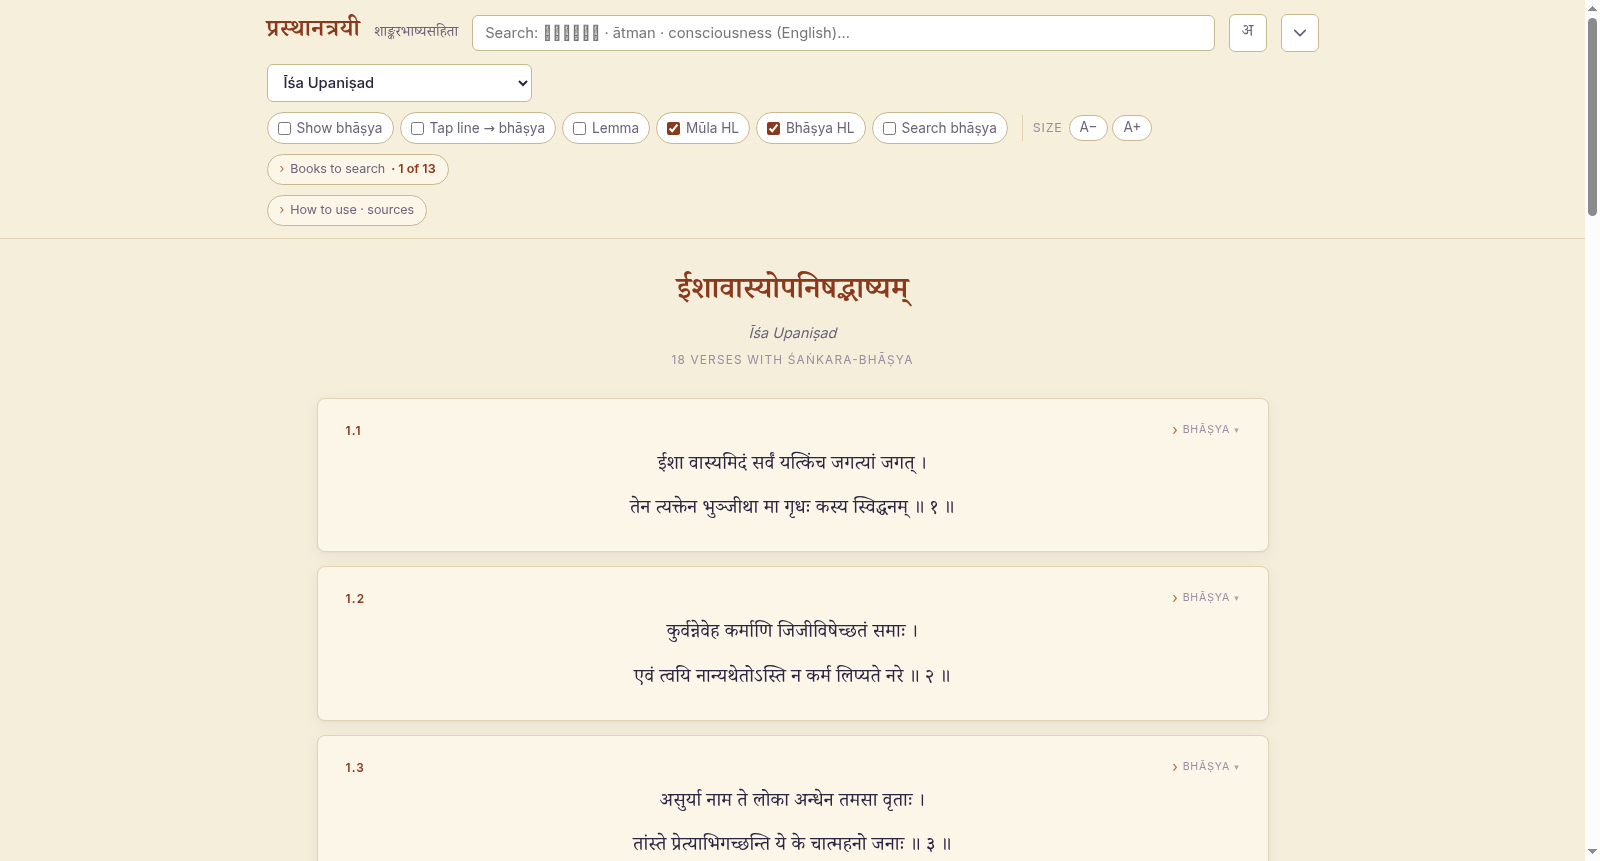
Prasthānatrayī with Śaṅkara’s Bhāṣya 数字语料库
收藏资源简介:
该数据集是由罗摩克里希那传道会·维韦卡南达教育与研究学院创建的《Prasthānatrayī with Śaṅkara’s Bhāṣya》数字语料库,涵盖吠檀多哲学经典文本及其注释的全面数字化版本。数据集包含13个注释单元,总计2,971个可寻址的经文、偈颂和散文段落,其中注释层包含95,587个独特的表面形式,根本文本层包含36,881个经过分析的词汇出现次数,构成了规模庞大的梵语语言学资源。创建过程采用混合分析流程,结合基于规则的连音拆分引擎、92.7万词形屈折词典和大型语言模型辅助分析,并经过对抗性双重验证协议和人工专家审查循环的严格质量控制。该数据集主要应用于数字人文学科和计算梵语研究领域,旨在为学习者提供词级可查询的阅读辅助工具,解决古典梵语文本因连音结合和复杂语法结构导致的阅读困难问题,同时作为开放式教育资源支持学术研究和教学应用。
This digital corpus entitled "Prasthānatrayī with Śaṅkara’s Bhāṣya" was developed by the Ramakrishna Mission Vivekananda Educational and Research Institute, encompassing fully digitized versions of classical Vedānta philosophical texts and their accompanying commentaries. The dataset consists of 13 annotation units, with a total of 2,971 addressable sūtras, gāthās, and prose passages. The annotation layer holds 95,587 unique surface forms, while the core text layer includes 36,881 analyzed lexical occurrences, constituting a large-scale Sanskrit linguistic resource. The corpus was built using a hybrid analytical pipeline that integrates a rule-based sandhi splitting engine, a 927,000-word inflectional lexicon, and large language model-aided analysis, with stringent quality control implemented via an adversarial dual validation protocol and iterative manual expert review cycles. This dataset is primarily applied in the fields of digital humanities and computational Sanskrit research. It aims to provide learners with word-level queryable reading assistance tools to address reading difficulties arising from sandhi combinations and complex grammatical structures in classical Sanskrit texts, while serving as an open educational resource to support academic research and pedagogical applications.